Normal view

Developer vibe codes a tool to let Nvidia RTX 50-series laptop owners crank up their power limits — can juice RTX 5090 mobile GPU to 225W

Folks with Nvidia-based gaming laptops can now use a new tool called NvpwrControl to unlock additional performance from their assuredly power-limited mobile GPU, as long as they're willing to accept the risks of cranking their GPU power limit by as much as 40 watts. The tool, spotted by VideoCardz, is available for download on GitHub, and it is labeled as 'experimental', so you'll want to be very sure you're willing to damage the reliability, if not the lifespan, of your fancy discrete GPU gaming laptop before using it.

If you've ever had a gaming laptop, you will know that the GPU model name can be deeply misleading. Whether it's NVIDIA using wildly different GPU configurations, AMD using confusing suffixes that don't exist in desktop GPUs, or Intel naming integrated graphics like a discrete GPU, all three vendors do things to keep the user guessing why their new gaming laptop isn't as fast as expected based on the name alone.

NVIDIA GeForce RTX 50 Series Laptop GPU Power Limits

GPU Name

GPU Power (varies per laptop)

Dynamic Boost Max

Mod Max (Experimental)

GeForce RTX 5050 Laptop

35 - 100W

15W

140W

GeForce RTX 5060 Laptop

45 - 100W

15W

140W

GeForce RTX 5070 Laptop

50 - 100W

15W

140W

GeForce RTX 5070 Ti Laptop

60 - 115W

25W

180W

GeForce RTX 5080 Laptop

80 - 150W

25W

225W

GeForce RTX 5090 Laptop

95 - 150W

25W

225W

In Nvidia's case, the GPU models (aside from the RTX 30 Series) don't match at all between laptop and desktop, but even with the smaller size of the laptop GPUs, the chips are still sharply limited in performance by their stringent power limits. These limits top out at 150W, with an extra jolt, usually 25W, available from Dynamic Boost if the CPU isn't heavily loaded. This is, frankly put, not enough power for even the mobile GeForce RTX 5070 Ti to stretch its legs, to say nothing of the GeForce RTX 5080 Laptop or GeForce RTX 5090 Laptop. In high-intensity gaming situations, these GPUs can score pretty similarly due to having the same power limit.

That's what makes this tool attractive. By cranking the power limit, you can give these power-limited GPUs a performance boost. The developer doesn't provide any benchmarks, but I can say from experience that testing power limit adjustments on a power-limited GPU can give nearly linear performance gains, meaning that increasing the power limit from a stock 140W all the way up to 180W could potentially give a GPU performance uplift in the neighborhood of 25% or more, although it is impossible to verify this without testing.

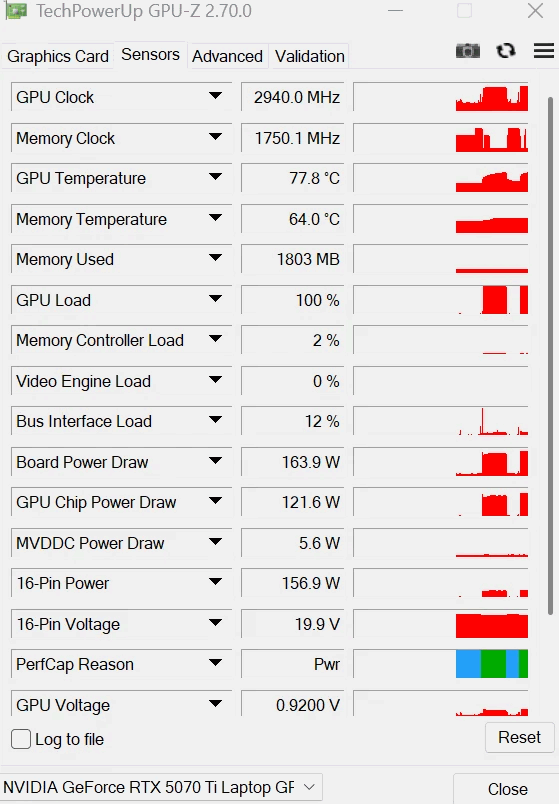
There are quite a few caveats to this utility, though. For one thing, even the author describes it as 'experimental ', and for another thing, it's clearly AI-generated in the largest part. The developer is called "LevinAI", after all, and there are the hallmarks of generative AI all over the GitHub repository. Still, there are a few reports on both GitHub and Reddit suggesting that users have been testing it, and the developer claims that it works on his GeForce RTX 5070 Ti laptop, posting the proof below.

A screenshot of the GPU-Z utility showing a board power draw of 163.9 watts on a GeForce RTX 5070 TI Laptop.

The developer's screenshot of GPU-Z, showing a board power draw of 163.9 watts on a GeForce RTX 5070 TI Laptop, well above the stock 140W cap. (Image credit: /u/Ecstatic_Hamster2208 on Reddit)

Other notable qualifiers include that it only supports Blackwell GPUs for now, and it only enables power controls when it can recognize the power policy layout and OEM baseline. If your GPU already ships with a wacky power configuration, this tool may not work for you. It's also not verified to work on every brand of laptop nor every model of GeForce RTX 50-series GPU, so we absolutely wouldn't try this unless you're willing to replace your Blackwell-based laptop.

The partially AI-generated project description (likely chosen as the author's native language appears to be Russian) explains that the developer investigated numerous layers of the software stack on top of the GPU to see where the power limit could be modified. The controls that NVIDIA exposes generally won't let the user raise the power limit above the value set by the OEM for fear of potentially damaging the hardware, since the power delivery and cooling mechanisms were likely not designed with the higher power draw and thermal output in mind.

The solution he found was apparently to modify a low-level NVIDIA power policy that isn't normally exposed to end-users. He says, "One of the important findings was that the power-management chain contains internal policy values that are not exposed through the normal consumer power-limit controls. This is the path that eventually led to a working experimental implementation." However, due to the method employed, the tool does require the user to disable Windows driver signature verification, which is yet another 'gotcha' of the mod.

A screenshot of the NvpwrControl utility showing its interface.

(Image credit: /u/Ecstatic_Hamster2208 on Reddit)

As amusing as it is to see that the developer left his AI assistant's instructions for constructing his GitHub repository (which he didn't follow), it's a reminder both of the reliability concerns around "vibe"-coded software in production as well as of the incredible potential of AI software development. Since we spotted the story on this utility, the developer has already bumped the version from 1.5.0 to 1.8.0 with a new release on GitHub, suggesting that the pace of improvements is extremely rapid.

A few users on Reddit, where the author posted the above screenshot, lambasted the developer for taking ownership of what they claim is "100% AI generated work" and also for not structuring his code repository correctly (since all of the source is packed in a ZIP file, not properly viewable on GitHub). However, the majority of other users seem enthusiastic about his work, and several have already posted proof that it seems to work, with huge gains in 3DMark and other benchmarks.
Piecemakers bets edge AI devices will diverge from reliance on HBM — custom-designed memory fuses DRAM stack directly to the processor using hybrid bonding

PieceMakers, a Nanya-backed DRAM designer, began trading on Taiwan’s Emerging Stock Board on September 16 at a NT$740 reference price, Cnyes reported ahead of the debut. PieceMakers is not an HBM company. Instead, it bets that inference memory diverges from training memory, President Lee Hsiao-wen told Cnyes, and that DRAM stacked directly on the processor with hybrid bonding can sit between Nvidia’s SRAM-only Groq LPU and HBM. As it stands, design fees, not chips, carry the company's profit, with AI custom-design work accounting for around 40% of the company's revenue in the first half of 2026. Piecemakers Chairman Joseph Ting told TechNews that its first volume customer program will not contribute to the company's financials until 2027 at the earliest.

At roughly 60.4 million shares outstanding, that price values the company at around NT$44.7 billion (around $1.4 billion). Taiwan's Emerging Board is the Taipei Exchange's pre-listing market, not a main-board IPO, so shares trade through market makers ahead of any formal listing application. The stock ended its first session at NT$915, 23.6% above the NT$740 reference price, after opening at NT$1,035 and trading as high as NT$1,205.

Nanya Technology is the largest holder of Piecemakers, at 33.96%, after selling 715,000 shares at NT$740 to seed the float, a disposal it disclosed in a Sept. 9 exchange filing reported by Knews.

What PieceMakers sells

PieceMakers was founded in January 2006 in Hsinchu, Taiwan, led by chairman Joseph Ting and president Lee Hsiao-wen. Historically, the company has designed standard SDR/DDR DRAM and known-good-die (KGD) parts through representatives in China, Japan, France, Turkey, and Israel. Now, the company seeks to shift from direct product sales to custom design services, paid as non-recurring engineering (NRE) fees, and then to IP licensing, royalties, and turnkey production from 2027, the company said at its Sept. 7 briefing, UDN reported.

Revenue from the AI custom design unit has risen from around 4% in 2024 to almost 40% in the first half of 2026. The products behind that increase are HBLL (High Bandwidth, Low Latency RAM), a 2D die rated at 144 GB/s that was taped out in 2016 for Intel’s HPC line and published at ISSCC in 2017, and HiBaLL, the 3D-stacked version rated at more than 1 TB/s, the company claims.

The company described its customers to Cnyes as developers of cloud AI inference accelerators, international semiconductor players, and North American customers, with some programs in design and verification, and none named. Qualcomm CEO Cristiano Amon’s Computex keynote backdrop in June listed PieceMakers among Taiwan ecosystem partners, although neither company has defined the relationship. The takeaway is that the profit is in design fees and not chips. The margin curve matches a pre-royalty Non-Recurring Engineering (NRE) business, rather than a traditional memory vendor.

Why Nanya is chasing this instead of HBM

Nanya’s AI-memory strategy is custom and edge rather than HBM3E. PieceMakers is the first half of a strategy laid out in 2024. On Aug. 7, 2025, Nanya announced a joint venture with Etron Technology, a Hsinchu-based chip designer, capitalized at NT$500 million, with 80/20 ownership. The venture was envisioned to design custom high-bandwidth memory for edge AI devices rather than for data center accelerators. Nanya president Pei-Ing Lee said earlier in 2025 that the company would not compete in HBM3 or HBM3E, TrendForce reported.

Both halves of the strategy rely on Formosa Advanced Technologies, the Formosa Plastics Group’s test and assembly affiliate, for packaging. It is building the through-silicon-via (TSV) and die-stacking processes that both need. The surge in DRAM pricing has made commodity memory Nanya’s real business, which leaves PieceMakers a cheap side bet that has become a windfall. Nanya took advantage of this by selling around 3% of its stake in a move that suggests it is acting more as an investor than a parent building a memory stack.

The inference gap

Groq is an AI inference startup that Nvidia struck a $20 billion licensing-and-talent deal for on Dec. 24, 2025. Nvidia announced its first chip built from that, the Groq 3 LPU (language processing unit), Nvidia’s SRAM-based inference chip, at GTC, its annual developer conference, in San Jose earlier this year.

There is no HBM or DRAM on the Groq 3 LPU. Instead, it uses 512MB of SRAM on the die to deliver 150 TB/s of bandwidth against 22 TB/s from the 288GB of HBM4 on each Rubin GPU. It’s a decode-only co-processor with Rubin handling the prompt prefill, displacing Nvidia’s Rubin CPX from the roadmap.

At Hot Chips 2026, Nvidia’s Igor Arsovski, Groq’s former chief architect, said the rack is in production and published the first third-party benchmark: 3,431 tokens per second on a 100K-context, 31B-parameter model, at about four times the next-fastest public endpoint, in a single-request test that we noted isn’t directly comparable to the shared endpoints it was measured against. The cost is capacity: at 512MB per chip, a 256-LPU rack holds 128GB, with the model needing 62 chips at FP8 just to hold the benchmark weights. Nvidia accepted that trade for decode speed, which supports Lee’s point that the market leader’s newest inference product contains no HBM.

At Hot Chips, Samsung’s Sangwook Han laid out a three-phase HBM roadmap that ends in zHBM, which is DRAM stacked directly on top of the processor rather than beside it on an interposer. Samsung projects about 70% less I/O power usage than HBM5 with roughly 2.3x the bandwidth of a four-stack HBM4E system, with zHBM’s stacks limited to about four-high due to heat, at around 100W less. This would require wafer-on-wafer hybrid copper bonding and tight co-design between DRAM and SoC teams. SK hynix’s Jaesik Lee, VP of package engineering, said on Aug. 23 that hybrid bonding won’t be ready for HBM4E, leaving HBM5 as the earliest point. Counterpoint Research expects full-scale HBM production with the technique around 2029–2030.

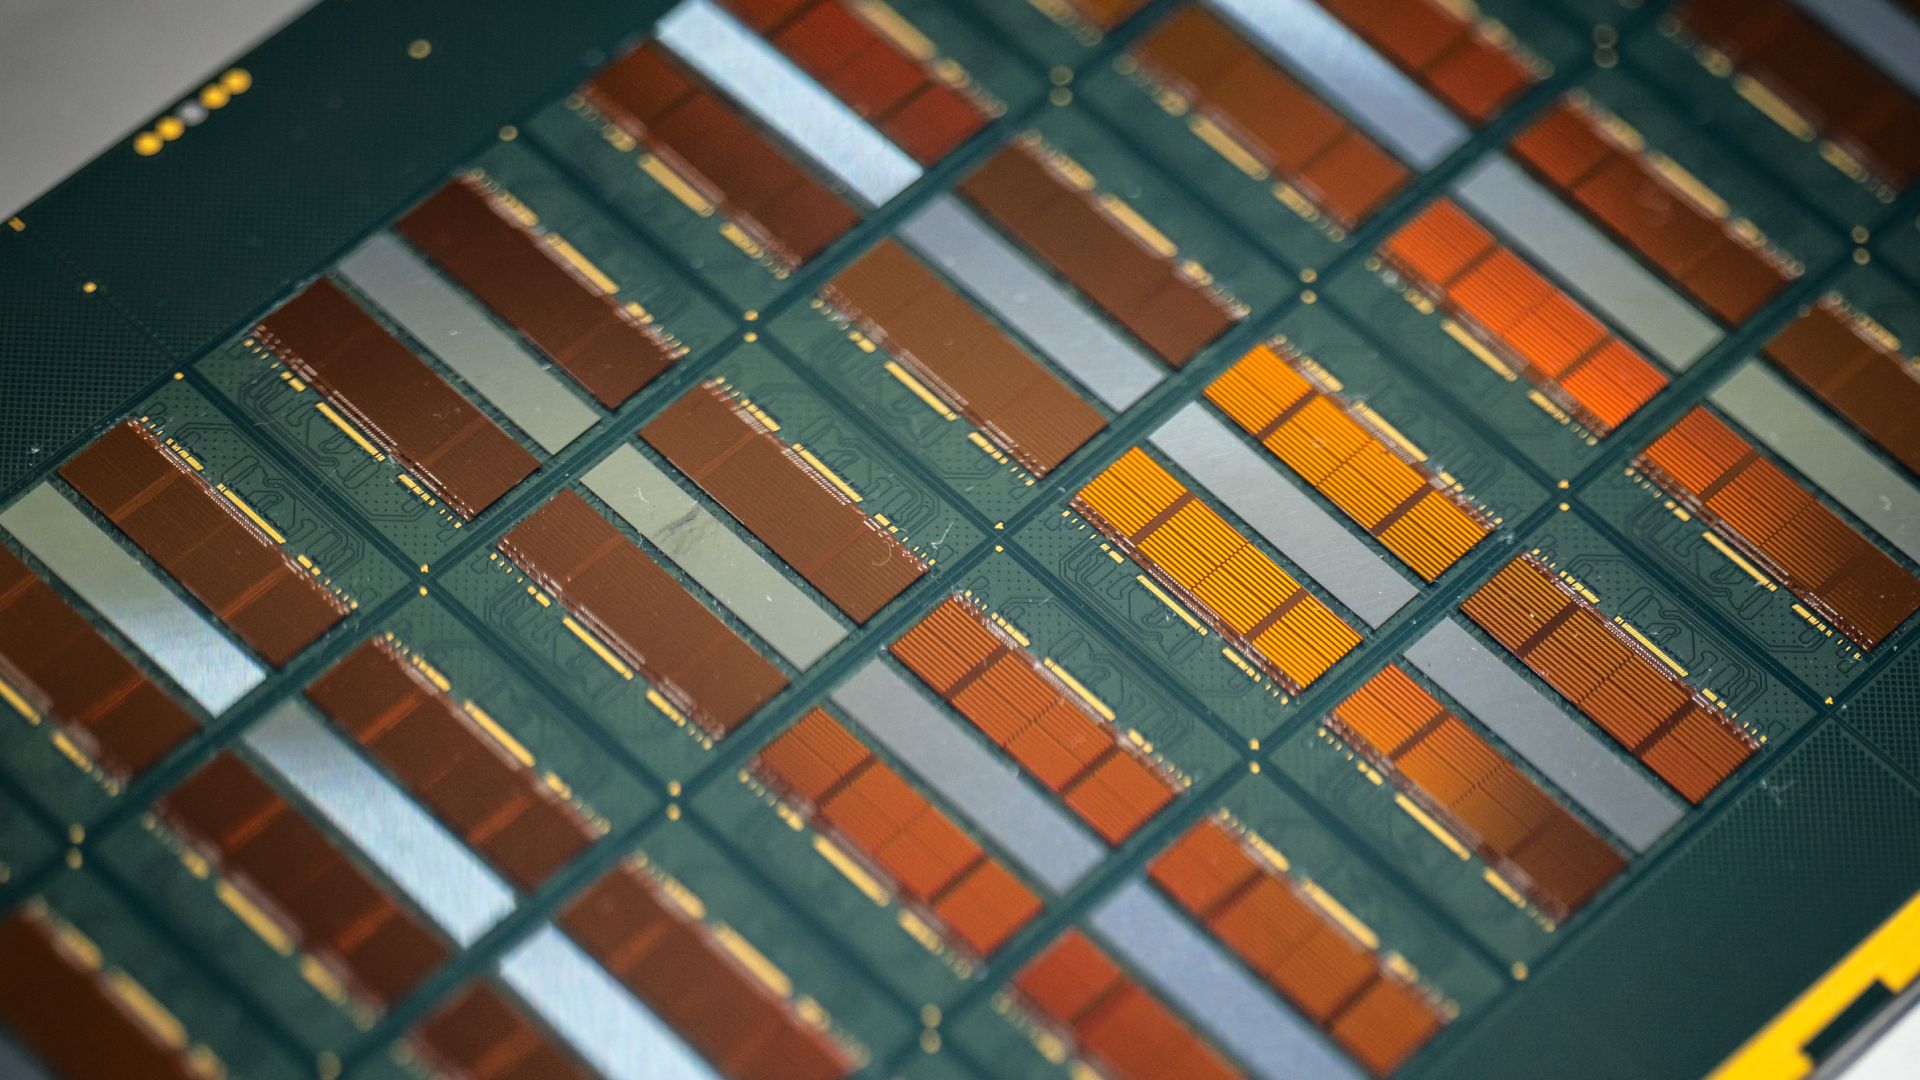
PieceMakers offers a different version. Instead of the GPU-plus-HBM 2.5D layout, it bonds the DRAM stack directly onto the processor, wafer-on-wafer, with hybrid bonding instead of microbumps. This fits far more connections with the finer pitch, improving bandwidth, and the shorter path reduces both latency and power consumption. The company puts its wafer-on-wafer product at more than 2 TB/s per layer with latency under 20ns, the company figures, but the target is more capacity than SRAM at a lower cost and power than HBM. PieceMakers is not doing the TSV or hybrid bonding itself, as this is handled by the customer’s logic wafer foundry, Ting added. This custom service promises a 2027 date against Samsung's undated roadmap end and SK hynix's HBM5-at-the-earliest timing. Nvidia and Samsung have each, in their own way, settled the architecture question, with the open question being the customer.

Yield is the product

Lee also said that yield is the biggest hurdle to wafer-on-wafer mass production. The repair architecture has to be designed in, with testing before bonding, after bonding, and then after logic integration. Lee’s own example was 80% yield per layer, at which four layers come out at about 41% and eight at 17%. Our recently-published hybrid bonding state of play covers the process side in more detail.

This better puts into perspective why the company sells repair and known-good-die IP as much as it does bandwidth. It’s also why an IP-and-royalty model fits the strategy — yield IP is portable across customers while a bandwidth number is not.

What to watch

For PieceMakers, AI revenue remains primarily NRE until there is a first named customer, with the first volume program expected in 2027 at the earliest. Ting said that Nanya’s Q3 2026 results, which come in late October, will gauge the PieceMakers gain and reveal further financial information. SK hynix’s hybrid-bonding timing, which targets HBM5 at the earliest, is the current benchmark, although its 16- and 20-layer memory stacks are a separate problem from a few DRAM layers on a logic wafer. Qualcomm may also describe its relationship with PieceMakers more formally.

PieceMakers is likely to end up as an IP licensor with a small number of accelerator customers and turnkey volume through Nanya and Formosa Advanced Technologies. The technology risk is the foundry’s and the customer’s, which is why PieceMakers’ design-fee model works. PieceMakers is expected to benefit from a 2027–2028 ramp, later than Ting’s 2027. If the largest HBM maker won’t bond its own memory this way before HBM5, PieceMakers’ own 2027 date is the one it must meet.

Denuvo sues anonymous game cracker ‘voices38’ over alleged DRM circumvention — seeks damages after Anti-Tamper protections bypassed in 26 games

Anti-Tamper and DRM (Digital Rights Management) software developer Denuvo is taking its fight against video game piracy to court by filing a lawsuit against the anonymous game cracker known as “voices38.” According to TorrentFreak, the company claims that the accused bypassed its Anti-Tamper technology in at least 26 PC games and is seeking monetary damages as well as a court order that would prevent further tampering of its DRM.

In its lawsuit filed on September 14 in the U.S. District Court for the Northern District of California, Denuvo alleges that the “defendant is a computer hacker who is focused on reverse engineering, hacking, or ‘cracking’ video games employing Denuvo’s Anti-Tamper product. Defendant has bypassed DRM restrictions in copyrighted works, removing protections that allow copyright owners to restrict who may access their works, and allowing for pirated versions of those copyrighted works.” The complaint also named 26 games including popular titles such as Hogwarts Legacy, Black Myth: Wukong, Resident Evil Requiem, and Doom: The Dark Ages.

It is worth mentioning that Denuvo doesn’t actually own the copyrights to any of these games. Meaning that instead of a filing for copyright infringement, the complaint relies on the anti-circumvention provisions of the DMCA. It essentially prohibits bypassing a digital lock that controls access to a copyrighted work, or distributing tools and instructions that help others to bypass copyright protections.

What makes the case interesting is that Denuvo does not know the real identity of voices38. It only points to the defendant as “an unknown individual or entity” alongside ten other unnamed defendants. The complaint also references Reddit and Discord accounts as well as Steam profiles that Denuvo believes may be connected to the cracking activity. The company could eventually seek information from these platforms as part of its legal proceedings.

Voices38 has been particularly active in recent months, with reports pointing to a growing number of Denuvo-protected game cracks to the anonymous cracker. Recent releases include Star Wars: Outlaws, Persona 3 Reload, and Prince of Persia: The Lost Crown. For Denuvo, the lawsuit could lead the way in identifying one of the more active figures in the recent video game-cracking scene. That said, the case is still in its early stages, and Denuvo's allegations have yet to be tested in court.

Micron announces 512GB DDR5-9200 memory modules with 16W power draw — up to 12TB per server, claims 60% less energy-intensive than four 128GB modules

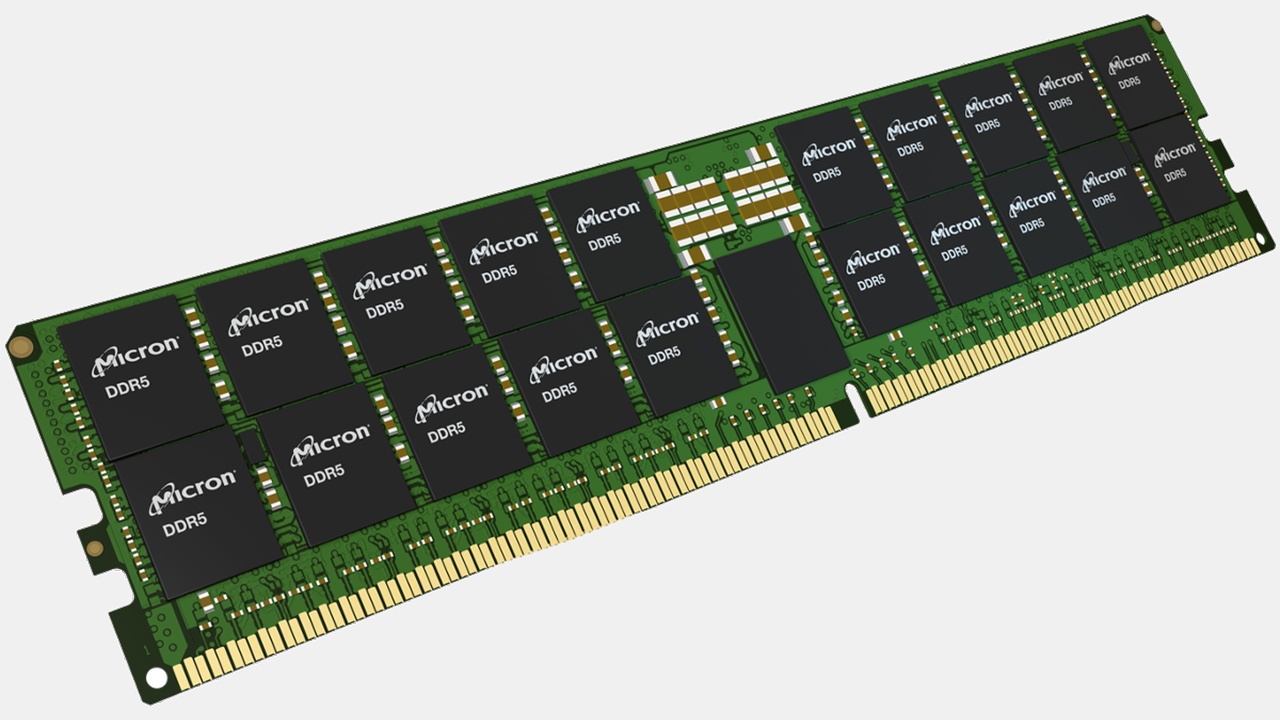
Micron this week introduced its first 512GB DDR5-9200 memory module that is designed for servers used for applications that demand a lot of memory. The new modules — which are currently being validated by AMD and Intel with their next-generation server platforms — will enable server makers to build machines with up to 12TB of fast memory. What remains to be seen is the price of such modules and servers.

To build its 512GB DDR5 RDIMM, Micron uses advanced packaging that stacks multiple DRAM dies vertically and connects them using through-silicon vias (TSVs). The company does not disclose which memory devices and how many of them it uses, but claims that a single 512GB RDIMM consumes over 60% less operating power than four 128GB modules — based on 16.0W for one 512GB module compared with the 44.2W total for four 128GB modules — which suggests that we are dealing with fairly advanced ICs.

Micron's 512GB module is not the industry's first 512GB DDR5 RDIMM — that achievement belongs to Samsung — but it is certainly the industry's first 512GB module certified to operate with a 9200 MT/s data transfer rate with standard 1.1V voltage (which implies on usage of Micron's 16Gb DDR5-9200 devices made on its 1γ (1-gamma) fabrication process that uses EUV lithography and consumes 20% less power than predecessors, though we are speculating).

Truth to be told, 512GB DDR5 memory modules are rather niche products, which is perhaps why Samsung's 512GB RDIMMs formally introduced in 2021 have not become widespread even after AMD and Intel introduced processors with over 100 cores. Micron positions its 512GB DDR5 RDIMM primarily for servers running analytics, in-memory databases, simulations, virtualization, agentic AI, and other workloads demanding high-core-count processors and plenty of memory. As processors with 200 or more cores emerge, 512GB modules may become more relevant as 12TB of memory in a server running two 256-core CPUs means 24GB per core, which no longer looks particularly excessive for applications like in-memory databases, analytics, or caching.

Micron claims that in memory-constrained Spark Support Vector Machine (SVM) analytics workloads, systems featuring 512GB memory modules can provide up to 1.4 times the performance of configurations equipped with 256GB DDR5 modules, though the company does not disclose how much memory in total these systems use. Micron also says the higher-capacity memory can increase throughput and concurrency for memory-intensive database and caching applications such as RocksDB and Redis.

AMD and Intel are working with Micron to qualify the new modules for their upcoming server platforms. Micron plans to begin volume production of its 512GB DDR5 RDIMMs sometime in the second half of 2027 and intends to align the schedule with customer requirements.

One of the more pressing questions about Micron's 512GB DDR5-9200 memory modules is their price. A 256GB DDR5-6400 RDIMM currently retails for around $19,000. Given the unique proposition that 512GB modules have for memory-constrained applications, such modules can cost significantly more than 256GB memory sticks, which will not help their broad adoption.

AI-induced memory shortage is changing how devices are built, Fairphone says memory now 60% of materials cost — smaller laptop and phone makers are redesigning products and have to test for fake chips

With the ongoing memory shortage, smaller smartphone and laptop manufacturers are reportedly looking at new ways to tackle the problem. While some are changing how they design their products, others are placing orders months in advance and are even forced to test incoming memory chips to make sure they are not fake. A Reuters report suggests that more than the price, availability has become a bigger problem, with manufacturers struggling to secure enough chips in the first place. Still, device makers like Fairphone say that memory now makes up nearly 60% of a device's bill of materials.

Back in July, memory maker SK Hynix’s CEO Kwak Noh-jung said that 2027 will be the "worst year" for the ongoing memory shortage and expects the memory crunch to last until 2030. For smaller manufacturers, however, simply paying more for memory isn't always enough. The situation is particularly difficult for budget-oriented phones and laptops, where memory makes up a much larger portion of the overall product cost.

According to Raymond van Eck, CEO of repairable-phone maker Fairphone, memory can account for almost 60% of the bill of materials in phones costing around $400. That itself is worrying, as a recent Counterpoint Research report expects global smartphone shipments to fall 13.9% this year to 1.08 billion units, marking the largest annual decline on record.

Finnish phone maker Jolla has designed two motherboard versions, allowing it to switch between combined packages for discrete chips depending on availability. The company is also testing samples from every batch it receives to ensure new memory isn't being sold as refurbished hardware.

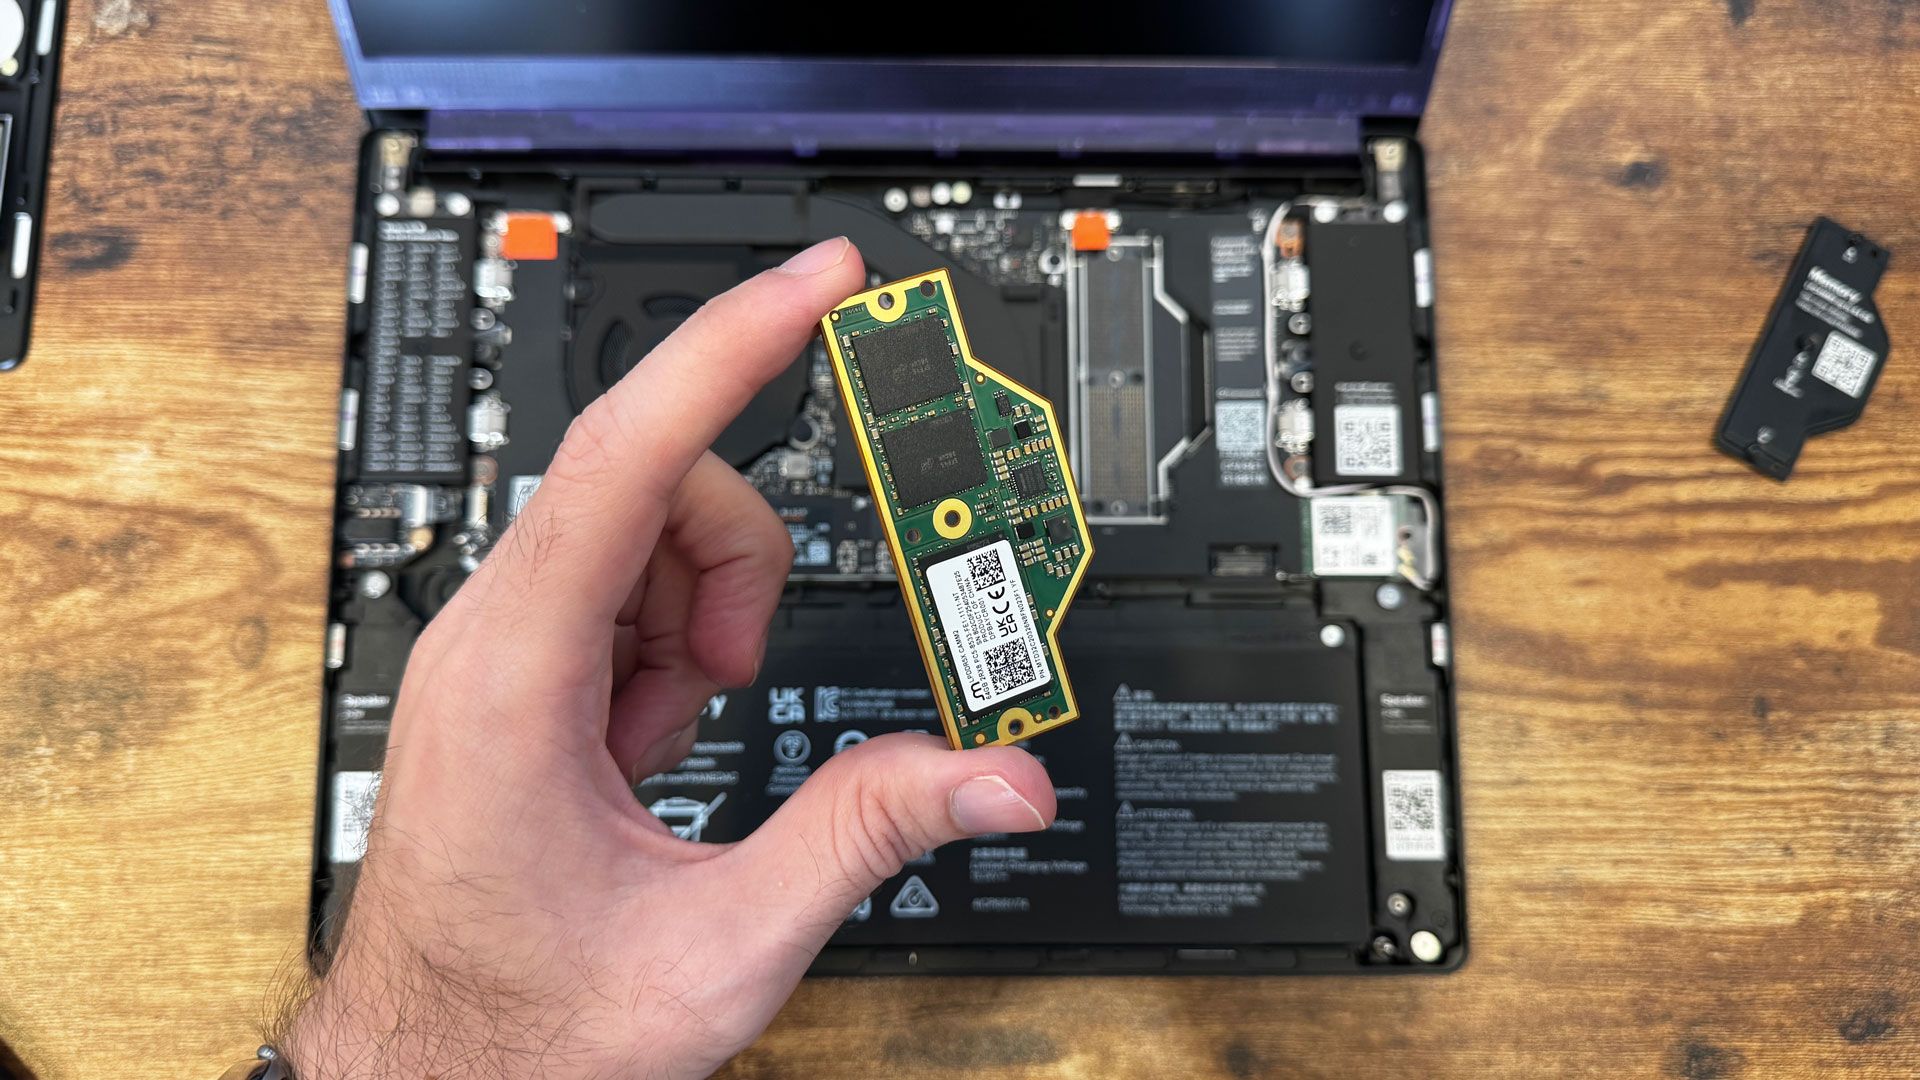
Similarly, laptop manufacturer Framework has been able to rely on its highly modular approach where customers can install memory salvaged from older laptops or opt for second-hand units, giving the company and its users another way to deal with limited supply. The company is also placing non-cancellable orders well in advance, even when it doesn't know the final price or exact delivery volume.

Back in July, it nearly doubled memory pricing for 32GB and 64GB variants of the Framework Laptop 13 Pro after receiving a cost update from its LPCAMM2 supplier. However, after sourcing new inventory at a reduced cost, the company recently announced a price drop for the same, including retroactive orders that have already shipped.

Chinese state media counters Anthropic's call to put brakes on AI development — paper says move is ‘a response to Chinese competition’

China's state-run newspaper has downplayed the call of Anthropic founder Dario Amodei to “pace the frontier.” China Daily, the official English mouthpiece of the Communist Party of China, questioned the move, which was supported by OpenAI CEO Sam Altman and SpaceXAI’s Elon Musk, asking if they were doing it out of concern for humanity or if they’re afraid of competition from China.

“The report, and the corporate ‘alliance’ that followed it, amounted in essence to a coordinated play — a response to Chinese competition and to the regulatory pressure coming from Washington. Its aims were threefold: to blunt China's AI advance, to win a favorable policy environment at home and to keep investors' enthusiasm for US AI alight,” the publication wrote. It further criticized the move thusly: “The proposed coordination among the three companies sounds rather like a club whose membership rules have been drafted before the guest list is announced. A global AI-safety framework that excludes China is not quite global.”

The paper also called out the U.S. efforts in blocking Chinese AI advancement, both through hardware, by blocking Beijing’s access to the latest Nvidia chips, and software, with Amodei’s multiple accusations of illegal distillation of Claude by Chinese AI labs. China Daily said that these efforts have apparently failed, and cited the success of the DeepSeek and Kimi K3 models, which turned out to perform well enough but at a much lower cost.

The availability of those models has resulted in many AI users shifting demand to cheaper tokens, like Kimi K3 (low) and DeepSeek V4 Pro, over the expensive frontier models like Fable 5.1, GPT 5.6 Sol, Grok 4.6, and Kimi K3 (max).

China Daily also took issue with Amodei’s focus on excluding China from his proposal. It suggests that the move is meant to widen the technological gap between the two rivals when it comes to AI technology and give American AI labs breathing room to “pace the frontier,” and that it reveals how Washington sees Chinese AI as an existential threat.

Nevertheless, Chinese policy acknowledges some of the risks that Amodei raised. The Standardization Administration of China, in cooperation with the Cyberspace Administration of China, says that the development of AI technology must be monitored as it may go beyond human control.

“Treating the AI race as a zero-sum game makes the cooperation needed to manage those risks more difficult. China and the US should cooperate where neither can manage the consequences alone,” says the state media outfit. “The planned AI-safety dialogue between the two sides and future high-level exchanges offer opportunities for practical engagement. The promise of AI lies in serving humanity's common good, not in being weaponized for geopolitical gain or instrumentalized for personal profit.”

Nvidia reportedly denies RTX 5090 warranty over faded serial number — $6,500 GPU blemish not an isolated incident, according to customers

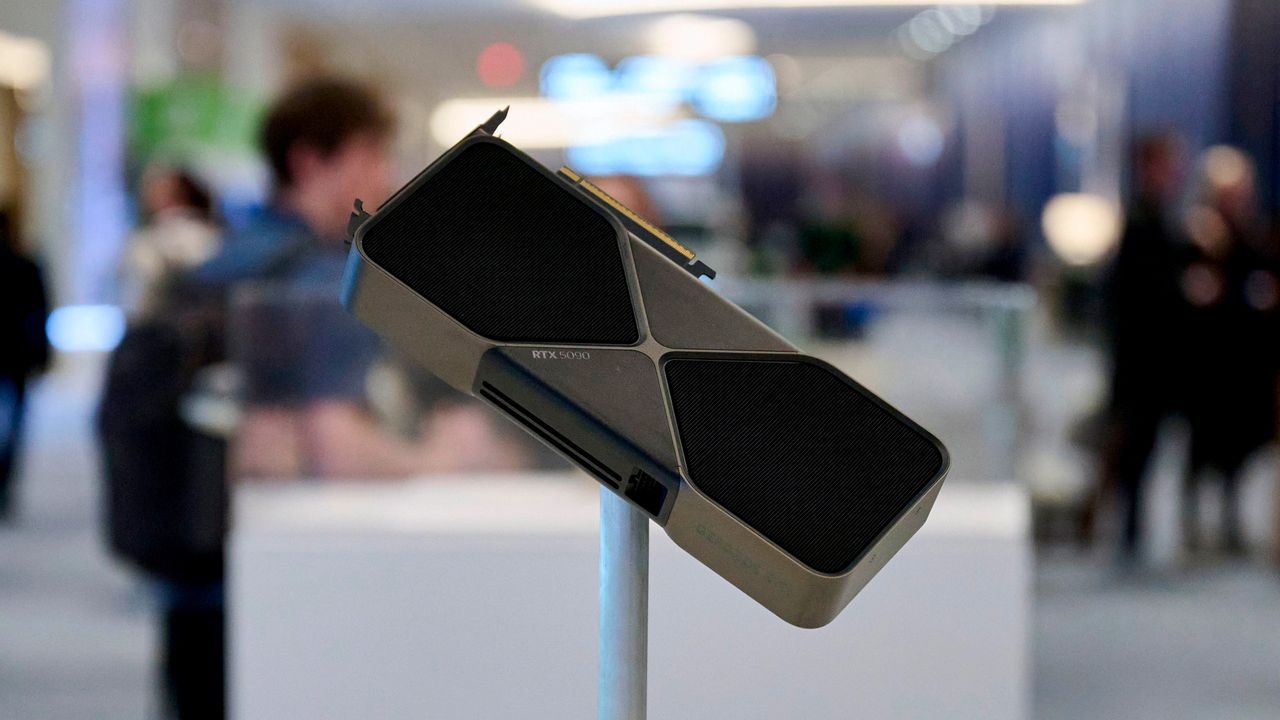
The GeForce RTX 5090 is the first thing that comes to mind when you think of the best graphics cards. However, you'd better pray the serial number on the inside of the metal bracket does not fade over time, since that could be a reason for Nvidia to reject warranty claims. At least one Redditor has shared a case of Nvidia reportedly denying a warranty claim because the bracket's serial number was unreadable.

The Redditor Willing-Avocado-4830, based in the UK, began experiencing black-screen crashes with a GeForce RTX 5090 Founders Edition graphics card under heavy load. The user sent the card to Nvidia for a warranty claim. After 30 days of radio silence, the owner finally received an email stating that their RMA request was rejected with no apparent explanation for the denial.

Seeking clarification, the user reached out to Nvidia for further information. According to the Redditor's recount, Nvidia support purportedly rejected the RMA because the serial number on the graphics card's metal bracket had faded. Like many gamers, Willing-Avocado-4830 claims never to have modified or tampered with the graphics card after installation. The fading serial number does not appear to be an isolated incident. Several other owners have reported similar issues in the Reddit discussion.

The metal bracket on graphics cards is susceptible to dust buildup, oxidation, and corrosion over time. This can cause it to look dirty, stained, or sometimes slightly discolored compared to when it was brand new. These same phenomena could have affected the serial number's legibility, especially since it is printed with ink onto the bracket's surface rather than etched for better durability. For comparison, the last-generation GeForce RTX 4090 Founders Edition had its serial number laser-etched onto the metal bracket.

My RTX 5090 FE RMA was rejected because the physical serial number is no longer readable — has anyone experienced this?
 from r/nvidia

One Redditor said that someone in the Nvidia Discord channel recommended cleaning the area with isopropyl alcohol to restore the serial number's visibility. However, that may not work if the ink is no longer present, as previous reports suggest the hot air expelled by the Founders Edition cooler could be erasing the serial number.

Surprisingly, Nvidia rejected a warranty claim solely because of a faded serial number on the graphics card’s bracket. The same serial number is clearly printed on a sticker on Nvidia's modular PCIe connector, which the chipmaker's technicians can verify when disassembling the GeForce RTX 5090. Moreover, you can pull the serial number from the graphics card through the command prompt with Nvidia SMI (System Management Interface), assuming the card is still working, which, in this case, it is. Willing-Avocado-4830 still had the original packaging and the original invoice from Nvidia U.K., so it would be easy to cross-reference the serial numbers.

Redditor hawok reportedly sent their GeForce RTX 5090 Founders Edition for RMA two months ago and encountered a similar situation. The serial number on the metal bracket was only partially visible. However, customer support seemingly accepted the RMA after the user sent photographs of the packaging that corroborated the serial number. It is unclear what Nvidia's policy is, or whether the chipmaker handles each case differently. We have reached out to Nvidia for clarification.

Some Redditors have suggested taking a photograph that shows the graphics card's serial number next to the packaging's serial number. Others jokingly recommend putting a piece of tape over the serial number. It might not be a bad idea, but you would need heat-resistant tape, something like Kapton tape.

GeForce RTX 5090 stock has practically disappeared from the U.S. market, with very few units starting at $6,500, 3.25X over the Blackwell flagship's MSRP. You cannot blame GeForce RTX 5090 owners for worrying. They already have a lot on their plates, dealing with the 16-pin power connector melting woes, and now also have to worry about fading serial numbers.

Original Sony PlayStation 2 security chip ‘broken wide open’ after 26 years — chemical decapping and four years of reverse engineering unlocks MechaCon secrets

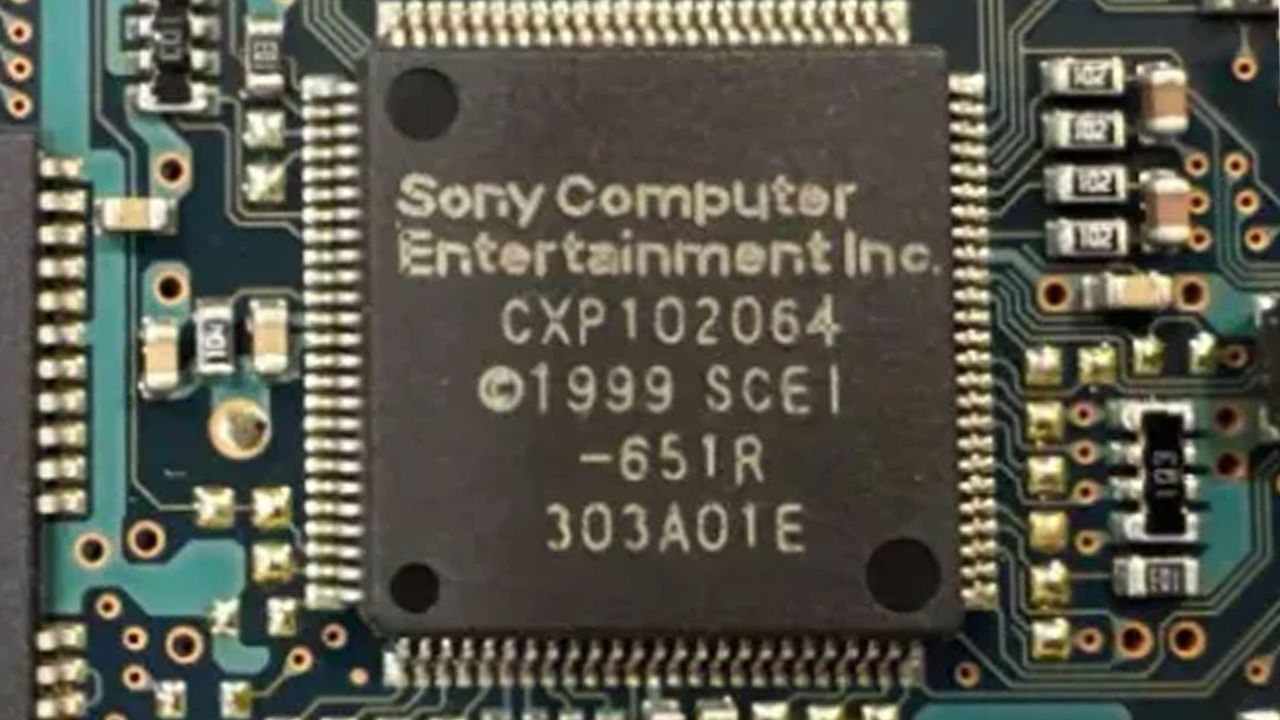
The ‘magic security chip’ inside the original PlayStation 2 has been successfully reverse-engineered and dumped. Canadian retro hardware and software enthusiast DiscoStarslayer was the manic mind behind the cracking open of the CXP102064 MechaCon chip, which arrived inside the ‘PS2 Fat’ from 1999. It took “four years of effort” to reach this stage, but this milestone should be a boon to hardware preservation, repair, and emulation projects.

After 4 years of effort, I'm happy to announce that one of the final secrets of the PS2 has been broken wide open!It's been a long process of decapping, optical dumping, and now at last a software solution.Thank you Libby for finding the exploit from our dirty optical dumps! pic.twitter.com/VrsCH8I35CSeptember 13, 2026

The Mechacon got its name from its primary duty of controlling the PS2’s optical and flash drive mechanics. It also played a significant part in Sony’s game optical disc security, supporting “Magic Gate [memory card] and KELF file [executable] decryption among other things,” notes the PSDev Wiki. Unlocking the secret workings of such chips can be important to those involved in video game preservation. So, many people will appreciate DiscoStarslayer’s work in reverse engineering and dumping one of the PS2’s last remaining secrets.

As per the social media post, the arduous task of breaking the MechaCon’s security took four years. Some of the reverse engineering tricks utilized by DiscoStarslayer include chemically decapping the CXP102064 to expose the die, then using microscopes and optical dumping skills to analyze the silicon chip circuitry. In this case, a lucky break during the hacking apparently uncovered an exploit that provided a method whereby the chip’s data could be extracted through software.

With this achievement unlocked, the game/hardware preservation and programming communities can look forward to improved emulation and homebrew developments. It should also open up possibilities for replacing the aging optical drives in PS2 consoles.

Beyond the confines of PS2 Fat consoles, some social media commenters noted that the MechaCon was also used in a handful of arcade machines from the era. Specifically, the Namco System 246 and System 256, as well as the Konami Python 1, which used modified PS2 hardware, used the MechaCon firmware to authenticate security and allow the execution of encrypted game data.

AI leaders clash over safety fears after Anthropic whistleblower says AI could 'kill us all' by 2030 — OpenAI, Anthropic and xAI figureheads call for external governance, while Jensen Huang says worries are 'made up'

This past week, employees and key figures at leading AI companies have called for a slowdown in the development of frontier AI models, citing warnings from their own teams and other AI researchers that the risk stemming from a super-intelligent AI could endanger the human race. However, while the top Western firms have shown solidarity on this issue, others have urged caution or downright denied their claims, but there's a deeper story within the calls for a slowdown, namely the tension between open-source and closed-source AI models.

Nvidia CEO Jensen Huang said the safety fears were "made up," and that there was no need for a slowdown. Chinese officials called the claims "fearmongering," and an effort to stymie international AI development efforts, while President Trump waded in with characteristic bombast and said that he was enough of an AI safeguard on his own, and that it was in the interests of China to enact a frontier AI slowdown

Meanwhile, other countries are reacting to the news and taking independent efforts to investigate AI safety, with the UK's King Charles setting a meeting with leading AI figureheads to discuss how to better develop AI for the benefit of humanity.

Why now?

If you ask most workers who've been scared into believing their livelihoods were in jeopardy, the time for AI slowdowns came and went years ago. Indeed, many are nostalgic for the time before AI. But why are so many tech leaders only now raising the alarm?

They claim it's entirely based around safety fears. Following months of AI seemingly surprising their own developers by breaching sandboxes to go on exploit-hunting sprees. The volume of concern rose considerably after former OpenAI researcher, Jacob Coxon, resigned from Anthropic, claiming that none of the AI companies were taking AI safety and alignment seriously enough.

He didn't whistleblow on anything nefarious, dump documents or internal company data to prove his claims, or point to any specific attack vectors, or even actual harms. Instead, Coxon warned of a future potential of AI that he sees these companies racing towards without due concern.

What they're developing could, "kill us all by the end of the decade," he warned. It's not clear how, but it started a viral conversation all the same. Much like Matt Schumer's "Something big is happening" viral post from February this year.

Days later, OpenAI CEO Sam Altman, Anthropic CEO Dario Amodei, and Elon Musk showed surprising levels of solidarity for arch rivals in the space, putting out similar statements claiming that AI was becoming too powerful and that a general slowdown in the development of frontier AI models was the best solution.

Dario is right https://t.co/EwKgqQGaUoSeptember 12, 2026

Claiming that AI was playing an increasing role in improving itself — hinting at the recursive self-improvement (RSI) event that many AI researchers are concerned about — Amodei called for the creation of independent auditors for AI models. Altman agreed, even calling on governments to globalize the regulation to encourage unified compliance with any safety protocols enacted by the frontier developers.

Where we're going, we don't need roads

Not everyone feels these fears are warranted, however. China, which has recently made great strides in its development of highly intelligent open-weight models, called the concerns "fearmongering" and said it served no one's interest to be so confrontational. Although Chinese Premier Xi Jinping has said in the past that it was important for AI to "always remain under human control," the Chinese state-run Global Times paper called demands for a slowdown a method to "contain" Chinese developments.

Meanwhile, Nvidia CEO Jensen Huang has broken ranks with other Western AI leaders, claiming that there was no need for a slowdown and that any apocalyptic fears around AI were entirely fictional.

Nvidia CEO Jensen Huang was asked how to explain a claimed 10% risk of human extinction from AI.“We shouldn't, because it's made up.” "All of these predictions have been wrong" pic.twitter.com/TZ3EXL8cl1September 14, 2026

As one of the few companies making real — and enormous — profits from AI development, Nvidia has a vested interest in the expansion of the AI industry continuing on its current explosive trajectory. Indeed, it has heavily invested in it. Nvidia has stakes in hardware and software companies, along with providing backstops for neo-cloud firms. It also recently bought Hugging Face for $13 billion.

We've been here before

While the AI CEOs might have suddenly decided it's time to slow down, there have been many, many others who have made that call before now. U.S. Senator Bernie Sanders has been at the forefront of claims that the AI industry was moving too fast and breaking too many things, and recently called for heavy prison sentences for those developing superintelligent AI.

Over 1,000 AI workers signed an open letter in July this year calling on the U.S. government to control AI research and ensure safety and security. Others did that in 2023, too. This isn't even the first time that AI CEOs have called for slowdowns on AI development. Dario Amodei called for global coordination to police AI after the release of OpenAI's GPT2 model in 2019. Elon Musk did the same in 2023.

None of this takes away from the real dangers of AI, or the suggestion that now may really be the time to do something about them. But it does raise questions about the reasons behind their coordinated fear-raising. Even if it isn't fear-mongering.

Safety, or a trojan horse?

The collation of leading Western frontier AI companies clamoring for tighter controls over powerful AI models has another theoretical benefit too: containing the number of AI models that are permitted for use in the Western Hemisphere. A cursory look at OpenRouter's AI model rankings, which base themselves on the total number of tokens generated, places just three Western-made models on the top ten list — the heavily discounted GPT 5.6 Luna at number one, Nvidia's Nemotron Ultra 3 (Free) at number eight, and Google's recently-launched Gemini 3.8 Flash at number ten.

The rest of the models in the rankings are all open-weight Chinese models, which, more often than not, are cheaper than leading Western frontier models, according to the Artificial Analysis' Cost per Intelligence index. The Chinese models in OpenRouter's current top ten include Z.AI's GLM 5.3, Deepseek V4 Flash, and Tencent's Hy4 and Hy3. So, if the development of a Western frontier AI alliance emerges under the guise of calls for safety, it's possible that said companies are aiming to be the chosen few, creating a closed-loop monopoly for "preferred" AI providers. However, this remains speculation as the situation develops.

Will anything actually change?

Although the major AI companies may voluntarily, or even jointly, throttle their development efforts to improve safety, enacting anything globally significant will need the cooperation of international governments. There are certainly calls from politicians the world over to rein in the trillion-dollar companies and their cutting-edge autonomous systems.

But with the U.S. government firmly on the side of limited regulation, and no clear indication of what a slowdown would even look like. Would that entail limited compute? No new models? A halt to superintelligence research? It's hard to imagine a global consensus taking shape as things stand.

Asus' ludicrous $10,850 20th-anniversary bundle is now the cheapest way to buy an RTX 5090 — Nvidia's flagship GPU stock is so limited that this bundle with a 3000W PSU, X870E board, and open-frame case is actually cheaper than some scalper listings

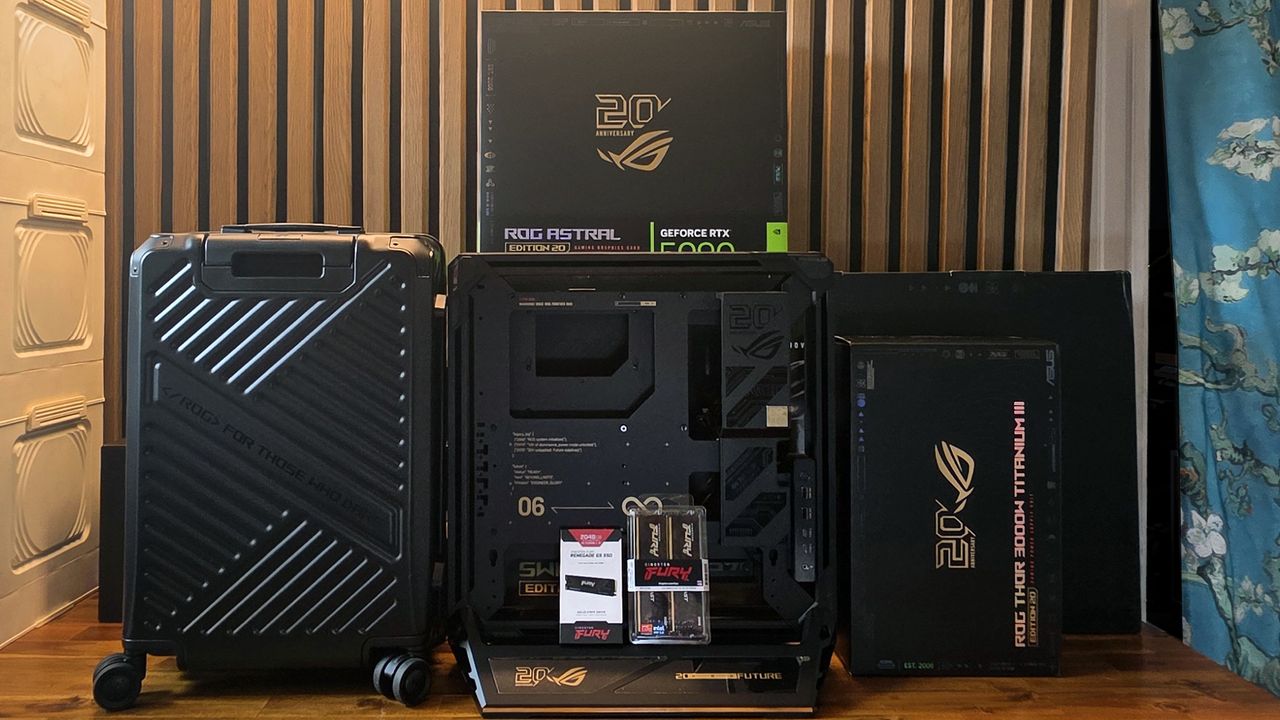
We've reviewed Asus' ROG Edition 20 anniversary kit. We've built a PC with it. It's about as premium as a gaming PC build can get. Right now, you can pick up the same kit for a whopping $10,849.96 on Newegg in a combo deal. To put it mildly, this is one expensive deal, but it's actually hiding a secret gem: it's the cheapest RTX 5090 graphics card on sale right now.

Check out this deal at Newegg

Writing up a near-$11,000 combo set as a deal might seem silly, but one of the core components here is the Asus ROG Astral GeForce RTX 5090 Edition 20 that is priced as part of this deal at $5,999. You can't buy this Astral card on sale individually right now. In fact, you can barely buy an RTX 5090 anywhere. RTX 5090 stock has almost completely disappeared in the United States, with only sketchy third-party sellers offering it at prices approaching $10,000.

This premium GPU is now ultra premium and, for the time being, ultra rare. Does that make this $10,849.96 Newegg combo deal a good option? If money is no object, you're perversely getting some value for your money, as long as you don't think too hard about the RTX 5090's original $1,999 MSRP.

ROG Edition 20 combo: $10849.96
This frankly ridiculous bundle includes all of Asus' ROG Edition 20 kit, including the ROG Astral RTX 5090, ROG Crosshair X870E, ROG Thor Titanium III 3000W PSU, and the ROG GR20 open-frame PC case. No discount, but the RTX 5090 is the cheapest you'll find it, in the oddest way.View Deal

Yes, the GPU is an unstoppable force for any gamer. Our GPU benchmarks make that very clear. The RTX 5090 is the best GPU you can buy, and no other consumer GPU is going to beat it. It has 21,760 CUDA cores and 22GB of GDDR7 VRAM, with a 512-bit memory bus and bandwidth speeds of up to 1,792 GB/s.

This Astral is a world-beater of its own, though. It features an upgraded design, with a second BTF power connector to pull up to 800 watts, a glass backplate, and a curved OLED screen. It has faster clocks, hitting 2,750 MHz, with a 4.7-slot design. Performance-wise, the OG Astral is beating world records, so this is a card that you can really push to its limits (if you're not scared of charred power cables).

GPU Benchmarks Hierarchy performance charts
Tom's Hardware
GPU Benchmarks Hierarchy performance charts
Tom's Hardware
GPU Benchmarks Hierarchy performance charts
Tom's Hardware

The $6,000 GPU aside, you're also getting a $3,299 Asus ROG Crosshair X870E Edition 20 motherboard. Asus has a few variants of this, but the Edition 20 board here has (alongside some beautiful gold accents) supports for up to nine M.2 SSDs, with five slots on the board and more via add-in cards. There are six USB-C ports, plus two 20 Gbps front-panel connectors. Large copper VRM heatsinks work with its integrated AIO cooler, with a curved 6.7-inch AMOLE screen and a huge copper heatsink. Probably overkill, but for $3,299, you want it all.

You're also getting a $899.99 Asus ROG Thor Titanium III 3000W Edition 20 power supply. It's a PSU, but 3000W isn't to be sniffed at, and it'll certainly provide enough power for the monstruous Astral RTX 5090. It’s fully modular, with another OLED display (magnetic, this time) which you can mount either side, or extend with a cable.

Asus ROG Edition 20 build

(Image credit: Tom's Hardware)

Finally, you get the Asus ROG GR20 open-frame EATX PC case, set at $649.99. This is a totally new design from Asus, supporting large EATX motherboards, and you can stand it vertically or horizontally. There's a crossflow fan to blow cool air onto the GPU, RGB light strips, and several fast USB ports. It's mostly aluminum, with some plastic, magnetically attached cosmetic covers around the sides.

$10,849.96 for this Asus combo kit is so much money for anyone to spend on a gaming PC build, but, unfortunately, we are where we are. As our Asus ROG Edition 20 build write-up mentions, this is a kit that few will buy and own. AI is pushing gaming PCs to new heights, and it's a real shame that we're now seeing current-gen flagship GPUs like the RTX 5090 becoming so rare to buy that combo offers like this are, perversely, almost good value. If you're spending $6K or more on a GPU, though, then it might make sense. You won't find an RTX 5090 cheaper (or, probably, at all, at least for some time) so if you want the best gaming PC build that you can find, this is the kit you'll want. For once, we don't imagine this will sell out soon, but Newegg might pull the deal at any point.

Intel reportedly cans 12Xe option for Nova Lake-S desktop — gaming APU design said to resurface with Razor Lake

Intel won't launch a Nova Lake-S SKU with 12 Xe3P graphics cores, according to tipster Jaykihn, who originally flagged a beefed-up APU design with the Nova Lake architecture. The original SKU was said to come with 4 P-cores, 8 E-cores, and 4 LPE-cores, along with the 12 Xe3P cores, presumably offering an inexpensive onramp to a gaming desktop without a discrete GPU. Now, the leaker says that design is cancelled, and Intel intends to pick it back up with Razor Lake, the generation that will follow Nova Lake.

Nova Lake -S 12Xe has been changed to Razor Lake -S 12XeSeptember 14, 2026

Originally, Intel's 12 Xe3P Nova Lake SKU was said to require 65W of dedicated power to drive the iGPU, necessitating the use of two VCCGT phases on the motherboard for integrated graphics. Intel's Arc B390 GPU, which is the 12 Xe3-core model available in Panther Lake and Arc G-series processors, has a thermal design that can sustain up to 80W. However, it's currently being used in Panther Lake machines and handhelds like MSI Claw 8 EX AI+ that have lower power targets.

The Xe3P architecture is slotted for use in Intel's Crescent Island AI accelerator, but it hasn't been announced for any other products yet. Xe3P supports a wide deployment of Xe cores (up to 32), a deeper XMX engine with support for low-precision data types like FP8 and FP4, an increased 512KB L1 cache per Xe core, and a new unified L2 cache (32MB on Crescent Island).

Even by desktop APU standards, an 80W iGPU is a beefy accelerator to have on the same package. In addition, Intel's Nova Lake stack is said to extend up to a 175W TDP with the rumored top-end 52-core SKU, meaning the full 12 Xe3P iGPU would likely only be possible lower down the stack (and maybe only in the 4 + 8 + 4 + 12 Xe design originally suggested).

Earlier in the year, rumors suggested Intel was working on a mobile APU to counter AMD's Strix/Gorgon Halo products, featuring a large pool of unified memory and a large iGPU, dubbed Nova Lake AX. Now, the rumor mill suggests Intel will recycle the Nova Lake CPU cores for Razor Lake AX on mobile while pushing a larger iGPU.

Nova Lake-S rumored specifications

SKU*

Core Config (P+E+LPE)*

bLLC*

TDP (Unlocked/Locked)*

52 Cores (dual-tile)

(8+16)+(8+16)+4

288MB

175W

44 Cores (dual-tile)

(8+12)+(8+12)+4

264MB

175W

28 Cores

8+16+4

144MB

125W

28 Cores

8+16+4

-

125W / 65W

24 Cores

8+12+4

132MB

125W

24 Cores

8+12+4

-

125W / 65W

22 Cores

6+12+4

108MB

125W / 65W

22 Cores

6+12+4

-

125W / 65W

16 Cores

4+8+4

-

65W / 35W

12 Cores

4+4+4

-

65W / 35W

8 Cores

4+0+4

-

65W / 35W

6 Cores

2+0+4

-

65W / 35W

*Specs rumored, unconfirmed by Intel

Intel has told us that Nova Lake is one of the most important desktop CPU launches for the company ever, following on the heels of the mediocre Arrow Lake rollout. Perhaps the biggest addition to the lineup is rumored to be bLLC, or big last-level cache, which is said to show up on select SKUs to counter AMD's X3D assault among the best CPUs for gaming. The company has yet to confirm that bLLC is even possible with its current packaging capabilities, though enthusiast channel VP Robert Hallock hinted to Tom's Hardware that Intel has plans to address X3D in the next generation.

The main stack is rumored to climb up to 28 cores, with two additional dual-tile SKUs that can go as high as 52 cores. The dual-tile models look like a bid for HEDT, perhaps competing with AMD's Threadripper CPUs, though it's not clear how Intel will position its dual-tile models yet.

Earlier this month, a leaked slide gave us a glimpse into Intel's launch plans for Nova Lake. The slide suggested Intel will announce the main stack (up to 28 cores) in Q4 of this year, with the chips arriving in Q1 2027. Intel will apparently follow up later in the year with the 52-core model. This aligns with what we've heard from our sources about Intel's Nova Lake rollout.

Alongside Nova Lake, Intel will introduce the new LGA1954 socket, along with the flagship Z990 chipset. We've already seen multiple Z990 motherboards in the flesh, suggesting Intel is preparing for a Nova Lake release in short order.

US AI data centers projected to become the fifth-largest natural gas consumer in the world by 2035 — consumption to grow by 15 billion cubic feet per day as demand for compute increases

The estimated natural gas consumption of data centers in the U.S. is expected to massively increase as these facilities increasingly rely on gas turbine generators for their power. According to Bloomberg, data centers are projected to use up to 15 billion cubic feet per day by 2035, a 117% increase from the previous forecast of 6.9 billion cubic feet. This number tracks with other data center forecasts, which suggest that data centers will use 20% of U.S. power by 2035, amounting to about 194 gigawatts.

Many data center projects have already been delayed by the lack of available power infrastructure, with power plants expected to take so much longer before they come online. It’s for this reason that many developments have turned towards onsite generators, so much so that AI demand is now compounding the jet engine shortage already plaguing the aviation industry.

Elon Musk was among the first to use gas turbines to power a data center when he deployed them at the Memphis Supercluster in 2024, even though he didn’t have permits for some of them. Now, it seems that the world’s richest man has seen this trend and has invested a billion dollars to buy a portable gas and diesel turbine leasing company. He even announced that SpaceX will start in-house turbine blade manufacturing to help cut down on the manufacturing bottleneck plaguing the jet engine industry.

New technologies like small modular reactors are currently being developed as an answer to AI data centers’ insatiable demand for power, like Ampera’s 3D-printed modular thorium nuclear reactor or Valar Atomics’ Ward 250 nuclear microreactor. Many AI hyperscalers, including Amazon, Google, Microsoft, Nvidia, and Oracle, have even invested in projects like these in a bid to generate massive amounts of clean energy for AI. However, they’re expected to take a few more years before they could become commercially viable — time that tech giants do not have. Because of this, Musk said that “natural gas will still be needed to supplement and bootstrap solar for several years.”

The deployment of natural gas turbines in data centers isn’t good news for the communities living around them, though. The NAACP said in its lawsuit against SpaceXAI that the use of these turbines at Colossus 2 increased nitrogen oxide exhaust by 111%, PM2.5 particles by 83%, and formaldehyde emissions by 88%. While the company has already pledged to remove all its unpermitted generators, the process will take at least a year as the portable turbines are slowly being replaced by a 1.2-gigawatt on-site power plant.

Aside from this, the massive demand for natural gas could potentially put a strain on the supply, causing prices to rise and hit the average consumer. Domestic natural gas producers are projected to raise their output by 35 billion cubic feet per day in the next decade, but this still falls short of the forecasted demand by around 11 billion cubic feet per day. So, unless output manages to catch up with the demand, prices are expected to shoot up and cause a scramble for available supply. Still, some experts suggest that there are still more than enough undeveloped gas fields within the U.S. to allow the industry to increase natural gas supplies and reduce costs.

ChatGPT transcripts are reportedly read by humans to improve responses, including those with personal information — 'Project Lilly' has seen OpenAI hire hundreds of contractors to manually review logs

AI companies don't have a great track record in areas like copyright or user privacy — unless they're the ones on the short end of the stick, that is — but it's generally known that the chat logs from platforms like ChatGPT are used for improving models. The mechanism as to how this happens was still a mystery until today. 404 Media just published a report about OpenAI's process of human review for chat transcripts, explaining how the review process works, and how it involves other humans sometimes reading private information.

The rating project's name at OpenAI is Project Lily. The publication got information on the project's instruction guides, Slack channels, real ChatGPT conversations, and, of course, the rating system to classify conversations. The operators are called "prompt reviewers," and their job is fairly simple: look at anonymized real-world chats, and judge the quality of ChatGPT's responses to assess whether they actually answer the question, and that the text doesn't overuse "AI-speak," patronizing tones, emojis, or sycophancy, among other parameters. Anthropomorphizing and stating "personal" experiences are both off the table, meaning that while it's OK for ChatGPT to say "I found some information," it's not OK for it to say "as a chef, I like to..." or "I know what that's like."

The work is "very rote," according to a reviewer, but at reportedly over $50 an hour, it's a high rate for what looks like reasonably simple work. The reviewer also said that their guidelines keep changing and are often self-contradictory, a feeling most software developers should easily identify with.

The person doesn't think that most users are aware their chats are being read by others, though, something that's particularly troubling when many use ChatGPT as an impromptu friend or therapist and put deep secrets in words for the bot to read.

While the chats allegedly go through an anonymization pass and reviewers don't see usernames, OpenAI admitted to 404 Media that the filtering may let some personal data through, especially in shorter chats. The site notes that in many conversations, the user asks ChatGPT to keep the contents secret, as well. The version of the chat handed to reviewers also reportedly includes a "user memories summary," containing a summary of the users' questions and interests, context, and potentially even location.

Crucially, Project Lily does not grade the chats' actual factual accuracy other than flagging obvious mistakes, implying that there's likely at least one more team (or several) doing separate evaluations. Likewise, this reviewing is separate from manual safety checks that ascertain if someone might be looking to hurt someone else (or, presumably, themselves).

The existence of the project also indicates that contrary to these image AI companies try to cultivate, the models don't improve just with technological advancement and better training sets — it appears you still need more than a few competent humans in the mix.

By now you may be wondering about the "allow us to use your chats to improve our product" (paraphrased) setting present in most consumer-facing chat bots. That setting is turned on by default in every bot we can think of, even with many paid plans. In ChatGPT's case, it does default to off in Enterprise, Business, and Educational customers.

That toggle switch does not work retroactively, though, so any chats already in ChatGPT's database will remain there unless the user requests deletion. Also, said deletion is also not retroactive, meaning that deleted chats may have already been hoovered and anonymized, and possibly reside in a dataset somewhere.

Although OpenAI initially had no answer to 404 Media's inquiry on whether users were explicitly informed that their chats could be read by humans, the company eventually offered a link to one of its FAQ pages that discusses human review for the purpose of model improvement. We verified ourselves that said notice is at least two years old, and likely older. After the publication of the exposé, the firm changed its help page explaining how people can opt out of data collection, but there's no mention of human operators in that text.

This type of data collection and review is a running theme across most providers. Google Gemini clearly states that "humans may review some saved chats" in its Privacy Hub. Anthropic's stance is similar, with a page dedicated to this topic. Perplexity's stance, meanwhile, is unclear, as its Privacy Notice doesn't confirm or deny human access to chat logs.

Microsoft rolls out emergency update for Windows 11's latest patch — recent update causes crashes on AMD graphics, Explorer hang-ups, and broken third-party integrations

Microsoft has issued an out-of-band update for its recent Windows 11 patch, which has caused a number of bugs and issues. The September 2026 update was just released last Tuesday, and although it packs a number of new features and fixes nearly 1000 security flaws (commonplace in this day and age), there are also a few unfortunate regressions.

The 25H2 update finally reintroduces a movable taskbar, just like we've had since Windows 95, with an option to make the height smaller for compact displays. Likewise, the Start menu now has multiple configurable layouts, and you can toggle each main section on or off. Microsoft also revamped Windows Search — perhaps to finally be useful — and users can now choose to only have it display local results. Explorer got a handy tweak in the form of using KB, MB, GB size indicators, as well.

The update has also surfaced some serious bugs. First off, PCs with AMD Radeon GPUs are crashing, apparently due to the update provoking driver instability. Reinstalling the driver doesn't appear to help, and the reports unfortunately cover most contemporary AMD graphics cards. Microsoft did not mention AMD GPUs specifically in its latest update.

Microsoft noted that it has fixed an issue with Remote Desktop Services where RDS might become unstable, causing connection and sign-in failures.

Microsoft is also aware of an issue with audio output and microphone input going dead. Additionally, there are seemingly reports of audio devices starting up with a botched configuration, like tweaked 3D audio settings or speaker setups. The apparent workaround seems to be putting audio in a standard 2.0 configuration, but Microsoft has now addressed this issue in the emergency patch.

Explorer may display a black screen after logging in, leaving you with a perfectly functioning operating system but no visible UI. The File History backup feature is reportedly not detecting external drives, effectively making it useless. Of particular concern to enterprises, systems administrators, and homelabs, the Remote Desktop Service is also experiencing issues. Last but not least, Microsoft says it has addressed an issue where Claude Cowork is nonfunctional due to the update breaking HC-managed Linux VMs with Plan9 shared folders

Owners of HP and Lenovo systems are also advised to consider holding off on this update. Ever since the August 2026 patch (and now, cumulatively, with the September update), there are reportedly serious issues on both camps. On the HP side, there are instances of the update triggering BIOS corruption, leading to a failed install with no ability to recover the OS — though seemingly the OEM has published a new BIOS revision, so it's hard to say which side is to blame. Meanwhile, Lenovo users might have their machines black-screen or shut down out of the blue, seemingly due to power mismanagement.

While it's heartening to see that Microsoft has significantly increased its Windows development speed and is seemingly listening to customer feedback, a string of bugs after a major feature update are still common.

Grab a $560 saving on this 1440p-ready gaming PC with a 9800X3D and RTX 5060 Ti 16GB, now $1,859 — all-white CyberPowerPC desktop ships with one of AMD's best X3D chips, along with 32GB DDR5 and a 2TB SSD

A pre-built gaming PC with one of AMD's top X3D chips inside is always going to be a formidable option, especially if it's coupled with a current-gen Nvidia GeForce GPU. That's exactly what you're getting with this all-white CyberPowerPC machine, down to $1,859.99 thanks to a $560 discount, that ships with a 9800X3D, RTX 5060 Ti, and 32GB of DDR5 RAM.

Check out this deal at Walmart

That's a serious set of specs with few compromises to think about in a market that's seen huge price rises over the last 12 months. Building a new gaming PC has become far more expensive than buying a good pre-built, and the specs you're getting here set you up with a rig that'll let you play games at 1440p at high frame rates and the best graphics presets for years to come. This particular rig scored 4 stars in our CyberPowerPC Gamer Supreme review, with praise for its performance and room for upgrades later.

Gamer Supreme (RTX 5060 Ti 16GB): was $2419.99 now $1859.99
This CyberPowerPC pre-built gaming PC is ready for gaming at 1440p. It features the AMD Ryzen 7 9800X3D, Nvidia GeForce RTX 5060 Ti 16GB, 32GB of DDR5 RAM, and a 2TB SSD for storage.View Deal

Featured in this rig is one of Nvidia’s current mid-tier graphics cards in the RTX 5060 Ti. It ships with 4,608 CUDA cores and a boost clock speed of 2,527MHz, along with that all-important 16GB of GDDR7 VRAM. Unlike the RTX 5090, this RTX 5060 Ti only requires a single eight-pin PCIe connector to deliver power, so you won't need a huge amount of electricity to run it.

Our RTX 5060 Ti 16 GB review is clear that this GPU is a very good option for mid-tier builds, with ray tracing performance proving to be much better than its rivals. You've also got the full support of Nvidia DLSS 4, giving you access to functionality like multi-frame generation to give your rig a frame rate boost in the most resource-heavy games, especially if you want to try and push to 4K.

Nvidia GeForce RTX 5060 Ti 16GB performance charts
Tom's Hardware
Nvidia GeForce RTX 5060 Ti 16GB performance charts
Tom's Hardware
Nvidia GeForce RTX 5060 Ti 16GB performance charts
Tom's Hardware
Nvidia GeForce RTX 5060 Ti 16GB performance charts
Tom's Hardware

At this price point, though, 16GB of VRAM is the serious winner. You're giving yourself much more headroom for better performance than the budget-friendly 8GB GPUs that you'd otherwise have to switch to. That'll mean that stable gaming at 1440p will be easier to achieve.

Couple that with the eight-core AMD Ryzen 7 9800X3D. This continues to be the best CPU overall for gamers, even if AMD has launched faster models since, because of its price-to-performance value. It continues to offer outstanding gaming performance, as the CPU benchmarks show, with 1% low frame rates that ensure the smoothest possible gameplay. The power of AMD 3D V-Cache, stacking extra L3 cache (96MB in total) so that games don't need to drop down to the slower system RAM, gives you a serious performance boost.

You won't see much compromise elsewhere, either. 32GB of DDR5 RAM means you won't face memory bottlenecks, and a 2TB Gen 4 SSD gives you good storage capacity for several big game installations alongside Windows. You're also getting Wi-Fi 6 and Bluetooth 5.2 wireless connectivity, along with Gigabit Ethernet for a wired setup.

The $1,859.99 sale price for the CyberPowerPC Gamer Supreme rig on sale here is a good price given its performance potential. You're getting a solid 1440p-capable gaming PC, with the best CPU and a formidable GPU to match, with plenty of room to upgrade in the future, and a lot of longevity until then. Don't expect this $560 discount to be around for long.

Minecraft Legacy gets rewritten in C++ for PS2 and Wii ports — code is tuned so it works well even on the PS2’s meager 32MB of RAM

Games optimization specialist OptiProjects (AKA OptiJeugos) has released a new port of Minecraft Legacy for the Sony PlayStation 2 and Nintendo Wii consoles. The project is based on the Minecraft Java 1.2.5 source code, rewritten in C++, and using a recreated legacy console interface (machine translation). Even on the quarter-century-old PS2 with its cramped 32MB of RAM, the OptiCraft Heritage Edition runs at 15-30 fps. Check out the video demo embedded below.

TERMINADO!!! FINALMENTE NUEVO PORT DE ""MINECRAFT LEGACY"" a PS2 y WII!!Es un PORT de JAVA 1.2.5 a C++ con la interfaz de Legacy recreada, corriendo nativamente en la PS2 y Wii.Probado en hardware real! La wii soporta online con servidores de JAVA en esa version! https://t.co/x3pQw8XvBJ pic.twitter.com/nZNc0QehGySeptember 14, 2026

Minecraft is one of the best-selling games of all time, with sales above $400 million according to an Entertainment Weekly report earlier this year. Meanwhile, the PS2 is the best-selling home console in history, with 160 million units shifted worldwide. When Minecraft first launched, the PS2 had already been kicking around for close to a decade and was rapidly reaching retirement age. Thus the Minecraft PS2 game release was never a thing (it did launch on PS3 in 2013-14). Similarly, the Wii got overlooked by Minecraft's publishers, with the Wii U only getting the game in late 2014.

Windows PC (Java Edition 1.2.5)

PS2 (OptiCraft Heritage)

Wii (OptiCraft Heritage)

Engine / Language

Java

C++ (native port)

C++ (native port)

Hardware / RAM

Min. ~2GB recommended for era

32MB system RAM

~88MB available RAM

Chunks / draw distance

Scalable, (usually 8–16+ chunks)

2 chunks

4 chunks

Performance

Often 60+ FPS on period PCs

15–30 FPS

15–60 FPS

Controls

Keyboard + mouse

DualShock 2

Wii Remote / Classic Controller

Interface

Original 1.2.5 UI

Recreated Legacy interface

Recreated Legacy interface

Ponder over the features and performance comparison table we have nailed together, above. You can see how tightly the PS2 version is constrained by its hardware limitations. In comparison the Wii version is significantly more comfortable. Moreover, the Wii version has experimental online gaming functionality.

Minecraft Legacy for the Sony PlayStation 2 and Nintendo Wii
OptiProjects
Minecraft Legacy for the Sony PlayStation 2 and Nintendo Wii
OptiProjects

If you are interested in enjoying some retro Minecrafting on your old PS2 or Wii, or emulators for either system head on over to the official OptiProjects page linked top for your downloads. Those aiming to play on original hardware will need to be able to load .ELF files from USB (on PS2), or access the game via SD card and the Homebrew Channel (on Wii). To my knowledge that means your PS2 or Wii must be soft or hard modded to play homebrew code.

Developer builds viral 3D source code visualizer that consumes 21GB of RAM — flies around 2.5 million lines of code at over 120 frames per second

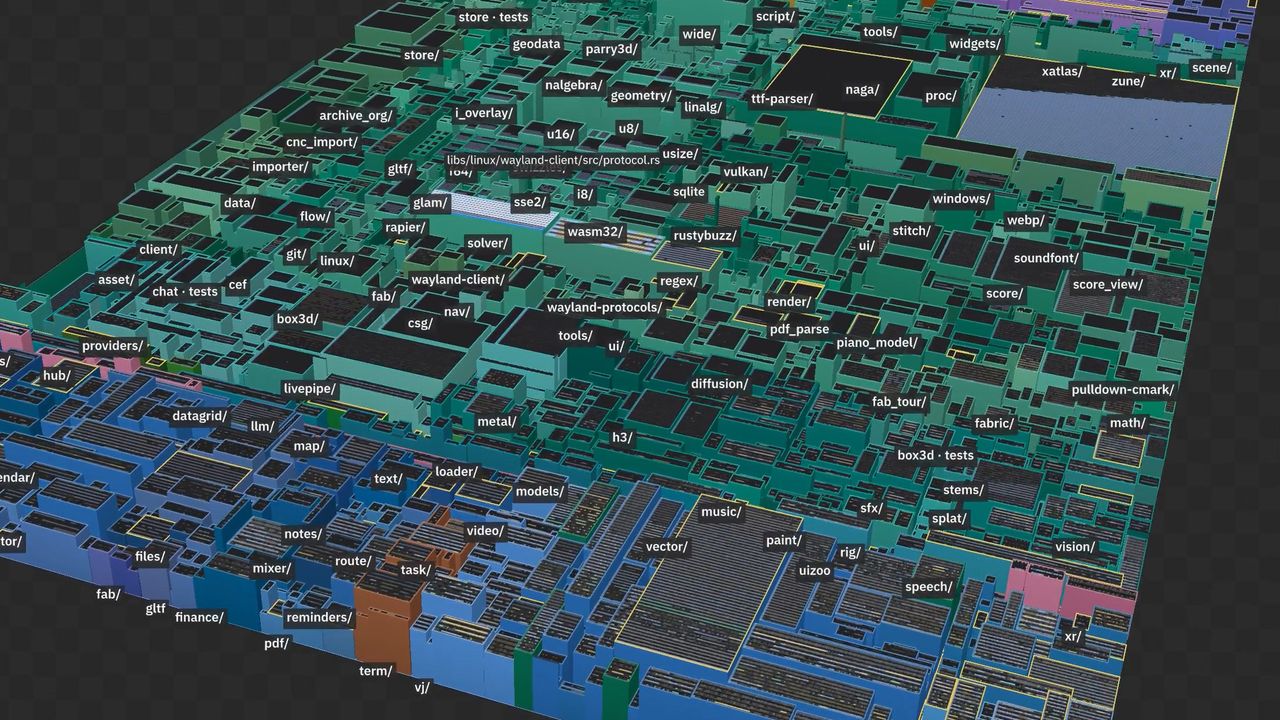
The immortal line "it's a Unix system, I know this" is forever entrenched in many a techie's brain. In the Jurassic Park movie, the visualization software in question was Silicon Graphics' File System Navigator for IRIX, an actual piece of software running on a real SG workstation. The concept of viewing files in 3D space never truly caught on, but the horsepower available in contemporary machines may change that. Makepad creator Rik Arends created his own 3D flyable source code visualizer that he claims handles 2.5 million lines with ease, at 120+ FPS, no less.

Ironed out the last performance issues with my full 2.5m line codebase explorer. 120hz awesomeness. Can only upload 60fps video tho. Much nicer uncompressed pic.twitter.com/LUsrmVaI6LSeptember 12, 2026

Although the published video is only at 60 FPS due to X's limitation, the navigation looks smooth indeed, and it's impressive to see all the actual source code in a reasonably readable manner. Arends says the visualization initially took 21 GB of RAM (in this economy?!), but that after judicious application of indexes and streaming compression, he got memory usage down to a much more palatable 3.5 GB. Although he remarked that he's yet to fully optimize the visualizer, he did try to load Chromium's entire source tree (51 million lines) in only 60 seconds at one point.

While one can argue that the 3D visualization of the code itself is probably really fun to look at, its practical use is also questionable, at least as-is. A commenter remarked that adding a time element would help immensely, by displaying changes to the source files. 3D tracking of dependencies would probably be handy, too. There's already an actual full-fledged commercial tool called CodeCharta that visualizes changes and hotspots in 3D, though the flybys aren't quite as impressive.

Arends says that he intends to turn this visualization tool into a product and charge a small fee for it, though he admits that the usefulness of the visualization may be limited. When asked why he created this, he simply said, "because I could." The jury is still out on whether he should.

AMD's Radeon RX 9070 GRE graphics card returns to its lowest-ever price of $499 — rare deal places this current-generation 12GB GPU below its MSRP launch price

It's back: one of the best deals on a brand-new, current-generation, mid-range graphics card that packs 12GB of VRAM. There is a little hoop to jump through via Newegg to receive the discount, but it's more than worth it to slash $70 off the card and bring the price back down to its all-time low. AMD's Gigabyte Gaming Radeon RX 9070 GRE GPU is available at Newegg for $499. All you need to do is click on the "Extra Discount Available" link and enter your email address to receive the promotional code. Once you do that, you bring the price of this graphics card all the way down from its $569.99 list price. It's a very grim time for shopping for PC component upgrades, so to see an actual deal on a GPU that takes it below its MSRP in today's inflated market is a rare sight indeed.

Check out this deal at Newegg

The RX 9070 GRE was initially made available to the Chinese GPU market and received a few changes from the original RX 9070 XT. The available VRAM was cut from 16GB to just 12GB of GDDR6, but it still sports bandwidth speeds of 18 Gbps on a 192-bit bus, producing 432 GB/s of memory bandwidth in gaming and applications. The Radeon RX 9070 GRE is still built on AMD’s RDNA 4 graphics architecture and uses the same Navi 48 GPU as the Radeon RX 9070 and RX 9070 XT. The RX 9070 GRE features a cut-down version of the Navi 48 chip with 48 compute units compared to the RX 9070's 56. Using just 220W total power draw, the RX 9070 GRE has an Identical power footprint to the standard Radeon RX 9070 GPU, making it quite power efficient and not needing a huge power supply to run.

Gaming Radeon RX 9070 GRE 12GB: was $569.99 now $499.99
A great graphics card for 1080p and 1440p gaming, the RX 9070 GRE sports 12GB of VRAM and boost clock speeds of 2920 MHz.

View Deal

We benchmarked the Radeon RX 9070 GRE in our extensive review, putting it through its paces in our suite of games. We found the card averages a cool 120 FPS at 1080p settings and 86.6 FPS at 1440p across our 11-game raster-only test suite. This is a good GPU choice for 1080p and 1440p gaming, with the RX 9070 GRE packing ample VRAM for high settings at 1080p, but pushing ultra settings at 1440p may use up the 12GB of VRAM. AMD's Radeon RX 9070 GRE sits just behind Nvidia's RTX 5070 in our results chart that you can view below.

Radeon RX 9070 GRE
Future
Radeon RX 9070 GRE
Future
Radeon RX 9070 GRE
Future

If you're actively looking for a new GPU in the current PC component market, you're more than aware of the considerable price hikes across the GPU lineups from both AMD and Nvidia. To see a graphics card on sale for under its launch MSRP is a very rare sight, and I personally did not expect to see this kind of deal again outside of a large sale event like Prime Day or Black Friday. So if you're looking for a competent card for 1080p and 1440p gaming, then jump on the Gigabyte Gaming RX 9070 GRE for just $499.99.

Perplexity’s local AI agent comes to Windows, but only for RTX GPUs with at least 24GB of VRAM — Portable Computer brings AI for multistep tasks to compatible PCs

Perplexity has released Portable Computer for Windows, in partnership with Nvidia, via the existing Perplexity app for Windows. Previously, this functionality was only available on Linux-based operating systems. The hardware requirements remain, meaning the host system must have at least 24GB of VRAM with a GeForce RTX or RTX PRO GPU. Likewise, a Pro or Max Perplexity subscription is required. Portable Computer was originally launched on the DGX Spark as a fully local AI agent platform.

Portable Computer, launched originally for Linux on Aug. 25, is a local version of Perplexity Computer, which is the company’s agent for multistep tasks. Perplexity Computer can plan, run subtasks through connectors and tools, and produce a result other than a simple chat response. This runs in Perplexity’s cloud and consumes Computer credits. Portable Computer is the same agent but with features running on your local PC instead of in the cloud. Local work does not consume credits, but the agent can send tasks to cloud models with explicit permission if necessary, the company said. Nvidia said on Sept. 3 that Windows support was coming soon.

Perplexity Portable Computer open on a Windows laptop, showing the empty task composer

(Image credit: Perplexity)

Portable Computer for Windows comes with some new features. These include scheduled recurring tasks and local MCP servers for desktop apps, according to Perplexity. Nvidia listed connectors for Microsoft Word, Google Drive, Gmail, Slack, and GitHub. The app also includes a dropdown for downloading a local model with one click. Nvidia named Qwen 3.8 27B as an example local model. DGX Station support is expected soon, Nvidia said.

Aravind Srinivas, CEO of Perplexity, wrote on X on Sept. 14 that with this release comes “unmetered local intelligence on every Windows PC running on Nvidia hardware and Perplexity harness.” The 24GB requirement is a VRAM gate more than a generation gate, cutting across Nvidia’s consumer lineup. Cards that meet the stated 24GB+ VRAM requirement include the RTX 3090 and 3090 Ti (24GB), the RTX 4090 (24GB), and the 5090 (32GB). The RTX 5090 Laptop GPU at 24GB has not explicitly been mentioned by either company. RTX PRO Blackwell cards that qualify are the 4000 (24GB), 4500 (32GB), 5000 (48GB or 72GB), and 6000 (96GB).

We're expanding our work with @nvidia to bring fully local AI to Microsoft Windows PCs with RTX GPUs. Unmetered local intelligence on every Windows PC running on NVIDIA hardware and Perplexity harness. Enjoy!September 14, 2026

In a Sept. 3 post ahead of IFA, the consumer electronics trade show in Berlin, Nvidia indicated more plans along these lines. The post stated that RTX Spark Windows PCs from Lenovo and Acer are expected in October and that two local agents, Hermes Agent and OpenClaw, are getting the same simplified local setup. For users who already own a qualifying RTX PC, the Windows release removes the need to buy a separate system. Upgrading a compatible desktop with a used qualifying card could also cost less than buying the DGX Spark Founders Edition at its $4,699 price.

Anthropic says AI can boost U.S. GDP by 32%, up to $44.4 trillion in four years — economics model predicts that displaced employees 'may have to switch to jobs like electrician and nurse'

Last week, Anthropic published its prediction of what the economic impact of AI on the U.S. economy is going to be for the next few years. The company thinks the U.S. can reach a $44.4 trillion GDP or higher by 2030, provided, of course, it conveniently adopts AI at a rapid pace. Having said that, Anthropic admits "the challenge is making sure that the gains are broadly shared."

The interactive post has a simulator where readers can plug in their estimates on key factors and get their own future predictions, within the firm's analysis and perspective. That's definitely interesting to play around with, but perhaps the most relevant piece of information is the lens through which Anthropic views the world.

Anthropic establishes its reasoning by first placing tasks in broad categories and using a nurse's workday as an example. They removed tasks, including those that will disappear naturally as technology progresses, like collecting data on paper or physically visiting the patient to collect basic vitals — neither happens anymore as remote monitoring becomes commonplace. However, some new tasks are added, like keeping an eye on dashboards for the aforementioned AI-powered monitoring.

Then, there are naturally the tasks that a bot can't perform, like bathing a patient. Augmented tasks include those that require a human, but can be made more efficient with AI: helping with triage, planning schedules, and assisting with dashboard data. Some tasks may be fully automated, like keeping supply closets full or scheduling follow-up patient visits. Finally, AI usage can introduce some tasks of its own, like reviewing automated triaging or double-checking dashboard alerts — perhaps even impromptu data recovery.

The company's predictions broadly hinge on how ubiquitous AI usage becomes, and therefore, the number of tasks transitioning into fully or partially automated. Unsurprisingly, Anthropic believes that the more entrenched AI gets, the more value the country creates, though at greater risk — and on an exponential scale, no less

Three models are presented, from "modest" economical impact to "extreme." The modest model establishes a 1.6% GDP rise to $34.1 trillion, an impact Anthropic says is in line with that of new technologies like the internet, and crucially, doesn't imply tectonic shifts to unemployment rates or wages.

For the "substantial impact" scenario, although AI is predicted to be able to do half of "knowledge work," mostly without intervention, adoption remains limited. This scenario foresees twice the normal economic growth, this time +8.3% to $36.3 trillion.

This future marks the inflection point at which Anthropic believes knowledge workers see their wages remain steady instead of growing, though it's not clear if the firm accounts for inflation. Additionally, the firm states that "knowledge workers may see a lot of automation and displacement [...] coders and call service center agents may have to switch to jobs like electrician and nurse", a statement some might argue is already true. In that sense, Anthropic expects other workers to start seeing more cash.

The eyebrow-raising prediction for both the above scenarios, though, is that Anthropic expects unemployment to "stay within ranges history has seen before," an odd statement given modern U.S. history contains events like the Great Depression. The company does note that it expects job churn to increase, but also that while "this process can be painful, [it] works relatively well from a macroeconomic perspective." Average wages are expected to rise across all three scenarios, though the increase is expected to go towards workers outside of knowledge areas.

In the "extreme" scenario, Anthropic expects significant changes. Should AI be super-widely adopted, the GDP can increase by 32.4%, corresponding to a cool $44.4 trillion, a "profound economic transformation." This is the point at which the firm expects that AI becomes more productive than humans for most knowledge work, and does so with near-autonomy. Equally worryingly, it's expected that there will be "essentially no" new knowledge tasks created.

Anthropic notes that to reach this kind of stage, the country would "likely require" recursively self-improving AI (using the AI to make better AI). There's a significant catch, however, as though the U.S. would be "far richer than [it's] ever been," knowledge workers would be the hardest hit with a 10% wage drop, plus overall unemployment would climb "beyond typical recessionary levels." Manual labor would be prized, though, given that "as AI increases productivity within knowledge work, the demand for manual work that benefits from that productivity will increase."

Scenarios aside, the one big question is: How would all that GDP money land in people's pockets? Anthropic admits this problem is a "challenge" and offers little solution for it. Such a high amount of future AI penetration might prove a hard sell, considering wealth inequality in the U.S. already sits at its highest level for the last few decades and is trending in that direction in most developed nations. Others might argue with Anthropic's assessment that unemployment levels would remain somewhat in the less extreme scenarios, seeing as job cuts are rampant across many sectors and have hit technology-related fields the hardest.

To its credit, Anthropic clearly highlights part of the wealth-inequality issue. The company admits that more AI automation might skew the current 60/40% balance between labor and capital, respectively, strongly tilting the scale in favor of capital ownership and increasing inequality. Many argue that's already happening today. There's also the matter that the prediction appears to assume little competition from other countries, nor does it offer insight as to what would happen to "AI-less" nations.

The interactive blog post and its simulator are worth a good read and fiddling with, regardless. Anthropic published the technical details on the mathematical model used in a separate article and published its Economic Policy Framework last June.

❌