While I was out at Texas Linux Fest this past weekend I got to watch a fun presentation from the one and only Brian Beck. He walked through an introduction to Blender, including an overview of creating his great The Lady in the Roses image that was a part of the 2015 Libre Calendar project.
Coincidentally, during my trip home community member @Fotonut asked about software to create an HD slideshow with images. The first answer that jumped into my mind was to consider using Blender (a very close second was OpenShot because I had just spent some time talking with Jon Thomas about it).
I figured this much Blender being talked about deserved at least a post to answer @Fotonut‘s question in greater detail. I know that many community members likely abuse Blender in various ways as well – so please let me know if I get something way off!
The reason that Blender was the first thing that popped into many folks minds when the question was posed is likely because it has been a go-to swiss-army knife of image and video creation for a long, long time. For some it was the only viable video editing application for heavy use (not that there weren’t other projects out there as well). This is partly due to to the fact that it integrates so much capability into a single project.
The part that we’re interested in for the context of Fotonut’s original question is the Video Sequence Editor (VSE). This is a very powerful (though often neglected) part of Blender that lets you arrange audio and video (and image!) assets along a timeline for rendering and some simple effects. Which is actually perfect for creating a simple HD slideshow of images, as we’ll see.
Blenders interface is likely to take some getting used to for newcomers (right-click!) but we’ll be focusing on a very small subset of the overall program—so hopefully nobody gets lost. The overall plan will be:
Setup the environment for video sequence editing
Include assets (images) and how to manipulate them on the timeline
Add effects such as cross-fades between images
Setup exporting options
There’s also an option of using a very helpful add-on for automatically resizing images to the correct size to maintain their aspect ratios. Luckily, Blender’s add-on system makes it trivially easy to set up.
On opening Blender for the first time we’re presented with the comforting view of the default cube in 3D space. Don’t get too cozy, though. We’re about to switch up to a different screen layout that’s already been created for us by default for Video Editing.
The main blender default view.
The developers were nice enough to include various default “Screen Layout” options for different tasks, and one of them happens to be for Video Editing. We can click on the screen layout option on the top menu bar and choose the one we want from the list (Video Editing):
Choosing a new Screen Layout option.
Our screen will then change to the new layout where the top left pane is the F-curve window, the top right is the video preview, the large center section is the sequencer, and the very bottom is a timeline. Blender will let you arrange, combine, and collapse all the various panes into just about any layout that you might want, including changing what each of them are showing. For our example we will mostly leave it all as-is with the exception of the F-curve pane, which we won’t be using and don’t need.
The Video Editing default layout.
What we can do now is to define what the resolution and framerate of our project should be. This is done in the Properties pane, which isn’t shown right now. So we will change the F-Curve pane into the Properties pane by clicking on the button shown in red above to change the panel type. We want to choose Properties from the options in the list:
Which will turn the old F-Curve pane into the Properties pane:
You’ll want to set the appropriate X and Y resolution for your intended output (don’t forget to set the scaling from the default 50% to 100% now as well) as well as your intended framerate. Common rates might be 23.976 (23.98), 25, 30, or even 60 frames per second. If your intended target is something like YouTube or an HD television you can probably safely use 30 or 60 (just remember that a higher frame rate means a longer render time!).
For our example I’m going to set the output resolution to 1920 × 1080 at 30fps.
Blender does need a little bit of help when it comes to using images on the sequence editor. It has a habit of scaling images to whatever the output resolution is set to (ignoring the original aspect ratios). This can be fixed by simply applying a transform to the images but normally requires us to manually compute and enter the correct scaling factors to get the images back to their original aspect ratios.
I did find a nice small add-on on this thread at blenderartists.org that binds some handy shortcuts onto the VSE for us. The author kgeogeo has the add-on hosted on Github, and you can download the Python file directly from here: VSE Transform Tool (you can Right-Click and save the link). Save the .py file somewhere easy to find.
To load the add-on manually we’re going to change the Properties panel to User Preferences:
Click on the Add-ons tab to open that window and at the bottom of the panel is an option to “Install from File…”. Click that and navigate to the VSE_Transform_Tool.py file that you downloaded previously.
Once loaded, you’ll still need to Activate the plugin by clicking on the box:
That’s it! You’re now all set up to begin adding images and creating a slideshow. You can set the User Preferences pane back to Properties if you want to.
Let’s have a look at adding images onto the sequencer.
You can add images by either choosing Add → Image from the VSE menu and navigating to your images location, choosing them:
Or by drag-and-dropping your images onto the sequencer timeline from Nautilus, Finder, Explorer, etc…
When you do, you’ll find that a strip now appears on the VSE window (purple in my case) that represents your image. You should also see a preview of your video in the top-right preview window (sorry for the subject).
At this point we can use the handy add-on we installed previously by Right-Clicking on the purple strip to make sure it’s activated and then hitting the “T” key on the keyboard. This will automatically add a transform to the image that scales it to the correct aspect ratio for you. A small green Transform strip will appear above your purple image strip now:
Your image should now also be scaled to fit at the correct aspect ratio.
If you scroll your mouse wheel in the VSE window, you will zoom in and out of time editor based on time (the x-axis in the sequencer window). You’ll notice that the time compresses or expands as you scroll the mouse wheel.
The middle-mouse button will let you pan around the sequencer.
The right-mouse button will select things. You can try this now by extending how long your image is displayed in the video. Right-Click on the small arrow on the end of the purple strip to activate it. A small number will appear above it indicating which frame it is currently on (26 in my example):
With the right handle active you can now either press “G” on the keyboard and drag the mouse to re-position the end of the strip, or Right-Click and drag to do the same thing. The timeline in seconds is shown along the bottom of the window for reference. If we wanted to let the image be visible for 5 seconds total, we could drag the end to the 5+00 mark on the sequencer window.
Since I set the framerate to 30 frames per second, I can also drag the end to frame 150 (30fps * 5s = 150 frames).
When you drag the image strip, the transform strip will automatically adjust to fit (so you don’t have to worry about it).
If you had selected the center of the image strip instead of the handle on one end and tried to move it, you would find that you can move the entire strip around instead of one end. This is how you can re-position image strips, which you may want to do when you add a second image to your sequencer.
Add a new image to your sequencer now following the same steps as above.
When I do, it adds a new strip back at the beginning of the timeline (basically where the current time is set):
I want to move this new strip so that it overlaps my first image by about half a second (or 15 frames). Then I will pull the right handle to resize the display time to about 5 seconds also.
Click on the new strip (center, not the ends), and press the “G” key to move it. Drag it right until the left side overlaps the previous image strip by a little bit:
When you click on the strip right handle to modify it’s length, notice the window on the far right of the VSE. The Edit Strip window should also show the strip “Length” parameter in case you want to change it by manually inputting a value (like 150):
I forgot to use the add-on to automatically fix the aspect ratio. With the strip selected I can press “T” at any time to invoke the add-on and fix the aspect ratio.
With the two image strips slightly overlapping, we now want to define a simple cross fade between the two images as a transition effect. This is actually something alreayd built into the Blender VSE for us, and is easy to add. We _do_ need to be careful to select the right things to get the transition working correctly, though.
Once you’ve added a transform effect to a strip, you’ll need to make sure that subsequent operations use the transform strip as opposed to the original image strip.
For instance, to add a cross fade transition between these two images, click the first image strip transform (green), then Shift-Click on the second image transform strip (green). Now they are both selected, so add a Gamma Cross by using the Add menu in the VSE (Add → Effect Strip… → Gamma Cross):
This will add a Gamma Cross effect as a new strip that is locked to the two images overlap. It will do a cross-fade between the two images for the duration of the overlap. You can Left-Click now and scrub over the cross-fade strip to see it rendered in the preview window if you’d like:
At any time you can also use the hotkey “Alt-A” to view a render preview. This may run slow if your machine is not super-fast, but it should run enough to give you a general sense of what you’ll get.
If you want to modify the transition effect by changing its length, you can just increase the overlap between the strips as desired (using the original image strip — if you try to drag the transform strip you’ll find it locked to the original image strip and won’t move).
You may notice on the VSE that there are vertical lines outside of which things will appear slightly grayed out. This is a visual indicator of the total start/end of the output. This is controlled via the Start and End frame settings on the timeline (bottom pane):
You’ll need to set the End value to match your last output frame from your video sequence. You can find this value by selecting the last strip in your sequence and pressing the “G” key: the start/end frame numbers of that last strip will be visible (you’ll want the last frame value, of course).
Current last frame of my video is 284
In my example above, my anticipated last frame should be 284, but the last render frame is currently set to 250. I would need to update that End frame to match my video to get output as expected.
Back on the Properties panel (assuming you set the top-left panel back to Properties earlier—if not do so now), if we scroll down a bit we should see a section dedicated to Output.
You can change the various output options here to do frame-by-frame dumps or to encode everything into a video container of some sort. You can set the output directory to be something different if you don’t want it rendered into /tmp here.
For my example I will encode the video with H.264:
By choosing this option, Blender will then expose a new section of the Properties panel for setting the Encoding options:
I will often use the H264 preset and will enable the Lossless Output checkbox option. If I don’t have the disk space to spare I can also set different options to shrink the resulting filesize down further. The Bitrate option will have the largest effect on final file size and image quality.
When everything is ready (or you just want to test it out), you can render your output by scrolling back to the top of the Properties window and pressing the Animation button, or by hitting Ctrl-F12.
This may seem overly complicated, but in reality much of what I covered here is the setup to get started and the settings for output. Once you’ve done this successfully it becomes pretty quick to use. One thing you can do is set up the environment the way you like it and then save the .blend file to use as a template for further work like this in the future. The next time you need to generate a slideshow you’ll have everything all ready to go and will only need to start adding images to the editor.
While looking for information on some VSE shortcuts I did run across a really interesting looking set of functions that I want to try out: the Blender Velvets. I’m going to go off and give it a good look when I get a chance as there’s quite a few interesting additions available.
While in London this past April I got a chance to hang out a bit with LWN.net editor and fellow countryman, Nathan Willis. (It sounds like the setup for a bad joke: “An Alabamian and Texan meet in a London pub…”). Which was awesome because even though we were both at LGM2014, we never got a chance to sit down and chat.
So it was super-exciting for me to hear from Nate about possibly doing a photowalk and Free Software photo workshop at the 2016 Texas Linux Fest, and as soon as I cleared it with my boss, I agreed!
My Boss
So… mosey on down to Austin, Texas on July 8-9 for Texas Linux Fest and join Akkana Peck and myself for a photowalk first thing of the morning on Friday (July 8) to be immediately followed by workshops from both of us. I’ll be talking about Free Software photography workflows and projects and Akkana will be focusing on a GIMP workshop.
Color Manipulation with the Colour Checker LUT Module
hanatos tinkering in darktable again...
I was lucky to get to spend some time in London with the darktable crew.
Being the wonderful nerds they are, they were constantly working on something while we were there.
One of the things that Johannes was working on was the colour checker module for darktable.
Having recently acquired a Fuji camera, he was working on matching color styles from the built-in rendering on the camera.
Here he presents some of the results of what he was working on.
This was originally published on the darktable blog, and is being republished here with permission. —Pat
unfortunately these are eat-it-or-die canned styles or icc lut profiles. you
have to apply them and be happy or tweak them with other tools. but can we
extract meaning from these presets? can we have understandable and tweakable
styles like these?
in a first attempt, i used a non-linear optimiser to control the parameters of
the modules in darktable’s processing pipeline and try to match the output of
such styles. while this worked reasonably well for some of pat’s film luts, it
failed completely on canon’s picture styles. it was very hard to reproduce
generic colour-mapping styles in darktable without parametric blending.
that is, we require a generic colour to colour mapping function. this should be
equally powerful as colour look up tables, but enable us to inspect it and
change small aspects of it (for instance only the way blue tones are treated).
in git master, there is a new module to implement generic colour mappings: the
colour checker lut module (lut: look up table). the following will be a
description how it works internally, how you can use it, and what this is good
for.
in short, it is a colour lut that remains understandable and editable. that is,
it is not a black-box look up table, but you get to see what it actually does
and change the bits that you don’t like about it.
the main use cases are precise control over source colour to target colour
mapping, as well as matching in-camera styles that process raws to jpg in a
certain way to achieve a particular look. an example of this are the fuji film
emulation modes. to this end, we will fit a colour checker lut to achieve their
colour rendition, as well as a tone curve to achieve the tonal contrast.
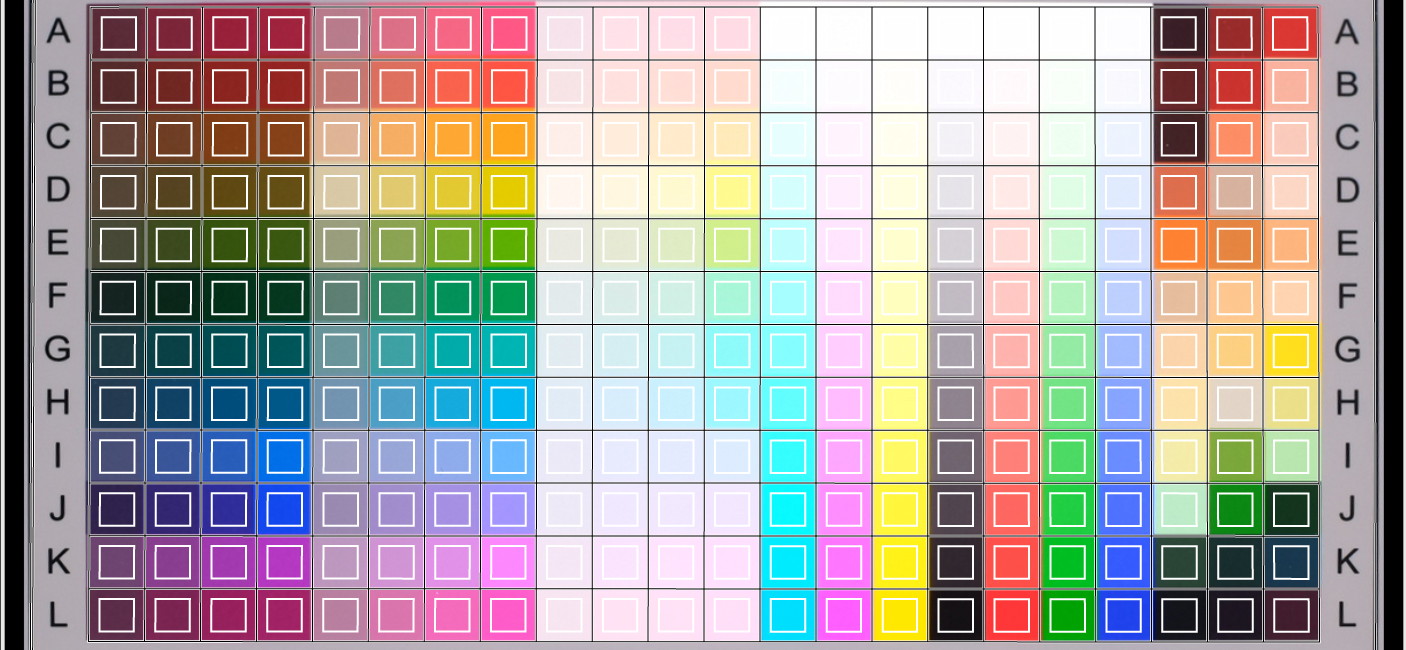
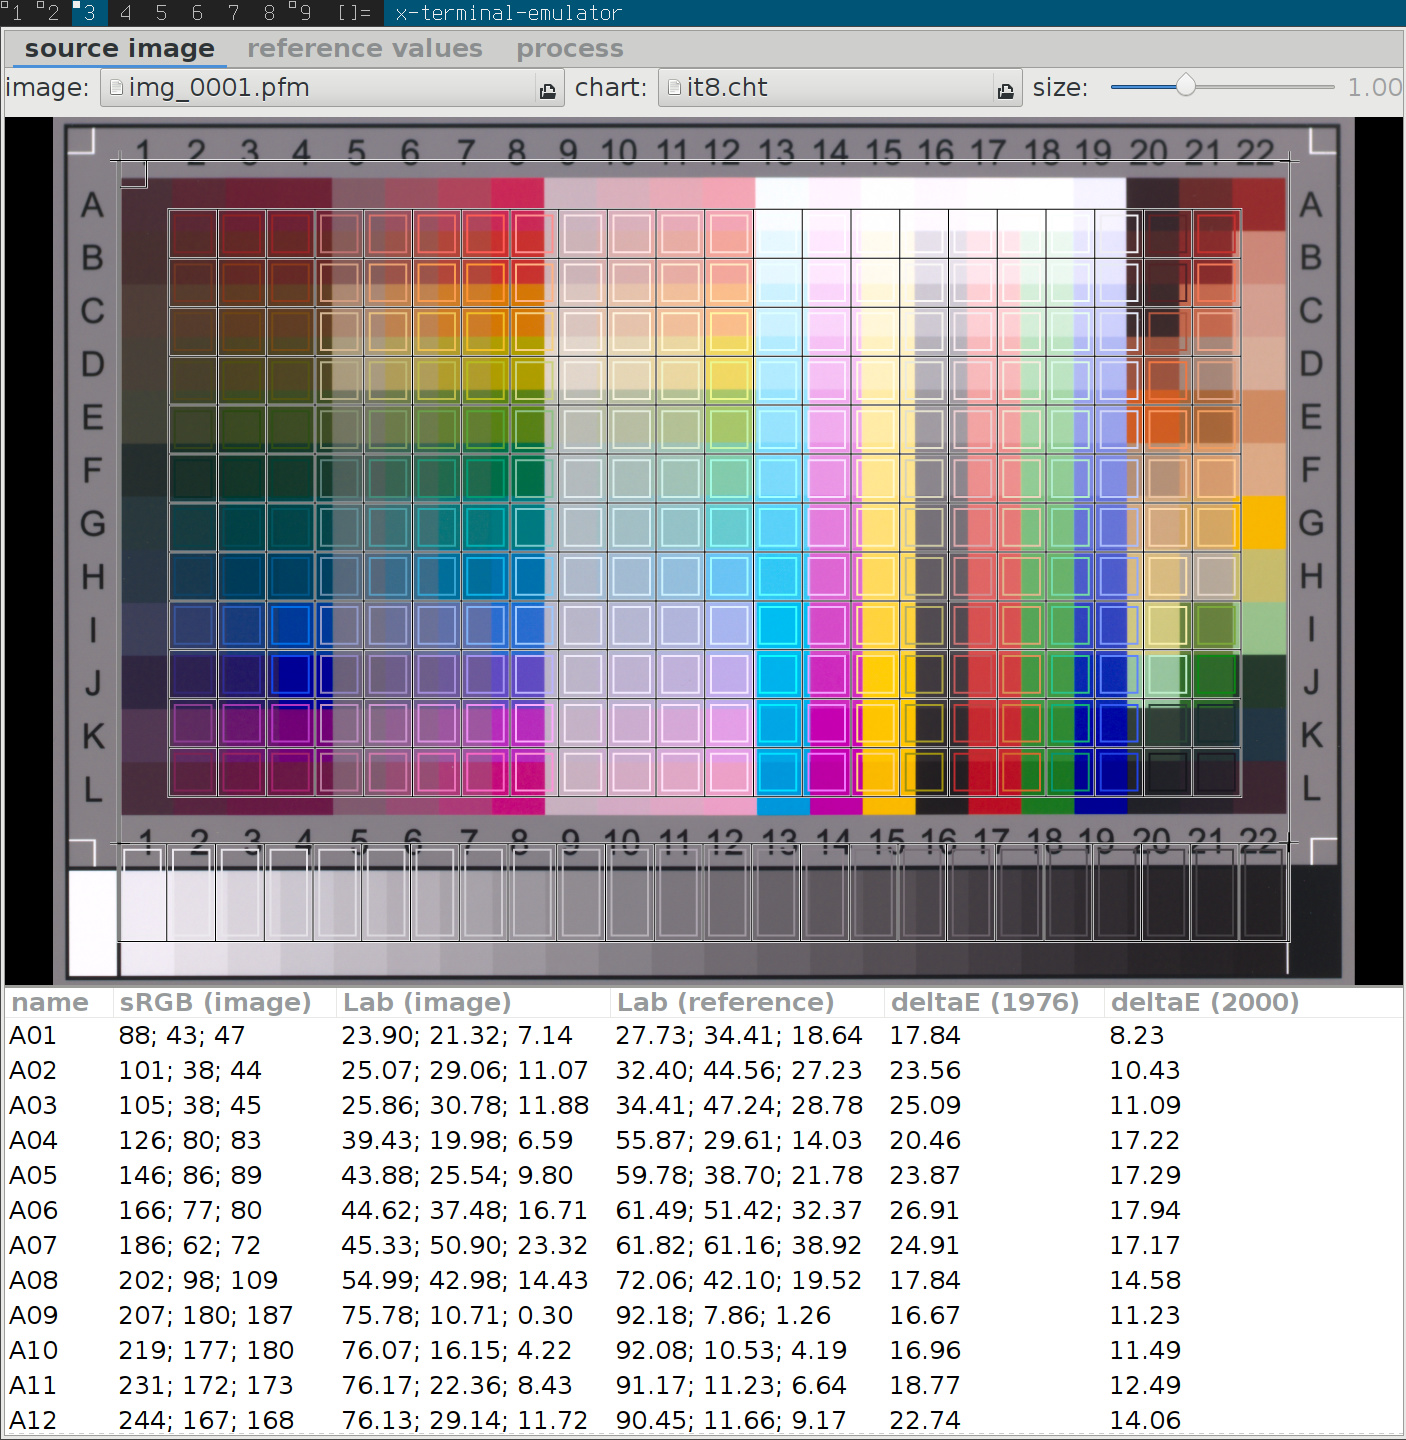
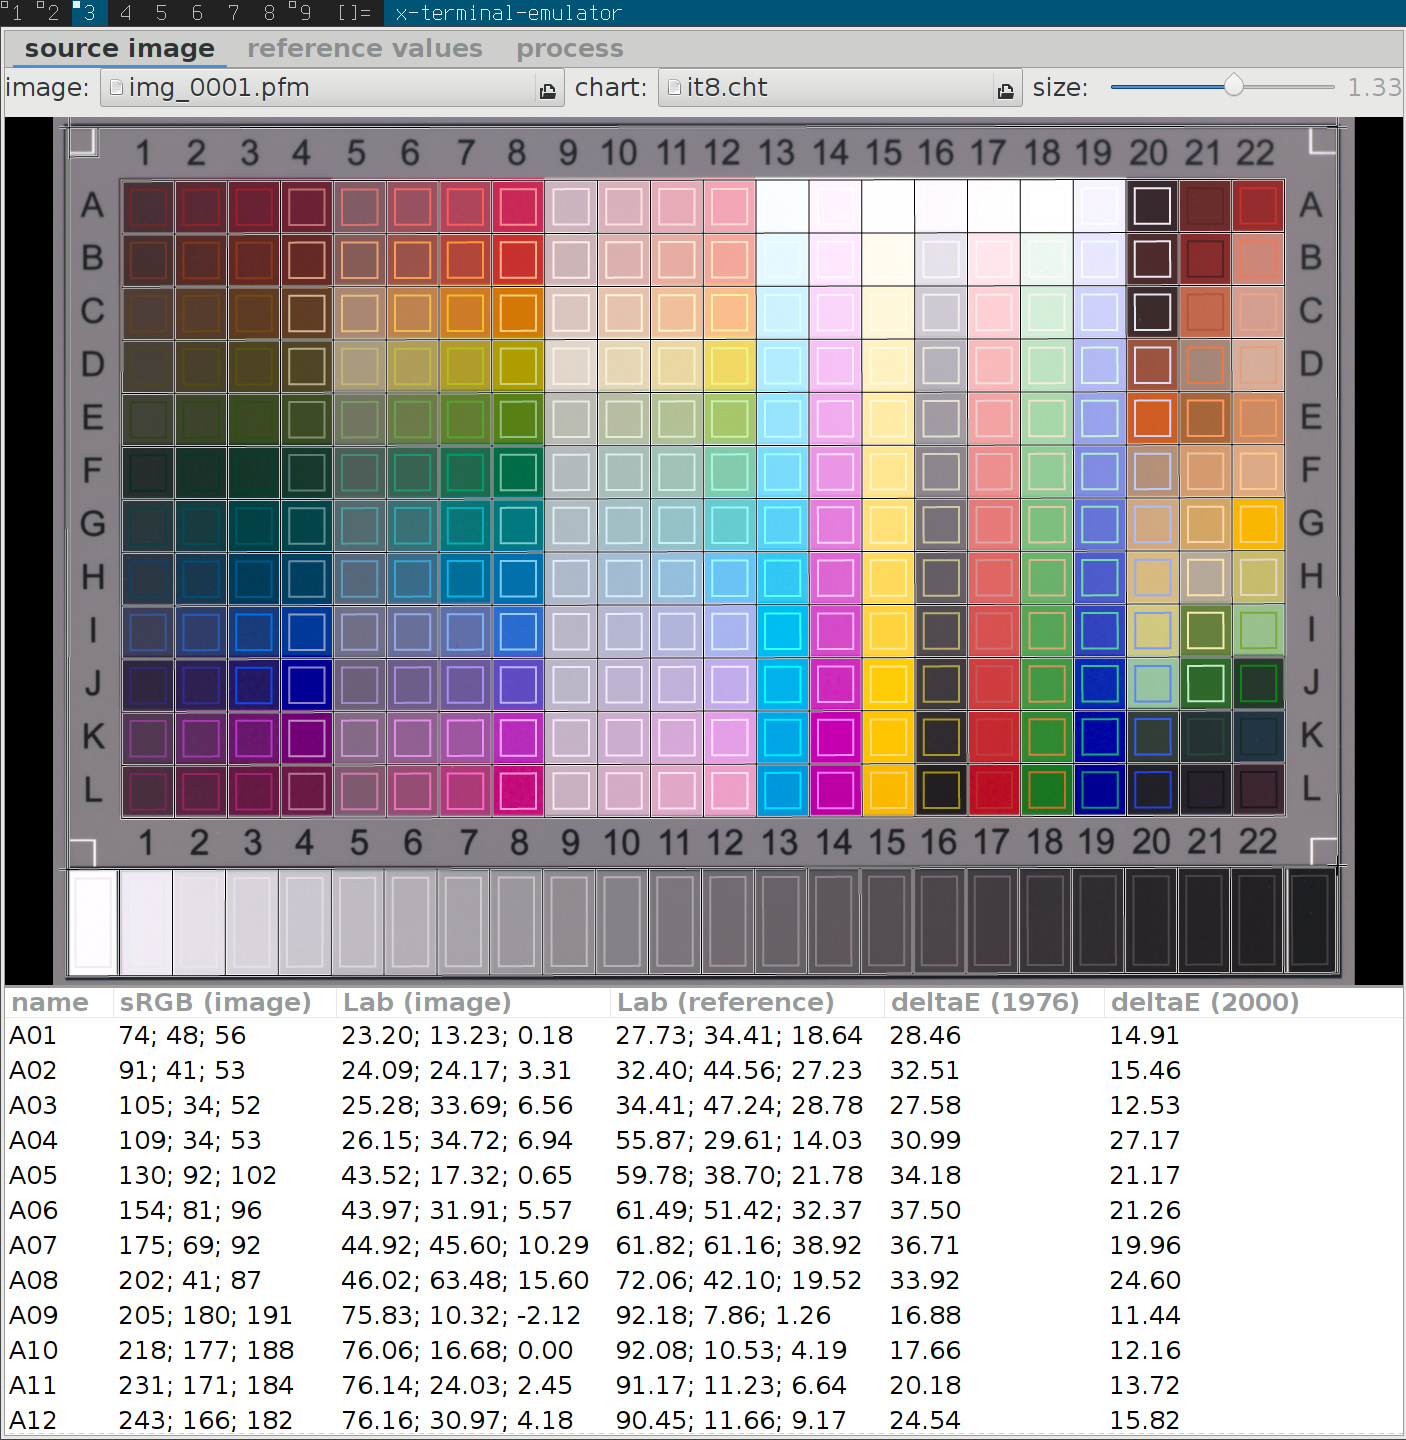
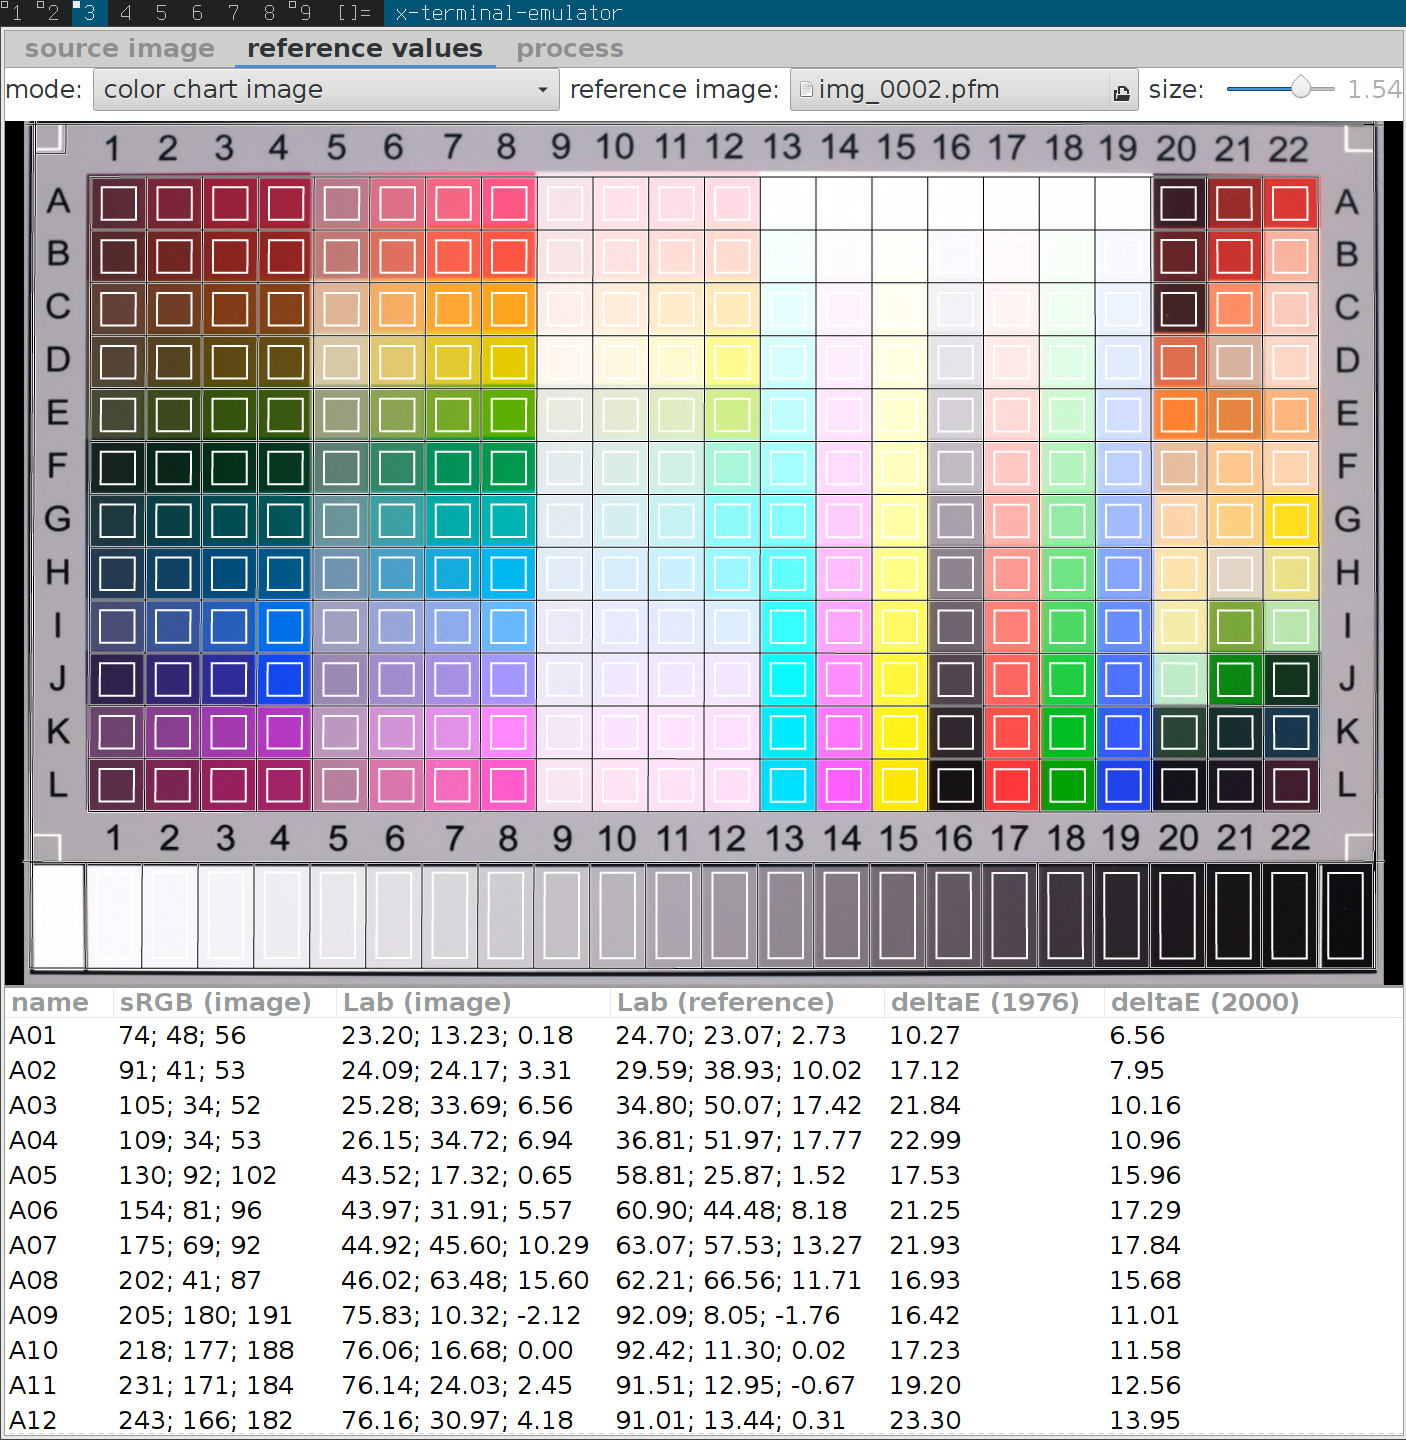
to create the colour lut, it is currently necessary to take a picture of an
it8 target (well, technically we support any similar target, but
didn’t try them yet so i won’t really comment on it). this gives us a raw
picture with colour values for a few colour patches, as well as a in-camera jpg
reference (in the raw thumbnail..), and measured reference values (what we know
it should look like).
to map all the other colours (that fell in between the patches on the chart) to
meaningful output colours, too, we will need to interpolate this measured
mapping.
we want to express a smooth mapping from input colours \(\mathbf{s}\) to target
colours \(\mathbf{t}\), defined by a couple of sample points (which will in our
case be the 288 patches of an it8 chart).
the following is a quick summary of what we implemented and much better
described in JP’s siggraph course [0].
radial basis functions are a means of interpolating between sample points
via
$$f(x) = \sum_i c_i\cdot\phi(| x - s_i|),$$
with some appropriate kernel \(\phi(r)\) (we’ll get to that later) and a set of
coefficients \(c_i\) chosen to make the mapping \(f(x)\) behave like we want it at
and in between the source colour positions \(s_i\). now to make
sure the function actually passes through the target colours, i.e. \(f(s_i) =
t_i\), we need to solve a linear system. because we want the function to take
on a simple form for simple problems, we also add a polynomial part to it. this
makes sure that black and white profiles turn out to be black and white and
don’t oscillate around zero saturation colours wildly. the system is
is the polynomial part, and \(\mathbf{d}\) are the coefficients to the polynomial
part. these are here so we can for instance easily reproduce \(t = s\) by setting
\(\mathbf{d} = (1, 1, 1, 0)\) in the respective row. we will need to solve this
system for the coefficients \(\mathbf{c}=(c_0,c_1,\cdots)^t\) and \(\mathbf{d}\).
many options will do the trick and solve the system here. we use singular value
decomposition in our implementation. one advantage is that it is robust against
singular matrices as input (accidentally map the same source colour to
different target colours for instance).
we didn’t yet define the radial basis function kernel. it turns out so-called
thin plate splines have very good behaviour in terms of low oscillation/low curvature
of the resulting function. the associated kernel is
$$\phi(r) = r^2 \log r.$$
note that there is a similar functionality in gimp as a gegl colour mapping
operation (which i believe is using a shepard-interpolation-like scheme).
we will feed this system with 288 patches of an it8 colour chart. that means,
with the added four polynomial coefficients, we have a total of 292
source/target colour pairs to manage here. apart from performance issues when
executing the interpolation, we didn’t want that to show up in the gui like
this, so we were looking to reduce this number without introducing large error.
indeed this is possible, and literature provides a nice algorithm to do so, which
is called orthogonal matching pursuit[1].
this algorithm will select the most important hand full of coefficients \(\in
\mathbf{c},\mathbf{d}\), to keep the overall error low. In practice we run it up
to a predefined number of patches (\(24=6\times 4\) or \(49=7\times 7\)), to make
best use of gui real estate.
when you select the module in darkroom mode, it should look something like the
image above (configurations with more than 24 patches are shown in a 7\(\times\)7 grid
instead). by default, it will load the 24 patches of a colour checker classic
and initialise the mapping to identity (no change to the image).
the grid shows a list of coloured patches. the colours of the patches are
the source points \(\mathbf{s}\).
the target colour \(t_i\) of the selected patch \(i\) is shown as
offset controlled by sliders in the ui under the grid of patches.
an outline is drawn around patches that have been altered, i.e. the source
and target colours differ.
the selected patch is marked with a white square, and the number shows
in the combo box below.
to interact with the colour mapping, you can change both source and target
colours. the main use case is to change the target colours however, and start
with an appropriate palette (see the presets menu, or download a style
somewhere).
you can change lightness (L), green-red (a), blue-yellow (b), or saturation
(C) of the target colour via sliders.
select a patch by left clicking on it, or using the combo box, or using the
colour picker
to change source colour, select a new colour from your image by using the
colour picker, and shift-left-click on the patch you want to replace.
to reset a patch, double-click it.
right-click a patch to delete it.
shift-left-click on empty space to add a new patch (with the currently
picked colour as source colour).
to process the following image i took of pat in the overground, i started with
the skin tones preset in the colour checker module (right click on nothing in
the gui or click on the icon with the three horizontal lines in the header and
select the preset).
then, i used the colour picker (little icon to the right of the patch# combo
box) to select two skin tones: very bright highlights and dark shadow tones.
the former i dragged the brightness down a bit, the latter i brightened up a
bit via the lightness (L) slider. this is the result:
in this image, i started with the fuji classic chrome-like style (see below for
a download link), to achieve the subdued look in the skin tones. then, i
picked the iris colour and saturated this tone via the saturation slider.
as a side note, the flash didn’t fire in this image (iso 800) so i needed to
stop it up by 2.5ev and the rest is all natural lighting..
as a starting point, i matched a colour checker lut interpolation function to
the in-camera processing of fuji cameras. these have the names of old film and
generally do a good job at creating pleasant colours. this was done using the
darktable-chart utility, by matching raw colours to the jpg output (both in Lab space in the darktable pipeline).
here is the link to the fuji styles, and how to use them.
i should be doing pat’s film emulation presets with this, too, and maybe
styles from other cameras (canon picture styles?). darktable-chart will
output a dtstyle file, with the mapping split into tone curve and colour
checker module. this allows us to tweak the contrast (tone curve) in isolation
from the colours (lut module).
these styles were created with the X100T model, and reportedly they work so/so
with different camera models. the idea is to create a Lab-space mapping which
is well configured for all cameras. but apparently there may be sufficient
differences between the output of different cameras after applying their colour
matrices (after all these matrices are just an approximation of the real camera
to XYZ mapping).
so if you’re really after maximum precision, you may have to create the styles
yourself for your camera model. here’s how:
this is to make sure we can process high-dynamic range images and not destroy
the bright spots with the lut. this is needed since the it8 does not deliver
any information out of the reflective gamut and for very bright input. to fix
wide gamut input, it may be needed to enable gamut clipping in the input colour
profile module when applying the resulting style to an image with highly
saturated colours. darktable-chart does that automatically in the style it
writes.
fix up style description in csv if you want
run darktable-chart --csv
outputs a .dtstyle with everything properly switched off, and two modules on: colour checker + tonecurve in Lab
when processing the list of colour pairs into a set of coefficients for the
thin plate spline, the program will output the approximation error, indicated
by average and maximum CIE 76 \(\Delta\)E for the input patches (the it8 in the
examples here). of course we don’t know anything about colours which aren’t
represented in the patch. the hope would be that the sampling is dense enough
for all intents and purposes (but nothing is holding us back from using a
target with even more patches).
for the fuji styles, these errors are typically in the range of mean \(\Delta
E\approx 2\) and max \(\Delta E \approx 10\) for 24 patches and a bit less for 49.
unfortunately the error does not decrease very fast in the number of patches
(and will of course drop to zero when using all the patches of the input chart).
provia 24:rank 28/24 avg DE 2.42189 max DE 7.57084
provia 49:rank 53/49 avg DE 1.44376 max DE 5.39751

astia-24:rank 27/24 avg DE 2.12006 max DE 10.0213
astia-49:rank 52/49 avg DE 1.34278 max DE 7.05165

velvia-24:rank 27/24 avg DE 2.87005 max DE 16.7967
velvia-49:rank 53/49 avg DE 1.62934 max DE 6.84697

classic chrome-24:rank 28/24 avg DE 1.99688 max DE 8.76036
classic chrome-49:rank 53/49 avg DE 1.13703 max DE 6.3298

mono-24:rank 27/24 avg DE 0.547846 max DE 3.42563
mono-49:rank 52/49 avg DE 0.339011 max DE 2.08548
it is possible to match the reference values of the it8 instead of a reference
jpg output, to calibrate the camera more precisely than the colour matrix
would.
there is a button for this in the darktable-chart tool
needs careful shooting, to match brightness of reference value closely.
at this point it’s not clear to me how white balance should best be handled here.
need reference reflectances of the it8 (wolf faust ships some for a few illuminants).
another next step we would like to take with this is to match real film footage
(porta etc). both reference and film matching will require some global exposure
calibration though.
[0] Ken Anjyo and J. P. Lewis and Frédéric Pighin, “Scattered data interpolation for computer graphics” in Proceedings of SIGGRAPH 2014 Courses, Article No. 27, 2014. pdf
[1] J. A. Tropp and A. C. Gilbert, “Signal Recovery From Random Measurements Via Orthogonal Matching Pursuit”, in IEEE Transactions on Information Theory, vol. 53, no. 12, pp. 4655-4666, Dec. 2007.
It was always my intention to make the entire PIXLS.US website available under a permissive license. The content is already all licensed Creative Commons, By Attribution, Share-Alike (unless otherwise noted). I just hadn’t gotten around to actually posting the site source.
Until now(ish). I say “ish“ because I apparently released the code back in April and am just now getting around to talking about it.
Also, we finally have a category specifically for all those darktable weenies on discuss!
I finally got around to pushing my code for this site up to Github on April 27 (I’m basing this off git logs because my memory is likely suspect). It took a while, but better late than never? I think part of the delay was a bit of minor embarrassment on my part for being so sloppy with the site code. In fact, I’m still embarrassed - so don’t laugh at me too hard (and if you do, at least don’t point while laughing too).
In fact, we’ve got a couple of other repositories under the Github Organization PIXLS.US including this website, presentation assets, lighting diagram SVG’s, and more. If you’ve got a Github account or wanted to join in with hacking at things, by all means send me a note and we’ll get you added to the organization asap.
Note: you don’t need to do anything special if you just want to grab the site code. You can do this quickly and easily with:
git clone https://github.com/pixlsus/website.git
You actually don’t even need a Github account to clone the repo, but you will need one if you want to fork it on Github itself, or to send pull-requests. You can also feel free to simply email/post patches to us as well:
Speaking of which, I wanted to give a special shout-out to community member @paperdigits (Mica), who has been active in sharing presentation materials in the Presentations repo and has been actively hacking at the website. Mica’s recommendations and pull requests are helping to make the site code cleaner and better for everyone, and I really appreciate all the help (even if I _am_ scared of change).
Yes, after member Claes asked the question on discuss about why we didn’t have a darktable category on the forums, I relented and created one. Normally I want to make sure that any category is going to have active people to maintain and monitor the topics there. I feel like having an empty forum can sometimes be detrimental to the perception of a project/community.
In this case, any topics in the darktable category will also show up in the more general Software category as well. This way the visibility and interactions are still there, but with the added benefit that we can now choose to see only darktable posts, ignore them, or let all those stinky users do what they want in there.
Besides, now we can say that we’ve sufficiently appeased Morgan Hardwood‘s organizational needs…
Community member and RawTherapee hacker Morgan Hardwood brings us a great tutorial + assets from one of his strolls near the Söderåsen National Park (Sweden!). Ofnuts is apparently trying to get me to burn the forum down by sharing his raw file of a questionable subject. After bugging David Tschumperlé he managed to find a neat solution to generating a median (pixel) blend of a large number of images without making your computer throw itself out a window.
So much neat content being shared for everyone to play with and learn from! Come see what everyone is doing!
Sometimes you’re just hanging out minding your own business and talking photography with friends and other Free Software nuts when someone comes running by and drops a great tutorial in your lap. Just as Morgan Hardwood did on the forums a few days ago!
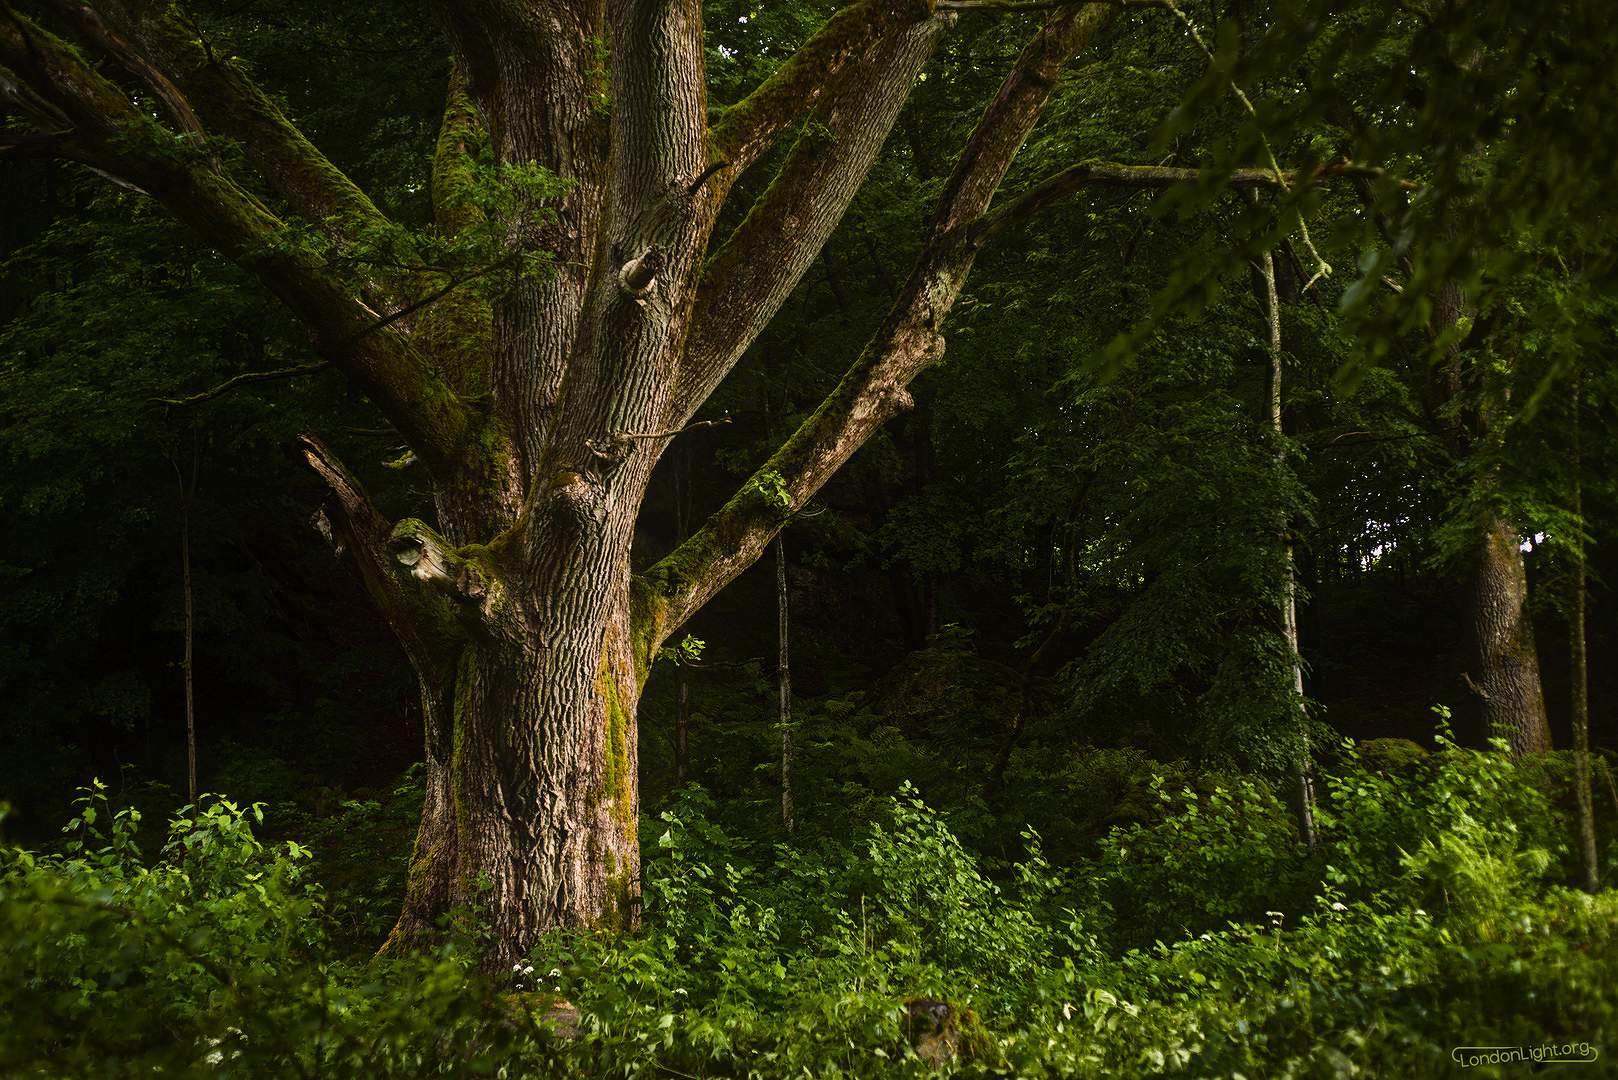
There is an old oak by the southern entrance to the Söderåsen National Park. Rumor has it that this is the oak under which Gandalf sat as he smoked his pipe and penned the famous saga about J.R.R. Tolkien. I don’t know about that, but the valley rabbits sure love it.
The image itself is a treat. I personally love images where the lighting does interesting things and there are some gorgeous things going on in this image. The diffused light flooding in under the canopy on the right with the edge highlights from the light filtering down make this a pleasure to look at.
Of course, Morgan doesn’t stop there. You should absolutely go read his entire post. He not only walks through his entire thought process and workflow starting at his rationale for lens selection (50mm f/2.8) all the way through his corrections and post-processing choices. To top it all off, he has graciously shared his assets for anyone to follow along! He provides the raw file, the flat-field, a shot of his color target + DCP, and finally his RawTherapee .PP3 file with all of his settings! Whew!
If you’re interested I urge you to go check out (and participate!) in his topic on the forums: Old Oak - A Tutorial.
Speaking of sharing material, Ofnuts has decided that he apparently wants me to burn the forums to the ground, put the ashes in a spaceship, fly the spaceship into the sun, and to detonate the entire solar system into a singularity. Why do I say this?
Kill it with fire!
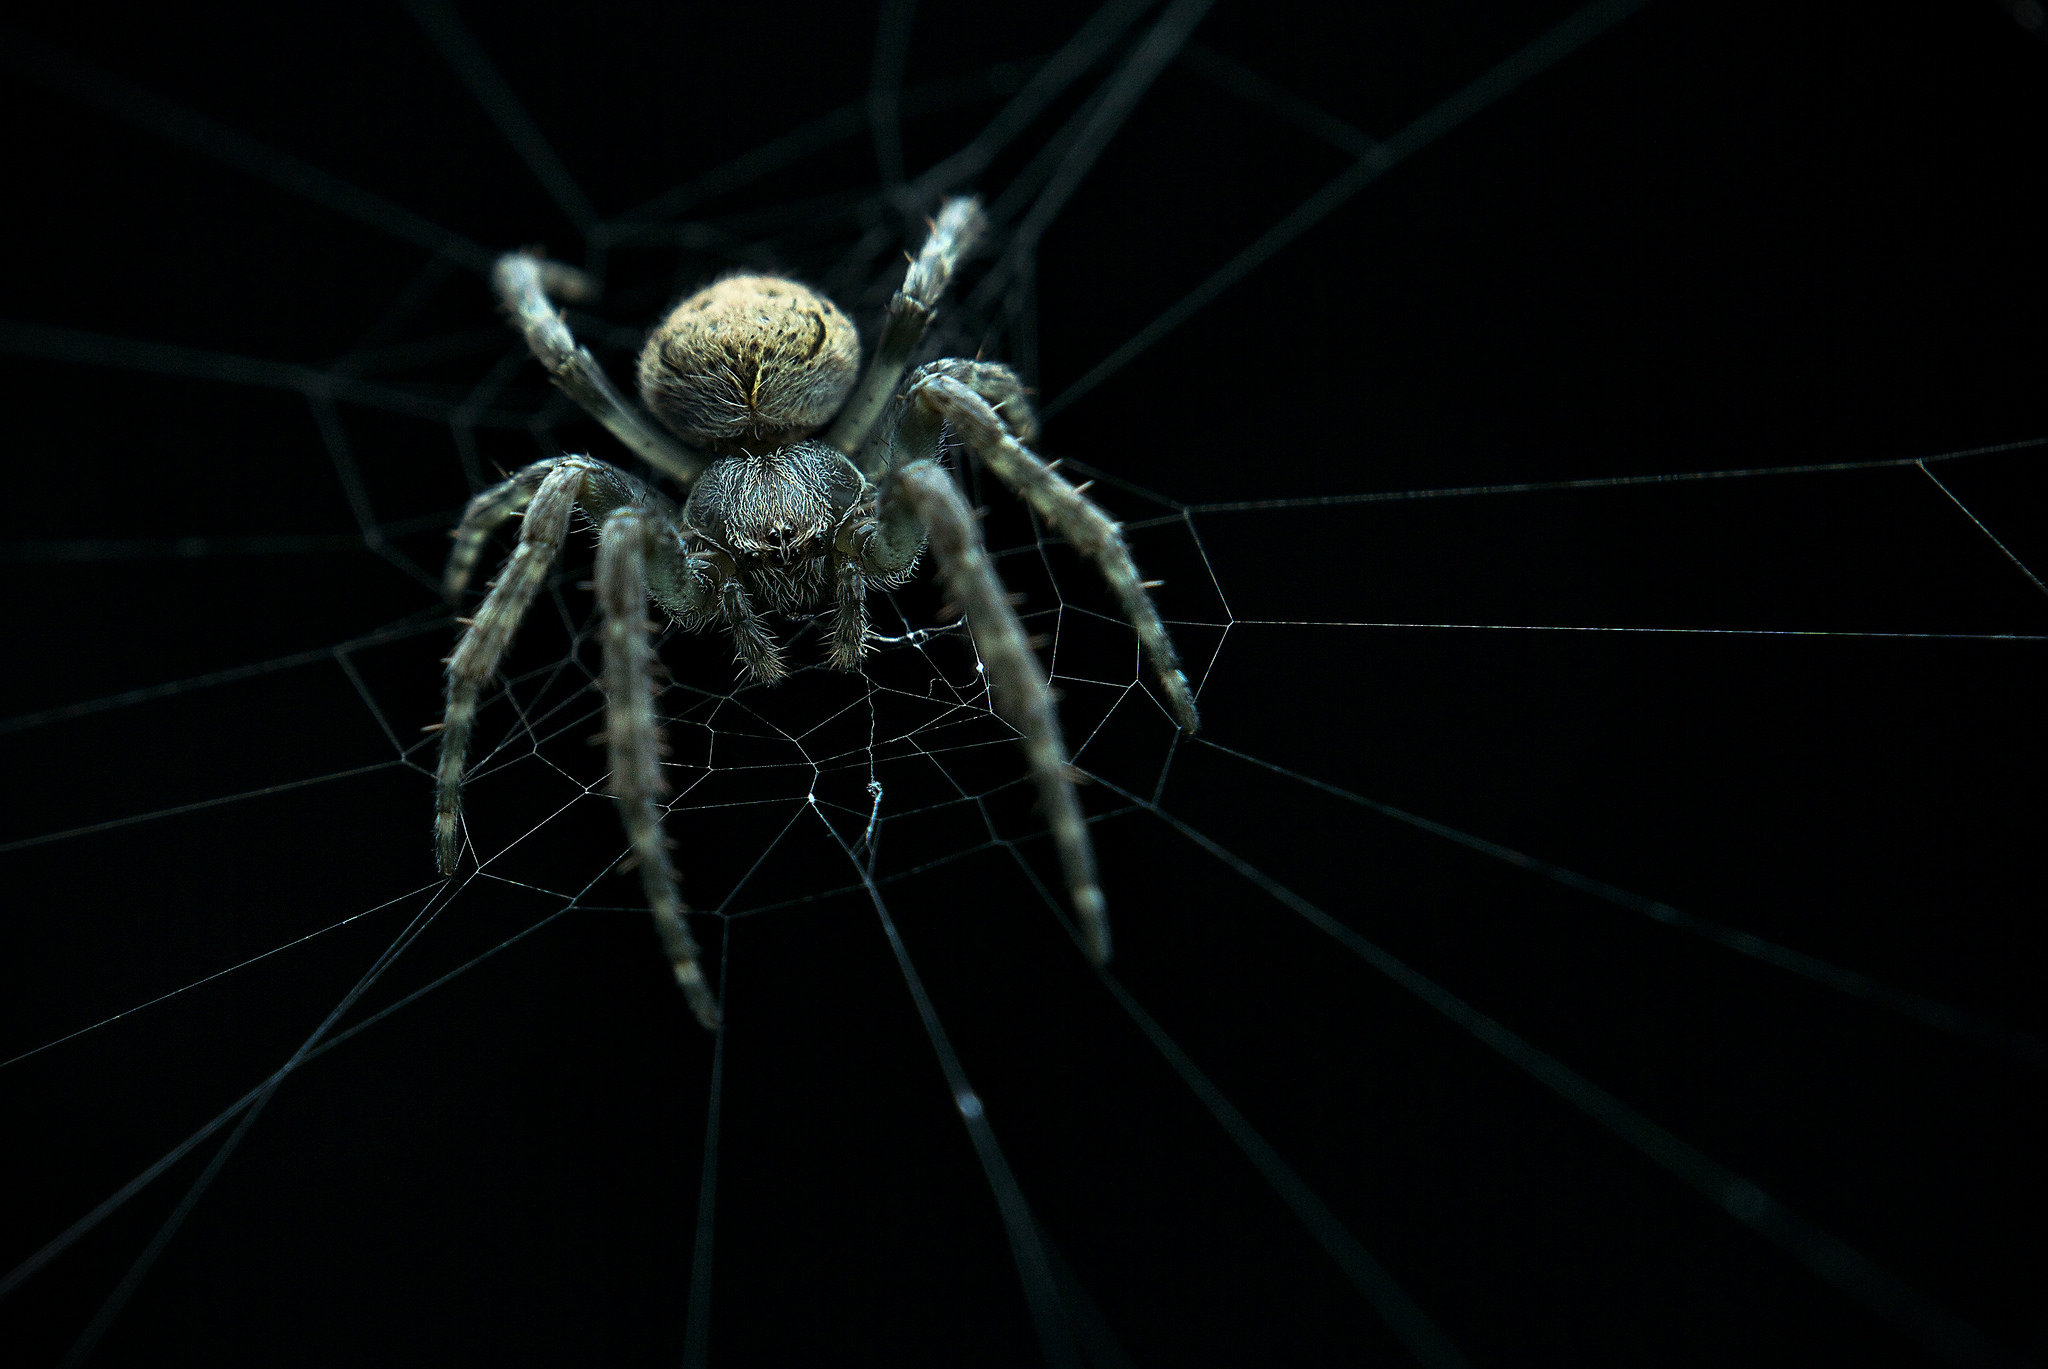
Because he started a topic appropriately entitled: “NSFPAOA (Not Suitable for Pat and Other Arachnophobes)”, in which he shares his raw .CR2 file for everyone to try their hand at processing that cute little spider above. There have already been quite a few awesome interpretations from folks in the community like:
A version by CarVac
By MLC/Morgin
By Jonas Wagner
By iarga
By PkmX
By Kees Guequierre
Of course, I had a chance to try processing it as well. Here’s what I ended up with:
Ahhhh, just writing this post is a giant bag of NOPE*. If you’d like to join in on the fun(?) and share your processing as well - go check out the topic!
Now let’s move on to something more cute and fuzzy, like an ALOT…
* I kid, I’m not really an arachnophobe (within reason), but I can totally see why someone would be.
The ALOT. Borrowed from Allie Brosh and here because I really wanted an excuse to include it.
I count myself lucky to have so many smart friends that I can lean on to figure out or help me do things (more on that in the next post). One of those friends is G’MIC creator and community member David Tschumperlé.
A few years back he helped me with some artwork I was generating with imagemagick at the time. I was averaging images together to see what an amalgamation would look like. For instance, here is what all of the Sports Illustrated swimsuit edition (NSFW) covers (through 2000) look like, all at once:
A natural progression of this idea was to consider doing a median blend vs. mean. The problem is that a mean average is very easy and fast to calculate as you advance through the image stack, but the median is not. This is relevant because I began to look at these for videos (in particular music videos), where the image stack was 5,000+ images for a video easily (that is ALOT of frames!).
It’s relatively easy to generate a running average for a series of numbers, but generating the median value requires that the entire stack of numbers be loaded and sorted. This makes it prohibitive to do on a huge number of images, particularly at HD resolutions.
So it’s awesome that, yet again, David has found a solution to the problem! He explains it in greater detail on his topic:
He basically chops up the image frame into regions, then computes the pixel-median value for those regions. Here’s an example of his result:
Mean/Median samples from P!nk - Try music video.
Now I can start utilizing median blends more often in my experiments, and I’m quite sure folks will find other interesting uses for this type of blending!
Attention: This article is a work in progress, based on my own practical experience up until the time of writing, so you may want to check back periodically to see if it has been updated.
This article outlines how you can calibrate and profile your display on Linux, assuming you have the right equipment (either a colorimeter like for example the i1 Display Pro or a spectrophotometer like for example the ColorMunki Photo). For a general overview of what color management is and details about some of its parlance you may want to read this before continuing.
A Fresh Start
First you may want to check if any kind of color management is already active on your machine, if you see the following then you’re fine:
$ xprop -display :0.0 -len 14 -root _ICC_PROFILE
_ICC_PROFILE: no such atom on any window.
However if you see something like this, then there is already another color management system active:
If this is the case you need to figure out what and why… For GNOME/Unity based desktops this is fairly typical, since they extract a simple profile from the display hardware itself via EDID and use that by default. I’m guessing KDE users may want to look into this before proceeding. I can’t give much advice about other desktop environments though, as I’m not particularly familiar with them. That said, I tested most of the examples in this article with XFCE 4.10 on Xubuntu 14.04 “Trusty”.
Display Types
Modern flat panel displays are comprised of two major components for purposes of our discussion, the backlight and the panel itself. There are various types of backlights, White LED (most common nowadays), CCFL (most common a few years ago), RGB LED and Wide Gamut CCFL, the latter two of which you’d typically find on higher end displays. The backlight primarily defines a displays gamut and maximum brightness. The panel on the other hand primarily defines the maximum contrast and acceptable viewing angles. Most common types are variants of IPS (usually good contrast and viewing angles) and TN (typically mediocre contrast and poor viewing angles).
Display Setup
There are two main cases, there are laptop displays, which usually allow for little configuration, and regular desktop displays. For regular displays there are a few steps to prepare your display to be profiled, first you need to reset your display to its factory defaults. We leave the contrast at its default value. If your display has a feature called dynamic contrast you need to disable it, this is critical, if you’re unlucky enough to have a display for which this cannot be disabled, then there is no use in proceeding any further. Then we set the color temperature setting to custom and set the R/G/B values to equal values (often 100/100/100 or 255/255/255). As for the brightness, set it to a level which is comfortable for prolonged viewing, typically this means reducing the brightness from its default setting, this will often be somewhere around 25–50 on a 0–100 scale. Laptops are a different story, often you’ll be fighting different lighting conditions, so you may want to consider profiling your laptop at its full brightness. We’ll get back to the brightness setting later on.
Before continuing any further, let the display settle for at least half an hour (as its color rendition may change while the backlight is warming up) and make sure the display doesn’t go into power saving mode during this time.
Another point worth considering is cleaning the display before starting the calibration and profiling process, do keep in mind that displays often have relatively fragile coatings, which may be deteriorated by traditional cleaning products, or easily scratched using regular cleaning cloths. There are specialist products available for safely cleaning computer displays.
You may also want to consider dimming the ambient lighting while running the calibration and profiling procedure to prevent (potential) glare from being an issue.
Software
If you’re in a GNOME or Unity environment it’s highly recommend to use GNOME Color Manager (with colord and argyll). If you have recent versions (3.8.3, 1.0.5, 1.6.2 respectively), you can profile and setup your display completely graphically via the Color applet in System Settings. It’s fully wizard driven and couldn’t be much easier in most cases. This is what I personally use and recommend. The rest of this article focuses on the case where you are not using it.
Xubuntu users in particular can get experimental packages for the latest argyll and optionally xiccd from my xiccd-testing PPAs. If you’re using a different distribution you’ll need to source help from its respective community.
Report On The Uncalibrated Display
To get an idea of the displays uncalibrated capabilities we use argyll’s dispcal:
$ dispcal -H -y l -R
Uncalibrated response:
Black level = 0.4179 cd/m^2
50%   level = 42.93 cd/m^2
White level = 189.08 cd/m^2
Aprox. gamma = 2.14
Contrast ratio = 452:1
White     Visual Daylight Temperature = 7465K, DE 2K to locus =  3.2
Here we see the display has a fairly high uncalibrated native whitepoint at almost 7500K, which means the display is bluer than it should be. When we’re done you’ll notice the display becoming more yellow. If your displays uncalibrated native whitepoint is below 6500K you’ll notice it becoming more blue when loading the profile.
Another point to note is the fairly high white level (brightness) of almost 190 cd/m2, it’s fairly typical to target 120 cd/m2 for the final calibration, keeping in mind that we’ll lose 10 cd/m2 or so because of the calibration itself. So if your display reports a brightness significantly higher than 130 cd/m2 you may want to considering turning down the brightness another notch.
Calibrating And Profiling Your Display
First we’ll use argyll’s dispcal to measure and adjust (calibrate) the display, compensating for the displays whitepoint (targeting 6500K) and gamma (targeting industry standard 2.2, more info on gamma here):
$ dispcal -v -m -H -y l -q l -t 6500 -g 2.2 asus_eee_pc_1215p
Next we’ll use argyll’s targen to generate measurement patches to determine its gamut:
$ targen -v -d 3 -G -f 128 asus_eee_pc_1215p
Then we’ll use argyll’s dispread to apply the calibration file generated by dispcal, and measure (profile) the displays gamut using the patches generated by targen:
$ dispread -v -N -H -y l -k asus_eee_pc_1215p.cal asus_eee_pc_1215p
Finally we’ll use argyll’s colprof to generate a standardized ICC (version 2) color profile:
$ colprof -v -D "Asus Eee PC 1215P" -C "Copyright 2013 Pascal de Bruijn" \
          -q m -a G -n c asus_eee_pc_1215p
Profile check complete, peak err = 9.771535, avg err = 3.383640, RMS = 4.094142
The parameters used to generate the ICC color profile are fairly conservative and should be fairly robust. They will likely provide good results for most use-cases. If you’re after better accuracy you may want to try replacing -a G with -a S or even -a s, but I very strongly recommend starting out using -a G.
You can inspect the contents of a standardized ICC (version 2 only) color profile using argyll’s iccdump:
$ iccdump -v 3 asus_eee_pc_1215p.icc
To try the color profile we just generated we can quickly load it using argyll’s dispwin:
$ dispwin -I asus_eee_pc_1215p.icc
Now you’ll likely see a color shift toward the yellow side. For some possibly aged displays you may notice it shifting toward the blue side.
If you’ve used a colorimeter (as opposed to a spectrophotometer) to profile your display and if you feel the profile might be off, you may want to consider reading this and this.
Report On The Calibrated Display
Next we can use argyll’s dispcal again to check our newly calibrated display:
$ dispcal -H -y l -r
Current calibration response:
Black level = 0.3432 cd/m^2
50%   level = 40.44 cd/m^2
White level = 179.63 cd/m^2
Aprox. gamma = 2.15
Contrast ratio = 523:1
White     Visual Daylight Temperature = 6420K, DE 2K to locus =  1.9
Here we see the calibrated displays whitepoint nicely around 6500K as it should be.
Loading The Profile In Your User Session
If your desktop environment is XDG autostart compliant, you may want to considering creating a .desktop file which will load the ICC color profile during all users session login:
Alternatively you could use colord and xiccd for a more sophisticated setup. If you do make sure you have recent versions of both, particularly for xiccd as it’s still a fairly young project.
First we’ll need to start xiccd (in the background), which detects your connected displays and adds it to colord‘s device inventory:
$ nohup xiccd &
Then we can query colord for its list of available devices:
$ colormgr get-devices
Next we need to query colord for its list of available profiles (or alternatively search by a profile’s full filename):
You should notice your displays color shift within a second or so (xiccd applies it asynchronously), assuming you haven’t already applied it via dispwin earlier (in which case you’ll notice no change).
If you suspect xiccd isn’t properly working, you may be able to debug the issue by stopping all xiccd background processes, and starting it in debug mode in the foreground:
$ killall xiccd
$ G_MESSAGES_DEBUG=all xiccd
Also in xiccd‘s case you’ll need to create a .desktop file to load xiccd during all users session login:
$ cat /etc/xdg/autostart/xiccd.desktop
[Desktop Entry]
Encoding=UTF-8
Name=xiccd
GenericName=X11 ICC Daemon
Comment=Applies color management profiles to your session
Exec=xiccd
Terminal=false
Type=Application
Categories=
OnlyShowIn=XFCE;
You’ll note that xiccd does not need any parameters, since it will query colord‘s database what profile to load.
If your desktop environment is not XDG autostart compliant, you need to ask them how to start custom commands (dispwin or xiccd respectively) during session login.
Dual Screen Caveats
Currently having a dual screen color managed setup is complicated at best. Most programs use the _ICC_PROFILE atom to get the system display profile, and there’s only one such atom. To resolve this issue new atoms were defined to support multiple displays, but not all applications actually honor them. So with a dual screen setup there is always a risk of applications applying the profile for your first display to your second display or vice versa.
So practically speaking, if you need a reliable color managed setup, you should probably avoid dual screen setups altogether.
That said, most of argyll’s commands support a -d parameter for selecting which display to work with during calibration and profiling, but I have no personal experience with them whatsoever, since I purposefully don’t have a dual screen setup.
Application Support Caveats
As my other article explains display color profiles consist of two parts, one part (whitepoint & gamma correction) is applied via X11 and thus benefits all applications. There is however a second part (gamut correction) that needs to be applied by the application. And application support for both input and display color management vary wildly. Many consumer grade applications have no color management awareness whatsoever.
Firefox can do color management and it’s half-enabled by default, read this to properly configure Firefox.
GIMP for example has display color management disabled by default, you need to enable it via its preferences.
Eye of GNOME has display color management enabled by default, but it has nasty corner case behaviors, for example when a file has no metadata no color management is done at all (instead of assuming sRGB input). Some of these issues seem to have been resolved on Ubuntu Trusty (LP #272584).
Darktable has display color management enabled by default and is one of the few applications which directly support colord and the display specific atoms as well as the generic _ICC_PROFILE atom as fallback. There are however a few caveats for darktable as well, documented here.
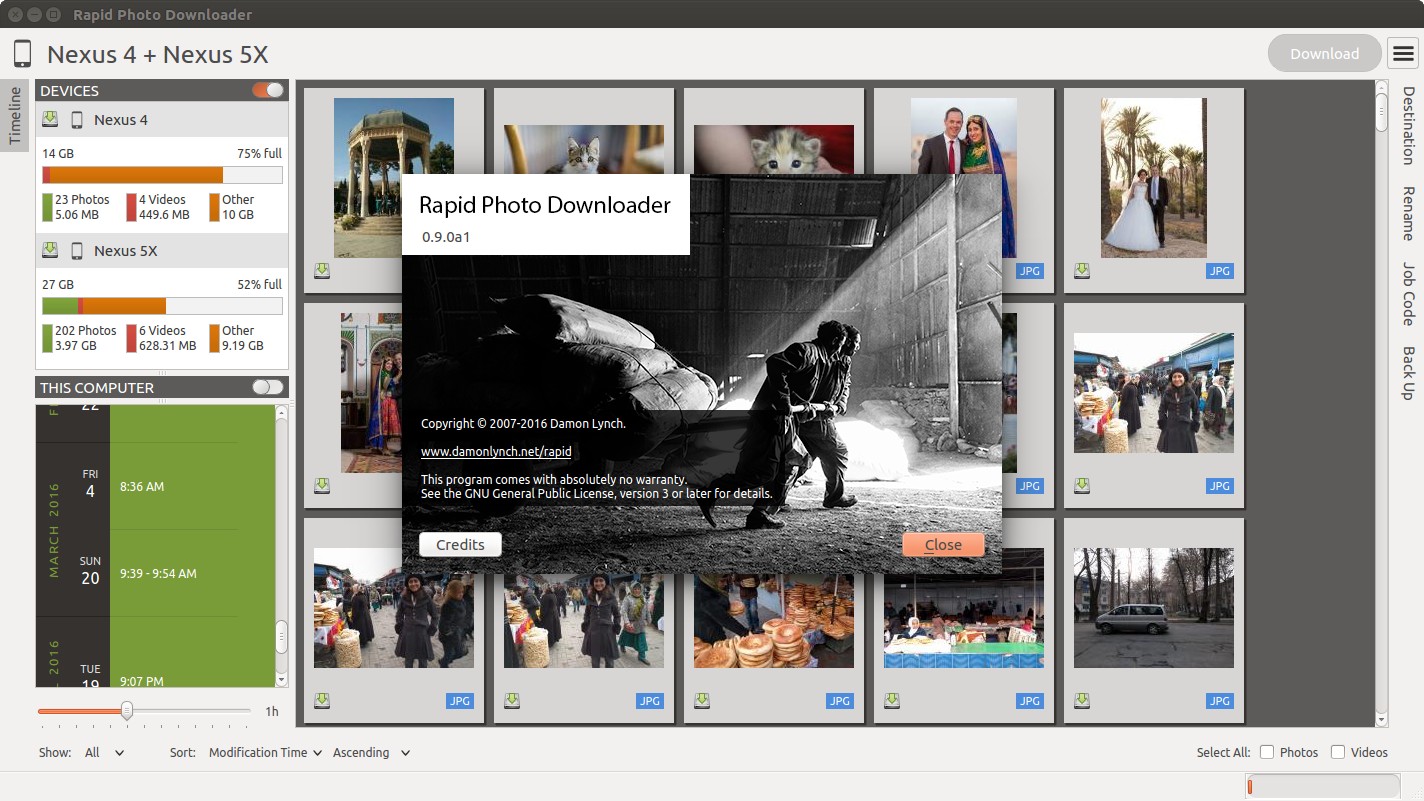
Community member Damon Lynch happens to make an awesome program called Rapid Photo Downloader in his “spare” time. In fact you may have heard mention of it as part of Riley Brandt’s“The Open Source Photography Course”*. It is a program that specializes in downloading photo and video from media in as efficient a manner as possible while extending the process with extra functionality.
* Riley donates a portion of the proceeds from his course to various projects, and Rapid Photo Downloader is one of them!
Some of the neat new features include being able to preview the download subfolder and storage space of devices before you download:
Also being able to download from multiple devices in parallel, including from all cameras supported by gphoto2:
There is much, much more in this release. Damon goes into much further detail on his post in the forum, copied here:
How about its Timeline, which groups photos and videos based on how much time elapsed between consecutive shots. Use it to identify photos and videos taken at different periods in a single day or
over consecutive days.
You can adjust the time elapsed between consecutive shots that is used to build the Timeline to match your shooting sessions.
For those who’ve used the older version, I’m copying and pasting from the ChangeLog, which covers most but not all changes:
New features compared to the previous release, version 0.4.11:
Every aspect of the user interface has been revised and modernized.
Files can be downloaded from all cameras supported by gPhoto2,
including smartphones. Unfortunately the previous version could download
from only some cameras.
Files that have already been downloaded are remembered. You can still select
previously downloaded files to download again, but they are unchecked by
default, and their thumbnails are dimmed so you can differentiate them
from files that are yet to be downloaded.
The thumbnails for previously downloaded files can be hidden.
Unique to Rapid Photo Downloader is its Timeline, which groups photos and
videos based on how much time elapsed between consecutive shots. Use it
to identify photos and videos taken at different periods in a single day
or over consecutive days. A slider adjusts the time elapsed between
consecutive shots that is used to build the Timeline. Time periods can be
selected to filter which thumbnails are displayed.
Thumbnails are bigger, and different file types are easier to
distinguish.
Thumbnails can be sorted using a variety of criteria, including by device
and file type.
Destination folders are previewed before a download starts, showing which
subfolders photos and videos will be downloaded to. Newly created folders
have their names italicized.
The storage space used by photos, videos, and other files on the devices
being downloaded from is displayed for each device. The projected storage
space on the computer to be used by photos and videos about to be
downloaded is also displayed.
Downloading is disabled when the projected storage space required is more
than the capacity of the download destination.
When downloading from more than one device, thumbnails for a particular
device are briefly highlighted when the mouse is moved over the device.
The order in which thumbnails are generated prioritizes representative
samples, based on time, which is useful for those who download very large
numbers of files at a time.
Thumbnails are generated asynchronously and in parallel, using a load
balancer to assign work to processes utilizing up to 4 CPU cores.
Thumbnail generation is faster than the 0.4 series of program
releases, especially when reading from fast memory cards or SSDs.
(Unfortunately generating thumbnails for a smartphone’s photos is painfully
slow. Unlike photos produced by cameras, smartphone photos do not contain
embedded preview images, which means the entire photo must be downloaded
and cached for its thumbnail to be generated. Although Rapid Photo Downloader
does this for you, nothing can be done to speed it up).
Thumbnails generated when a device is scanned are cached, making thumbnail
generation quicker on subsequent scans.
Libraw is used to render RAW images from which a preview cannot be extracted,
which is the case with Android DNG files, for instance.
Freedesktop.org thumbnails for RAW and TIFF photos are generated once they
have been downloaded, which means they will have thumbnails in programs like
Gnome Files, Nemo, Caja, Thunar, PCManFM and Dolphin. If the path files are being
downloaded to contains symbolic links, a thumbnail will be created for the
path with and without the links. While generating these thumbnails does slow the
download process a little, it’s a worthwhile tradeoff because Linux desktops
typically do not generate thumbnails for RAW images, and thumbnails only for
small TIFFs.
The program can now handle hundreds of thousands of files at a time.
Tooltips display information about the file including name, modification
time, shot taken time, and file size.
Right click on thumbnails to open the file in a file browser or copy the
path.
When downloading from a camera with dual memory cards, an emblem beneath the
thumbnail indicates which memory cards the photo or video is on
Audio files that accompany photos on professional cameras like the Canon
EOS-1D series of cameras are now also downloaded. XMP files associated with
a photo or video on any device are also downloaded.
Comprehensive log files are generated that allow easier diagnosis of
program problems in bug reports. Messages optionally logged to a
terminal window are displayed in color.
When running under Ubuntu‘s Unity desktop, a progress bar and count of files
available for download is displayed on the program’s launcher.
Status bar messages have been significantly revamped.
Determining a video’s correct creation date and time has been improved, using a
combination of the tools MediaInfo and ExifTool. Getting the right date and time
is trickier than it might appear. Depending on the video file and the camera that
produced it, neither MediaInfo nor ExifTool always give the correct result.
Moreover some cameras always use the UTC time zone when recording the creation
date and time in the video’s metadata, whereas other cameras use the time zone
the video was created in, while others ignore time zones altogether.
The time remaining until a download is complete (which is shown in the status
bar) is more stable and more accurate. The algorithm is modelled on that
used by Mozilla Firefox.
The installer has been totally rewritten to take advantage of Python‘s
tool pip, which installs Python packages. Rapid Photo Downloader can now
be easily installed and uninstalled. On Ubuntu, Debian and Fedora-like
Linux distributions, the installation of all dependencies is automated.
On other Linux distrubtions, dependency installation is partially
automated.
When choosing a Job Code, whether to remember the choice or not can be
specified.
Removed feature:
Rotate Jpeg images - to apply lossless rotation, this feature requires the
program jpegtran. Some users reported jpegtran corrupted their jpegs’
metadata – which is bad under any circumstances, but terrible when applied
to the only copy of a file. To preserve file integrity under all circumstances,
unfortunately the rotate jpeg option must therefore be removed.
Under the hood, the code now uses:
PyQt 5.4 +
gPhoto2 to download from cameras
Python 3.4 +
ZeroMQ for interprocess communication
GExiv2 for photo metadata
Exiftool for video metadata
Gstreamer for video thumbnail generation
Please note if you use a system monitor that displays network activity,
don’t be alarmed if it shows increased local network activity while the
program is running. The program uses ZeroMQ over TCP/IP for its
interprocess messaging. Rapid Photo Downloader’s network traffic is
strictly between its own processes, all running solely on your computer.
Missing features, which will be implemented in future releases:
Components of the user interface that are used to configure file
renaming, download subfolder generation, backups, and miscellaneous
other program preferences. While they can be configured by manually
editing the program’s configuration file, that’s far from easy and is
error prone. Meanwhile, some options can be configured using the command
line.
There are no full size photo and video previews.
There is no error log window.
Some main menu items do nothing.
Files can only be copied, not moved.
Of course, Damon doesn’t sit still. He quickly followed up the 0.9.0a1 announcement by announcing 0.9.0a2 which included a few bug fixes from the previous release:
Added command line option to import preferences from from an old program
version (0.4.11 or earlier).
Implemented auto unmount using GIO (which is used on most Linux desktops) and
UDisks2 (all those desktops that don’t use GIO, e.g. KDE).
Fixed bug while logging processes being forcefully terminated.
Fixed bug where stored sequence number was not being correctly used when
renaming files.
Fixed bug where download would crash on Python 3.4 systems due to use of Python
3.5 only math.inf
If you’ve been considering optimizing your workflow for photo import and initial sorting now is as good a time as any - particularly with all of the great new features that have been packed into this release! Head on over to the Rapid Photo Downloader website to have a look and see the instructions for getting a copy:
Remember, this is Alpha software still (though most of the functionality is all in place). If you do run into any problems, please drop in and let Damon know in the forums!
When the flowers are blooming, image filters abound!
A new version 1.7.1 “Spring 2016” of G’MIC (GREYC’s Magic for Image Computing),
the open-source framework for image processing, has been released recently (26 April 2016).
This is a great opportunity to summarize some of the latest advances and features over the last 5 months.
G’MIC is an open-source project started in August 2008. It has been developed in the
IMAGE team of the GREYC laboratory
from the CNRS (one of the major French public research institutes).
This team is made up of researchers and teachers specializing in the algorithms and mathematics of image processing.
G’MIC is released under the free software licence CeCILL
(GPL-compatible) for various platforms (Linux, Mac and Windows). It provides a set of various user interfaces
for the manipulation of generic image data, that is images or image sequences of
multispectral data being _2D_ or _3D_, and with high-bit precision
(up to 32bits floats per channel). Of course, it manages “classical” color images as well.
Logo and (new) mascot of the G’MIC project, the open-source framework for image processing.
Note that the project just got a redesign of its mascot Gmicky, drawn by David Revoy, a French illustrator well-known to free graphics lovers for being responsible for the great libre webcomics Pepper&Carott.
G’MIC is probably best known for it’s GIMPplug-in,
first released in 2009. Today, this popular GIMP extension proposes more than 460 customizable filters and effects
to apply on your images.
Overview of the G’MIC plug-in for GIMP.
But G’MIC is not a plug-in for GIMP only. It also offers a command-line interface, that can
be used in addition with the CLI tools from ImageMagick or
GraphicsMagick
(this is undoubtly the most powerful and flexible interface of the framework).
G’MIC also has a web service G’MIC Online to apply effects on your images
directly from a web browser. Other G’MIC-based interfaces also exist (ZArt,
a plug-in for Krita, filters for Photoflow…).
All these interfaces are based on the generic C++ libraries CImg and
libgmic which are portable, thread-safe and multi-threaded
(through the use of OpenMP).
Today, G’MIC has more than 900 functions to process images, all being
fully configurable, for a library of only approximately 150 kloc of source code.
It’s features cover a wide spectrum of the image processing field, with algorithms for
geometric and color manipulations, image filtering (denoising/sharpening with spectral, variational or
patch-based approaches…), motion estimation and registration, drawing of graphic primitives (up to 3d vector objects),
edge detection, object segmentation, artistic rendering, etc.
This is a versatile tool, useful to visualize and explore complex image data,
as well as elaborate custom image processing pipelines (see these
slides to get more information about
the motivations and goals of the G’MIC project).
Here we look at the descriptions of some of the most significant filters recently added. We illustrate their usage
from the G’MIC plug-in for GIMP. All of these filters are of course available from other interfaces as well
(in particular within the CLI tool gmic).
The filter Artistic / Brushify tries to transform an image into a painting.
Here, the idea is to simulate the process of painting with brushes on a white canvas. One provides a template image
and the algorithm first analyzes the image geometry (local contrasts and orientations of the contours), then
attempt to reproduce the image with a single brush that will be locally rotated and scaled accordingly to the
contour geometry.
By simulating enough of brushstrokes, one gets a “painted” version of the template image, which is more or less close to the original one,
depending on the brush shape, its size, the number of allowed orientations, etc.
All these settings being customizable by the user as parameters of the algorithm:
This filter allows thus to render a wide variety of painting effects.
Overview of the filter “Brushify” in the G’MIC plug-in GIMP. The brush that will be used by the algorithmis visible on the top left.
The animation below illustrates the diversity of results one can get with this filter, applied on the same
input picture of a lion. Various brush shapes and geometries have been supplied to the algorithm.
Brushify is computationally expensive so its implementation is parallelized (each core gives several brushstrokes simultaneously).
A few examples of renderings obtained with “Brushify” from the same template image, but with different brushes and parameters.
Note that it’s particularly fun to invoke this filter from the command line interface (using the option -brushify
available in gmic) to process a sequence of video frames
(see this example of “ brushified “ video):
G’MIC gets a new algorithm to reconstruct missing data in images. This is a classical problem in image processing,
often named “Image Inpainting“, and G’MIC already had a lot of
useful filters to solve this problem.
Here, the newly added interpolation method assumes only a sparse set of image data is known, for instance a few scattered pixels
over the image (instead of continuous chuncks of image data). The analysis and the reconstruction of the global
image geometry is then particularly tough.
The new option -solidify in G’MIC allows the reconstruction of dense image data from such a sparse sampling,
based on a multi-scale diffusion PDE’s-based technique.
The figure below illustrates the ability of the algorithm with an example of image reconstruction. We start from
an input image of a waterdrop,
and we keep only 2.7% of the image data (a very little amount of data!). The algorithm is able to reconstruct
a whole image that looks like the input, even if all the small details have not been
fully reconstructed (of course!). The more samples we have, the finer details we can recover.
Reconstruction of an image from a sparse sampling.
As this reconstruction technique is quite generic, several new G’MIC filters takes advantage of it:
Filter Repair / Solidify applies the algorithm in a direct manner, by reconstructing transparent areas
from the interpolation of opaque regions.
The animation below shows how this filter can be used to create an artistic blur on the image borders.
Overview of the “Solidify” filter, in the G’MIC plug-in for GIMP.
From an artistic point of view, there are many possibilities offered by this filters.
For instance, it becomes really easy to generate color gradients with complex shapes, as shown with the two examples below
(also in this video that details the whole process).
Using the “Solidify” filter of G’MIC to easily create color gradients with complex shapes (input images on the left, filter results on the right).
Filter Artistic / Smooth abstract uses same idea as the one with the waterdrop image:
it purposely sub-samples the image in a sparse way, by choosing keypoints mainly on the image edges, then use the reconstruction
algorithm to get the image back. With a low number of samples, the filter can only render a piecewise smooth image,
i.e. a smooth abstraction of the input image.
Overview of the “Smooth abstract” filter in the G’MIC plug-in for GIMP.
Filter Rendering / Gradient [random] is able to synthetize random colored backgrounds. Here again, the filter initializes
a set of colors keypoints randomly chosen over the image, then interpolate them with the new reconstruction algorithm.
We end up with a psychedelic background composed of randomly oriented color gradients.
Overview of the “Gradient [random]” filter in the G’MIC plug-in for GIMP.
Simulation of analog films : the new reconstruction algorithm also allowed a major improvement
for all the analog film emulation filters that have been present in G’MIC for years.
The section Film emulation/ proposes a wide variety of filters for this purpose. Their goal is to apply color transformations
to simulate the look of a picture shot by an analogue camera with a certain kind of film.
Below, you can see for instance a few of the 300 colorimetric transformations that are available in G’MIC.
A few of the 300+ color transformations available in G’MIC.
From an algorithmic point of view, such a color mapping is extremely simple to implement :
for each of the 300+ presets, G’MIC actually has an HaldCLUT, that is
a function defining for each possible color (R,G,B) (of the original image), a new color (R’,G’,B’) color to set
instead. As this function is not necessarily analytic, a HaldCLUT is stored in a discrete manner as a lookup table that gives
the result of the mapping for all possible colors of the RGB cube (that is 2^24 = 16777216 values
if we work with a 8bits precision per color component). This HaldCLUT-based color mapping is illustrated below for all values of the RGB color cube.
Principle of an HaldCLUT-based colorimetric transformation.
This is a large amount of data: even by subsampling the RGB space (e.g. with 6 bits per component) and compressing the corresponding HaldCLUT file,
you ends up with approximately 200 and 300 kB for each mapping file.
Multiply this number by 300+ (the number of available mappings in G’MIC), and you get a total of 85MB of data, to store all these color transformations.
Definitely not convenient to spread and package!
The idea was then to develop a new lossy compression technique focused on HaldCLUT files, that is volumetric discretised vector-valued functions which are piecewise smooth by nature.
And that what has been done in G’MIC, thanks to the new sparse reconstruction algorithm. Indeed, the reconstruction technique also works with _3D_ image data (such as a HaldCLUT!), so
one simply has to extract a sufficient number of significant keypoints in the RGB cube and interpolate them afterwards to allow the reconstruction of a whole HaldCLUT
(taking care to have a reconstruction error small enough to be sure that
the color mapping we get with the compressed HaldCLUT is indistinguishable from the non-compressed one).
How the decompression of an HaldCLUT now works in G’MIC, from a set of colored keypoints located in the RGB cube.
Thus, G’MIC doesn’t need to store all the color data from a HaldCLUT, but only a sparse sampling of it (i.e. a sequence of { rgb_keypoint, new_rgb_color }).
Depending on the geometric complexity of the HaldCLUTs to encode, more or less keypoints are necessary (roughly from _30_ to 2000).
As a result, the storage of the 300+HaldCLUTs in G’MIC requires now only 850 KiB of data (instead of 85 MiB), that is a compression gain of 99% !
That makes the whole HaldCLUT data storable in a single file that is easy to ship with the G’MIC package. Now, a user can then apply all the G’MIC color transformations
while being offline (previously, each HaldCLUT had to be downloaded separately from the G’MIC server when requested).
It looks like this new reconstruction algorithm from sparse samples is really great, and no doubts it will be used in other filters in the future.
Filter Arrays & tiles / Make seamless [patch-based] tries to transform an input texture to make it tileable, so that it can be duplicated as tiles along the horizontal and vertical axes
without visible seams on the borders of adjacent tiles.
Note that this is something that can be extremely hard to achieve, if the input texture has few auto-similarity or glaring luminosity changes spatially.
That is the case for instance with the “Salmon” texture shown below as four adjacent tiles (configuration 2x2) with a lighting that goes from dark (on the left) to bright (on the right).
Here, the algorithm modifies the texture so that the tiling shows no seams, but where the aspect of the original texture is preserved as much as possible
(only the texture borders are modified).
Overview of the “Make Seamless” filter in the G’MIC plug-in for GIMP.
We can imagine some great uses of this filter, for instance in video games, where texture tiling is common to render large virtual worlds.
Result of the “Make seamless” filter of G’MIC to make a texture tileable.
A “new” filter Details / Split details [wavelets] has been added to decompose an image into several levels of details.
It is based on the so-called “à trous” wavelet decomposition.
For those who already know the popular Wavelet Decompose plug-in for GIMP, there won’t be so much novelty here, as it is mainly the same kind of
decomposition technique that has been implemented.
Having it directly in G’MIC is still a great news: it offers now a preview of the different scales that will be computed, and the implementation is parallelized to take advantage of multiple cores.
Overview of the wavelet-based image decomposition filter, in the G’MIC plug-in for GIMP.
The filter outputs several layers, so that each layer contains the details of the image at a given scale. All those layers blended together gives the original image back.
Thus, one can work on those output layers separately and modify the image details only for a given scale. There are a lot of applications for this kind of image decomposition,
one of the most spectacular being the ability to retouch the skin in portraits : the flaws of the skin are indeed often present in layers with middle-sized scales, while
the natural skin texture (the pores) are present in the fine details. By selectively removing the flaws while keeping the pores, the skin aspect stays natural after the retouch
(see this wonderful link for a detailed tutorial about skin retouching techniques, with GIMP).
Using the wavelet decomposition filter in G’MIC for removing visible skin flaws on a portrait.
G’MIC is also well known to offer a wide range of algorithms for image denoising and smoothing (currently more than a dozen). And he got one more !
Filter Repair / Smooth [patch-pca] proposed a new image denoising algorithm that is both efficient and computationally intensive (despite its multi-threaded implementation, you
probably should avoid it on a machine with less than 8 cores…).
In return, it sometimes does magic to suppress noise while preserving small details.
Result of the new patch-based denoising algorithm added to G’MIC.
The Droste effect (also known as “mise en abyme“ in art) is the effect of a picture appearing within itself recursively.
To achieve this, a new filter Deformations / Continuous droste has been added into G’MIC. It’s actually a complete rewrite of the popular Mathmap’s
Droste filter that has existed for years.
Mathmap was a very popular plug-in for GIMP, but it seems to be not maintained anymore. The Droste effect was one of its most iconic and complex filter.
Martin “Souphead”, one former user of Mathmap then took the bull by the horns and converted the complex code of this filter specifically into a G’MIC script,
resulting in a parallelized implementation of the filter.
Overview of the converted “Droste” filter, in the G’MIC plug-in for GIMP.
This filter allows all artistic delusions. For instance, it becomes trivial to create the result below in a few steps: create a selection around the clock, move it on a transparent background, run the Droste filter,
et voilà!.
A simple example of what the G’MIC “Droste” filter can do.
The filter Deformations / Equirectangular to nadir-zenith is another filter converted from Mathmap to G’MIC.
It is specifically used for the processing of panoramas: it reconstructs both the
Zenith and the
Nadir regions of a panorama so that they can be easily modified
(for instance to reconstruct missing parts), before being reprojected back into the input panorama.
Overview of the “Deformations / Equirectangular to nadir-zenith” filter in the G’MIC plug-in for GIMP.
Morgan Hardwood has wrote a quite detailled tutorial,
here on pixls.us,
about the reconstruction of missing parts in the Zenith/Nadir of an equirectangular panorama. Check it out!
Finally, here are other highlights about the G’MIC project:
Filter Rendering / Kitaoka Spin Illusion is another Mathmap filter converted to G’MIC by Martin “Souphead”. It generates a certain kind of
optical illusions as shown below (close your eyes if you are epileptic!)
Result of the “Kitaoka Spin Illusion” filter.
Filter Colors / Color blindness transforms the colors of an image to simulate different types of color blindness.
This can be very helpful to check the accessibility of a web site or a graphical document for colorblind people.
The color transformations used here are the same as defined on Coblis,
a website that proposes to apply this kind of simulation online. The G’MIC filter gives strictly identical results, but it ease
the batch processing of several images at once.
Overview of the colorblindness simulation filter, in the G’MIC plug-in for GIMP.
Since a few years now, G’MIC has its own parser of mathematical expression, a really convenient module to perform complex calculations when applying image filters
This core feature gets new functionalities: the ability to manage variables that can be complex, vector or matrix-valued, but also the creation of
user-defined mathematical functions. For instance, the classical rendering of the Mandelbrot fractal set
(done by estimating the divergence of a sequence of complex numbers) can be implemented like this, directly on the command line:
$ gmic 512,512,1,1,"c = 2.4*[x/w,y/h] - [1.8,1.2]; z = [0,0]; for (iter = 0, cabs(z)<=2 && ++iter<256, z = z**z + c); 6*iter" -map 7,2
Using the G’MIC math evaluator to implement the rendering of the Mandelbrot set, directly from the command line!_
This clearly enlarge the math evaluator ability, as you are not limited to scalar variables anymore. You can now create complex filters which are able to
solve linear systems or compute eigenvalues/eigenvectors, and this, for each pixel of an input image.
It’s a bit like having a micro-(micro!)-Octave inside G’MIC.
Note that the Brushify filter described earlier uses these new features extensively.
It’s also interesting to know that the G’MIC math expression evaluator has its own JIT compiler
to achieve a fast evaluation of expressions when applied on thousands of image values simultaneously.
Another great contribution has been proposed by Tobias Fleischer, with the creation of a new _C_
API to invoke the functions of the libgmic library
(which is the library containing all the G’MIC features, initially available through a C++API only).
As the _C_ ABI is standardized (unlike C++),
this basically means G’MIC can be interfaced more easily with languages other than C++.
In the future, we can imagine the development of G’MICAPIs for languages such as Python for instance.
Tobias is currently using this new _C_ API to develop G’MIC-based plug-ins compatible with the OpenFX standard.
Those plug-ins should be usable indifferently in video editing software such as After effects, Sony Vegas Pro
or Natron. This is still an on-going work though.
Overview of some G’MIC-based OpenFX plug-ins, running under Natron.
Another contributor Robin “Starfall Robles” started to develop a Python script
to provide some of the G’MIC filters directly in the Blender video sequence editor.
This work is still in a early stage, but you can already apply different G’MIC effects on image sequences (see this video for a demonstration).
Overview of a dedicated G’MIC script running within the Blender VSE.
You can find out G’MIC filters also in the opensource nonlinear video editor Flowblade, thanks to the hard work of
Janne Liljeblad (Flowblade project leader).
Here again, the goal is to allow the application of G’MIC effects and filters directly on image sequences, mainly for artistic purposes
(as shown in this video or this one).
Overview of a G’MIC filter applied under Flowblade, a nonlinear video editor.
As you see, the G’MIC project is doing well, with an active development and cool new features added months after months.
You can find and use interfaces to G’MIC in more and more opensource software, as
GIMP,
Krita,
Blender,
Photoflow,
Flowblade,
Veejay,
EKD and
Natron in a near future (at least we hope so!).
At the same time, we can see more and more external resources available for G’MIC : tutorials, blog articles
(here,
here,
here,…),
or demonstration videos
(here,
here,
here,
here,…).
This shows the project becoming more useful to users of opensource software for graphics and photography.
The development of version 1.7.2 already hit the ground running, so stay tuned and visit the official G’MICforum on pixls.us
to get more info about the project developement and get answers to your questions.
Meanwhile, feel the power of free software for image processing!
This trip report is long overdue, but I wanted to process some of my images to share with everyone before I posted.
It had been a couple of years since I had an opportunity to travel and meet with the GIMP team again (Leipzig was awesome) so I was really looking forward to this trip. I missed the opportunity to head up to the great white North for last years meeting in Toronto.
Passport? Check! Magazine? Check! Ready to head to London!
I was going to attend the pre-LGM photowalk again this year so this time I decided to pack some bigger off-camera lighting modifiers for everyone to play with. Here’s a neat travelling photographer pro-tip: most airlines will let you carry on an umbrella as a “freebie” item. They just don’t specify that it has to be an umbrella to keep the rain off you. So I carried on my big Photek Softlighter II (luckily my light stands fit in my checked luggage). Just be sure not to leave it behind somewhere (which I was paranoid about for most of my trip). Luckily I was only changing planes in Atlanta.
The new ‘futristic’ looking Atlanta airport international terminal.
A couple of (bad) movies and hours later I was in Heathrow. I figured it wouldn’t be much trouble getting through border control.
I may have been a little optimistic about that.
The Border Force agent was quite nice and super inquisitive. So much so that I actually began to worry at some point (I think I must have spent almost 20 minutes talking to her) that she might not let me in!
She kept asking what I was coming to London for and I kept trying to explain to her what a “Libre Graphics Meeting“ was. This was almost a tragic comedy. The idea of Free Software did not seem to compute to her and I was sorry I had even made the passing mention. Her attention then turned to my umbrella and photography. What was I there to photograph? Who? Why? (Come to think of it, I should start asking myself those same questions more often… It was an existential visit to the border control.)
In the end I think she got bored with my answers and figured that I was far too awkward to be a threat to anything. Which pretty much sums up my entire college dating life.
In what I hope will become a tradition we had our photowalk the day before LGM officially kicked off and we could not have asked for a better day of weather! It was partly cloudy and just gorgeous (pretty much the complete opposite to what I was expecting for London weather).
I want to thank Ruth Catlow (http://ruthcatlow.net/) for allowing us to use the awesome space at Furtherfield Commons in Finsbury Park as a base for our photowalk! They were amazingly accommodating and we had a wonderful time chatting in general about art and what they were up to at the gallery and space.
They have some really neat things going on at the gallery and space so be sure to check them out if you can!
This is one of my favorite things about being able to attend LGM. I get to take a stroll and talk about photography with friends that I only usually get to interact with through an IRC window. I also feel like I can finally contribute something back to these awesome people that provide software I use every day.
Mairi between Simon and myself (I’m holding a reflector for him).
Photo by Michael Schumachercbna
We meandered through the park and chatted a bit about various things. Simon had brought along his external flash and wanted to play with off-camera lighting. So we convinced Liam to stand in front of a tree for us and Simon ended up taking one of my favorite images from the entire trip. This was Liam standing in front of the tree under the shade with me holding the flash slightly above him and to the camera right.
Liam by Simon
We even managed to run into Barrie Minney while on our way back to the Commons building. Aryeom and I started talking a little bit while walking when we crossed paths with some locals hanging out in the park. One man in particular was quite outgoing and let Aryeom take his photo, leading to another fun image!
Upon returning to the Commons building we experimented with some of the pretty window light coming into the building along with some black panels and a model (Mairi). This was quite fun as we were experimenting with various setups for the black panels and speedlights. Everyone had a chance to try some shots out and to direct Mairi (who was super patient and accommodating while we played).
I was having so much fun talking and trying things out with everyone that I didn’t even take that many photos of my own! This is one of my only images of Mairi inside the Commons. Mairi Natural Lightcba
Towards the end of our day I decided get my big Softlighter out and to try a few things in the lane outside the Commons building. Luckily Michael Schumacher grabbed an image of us while we were testing some shots with Mairi outside.
A nice behind-the-scenes image from schumaml of the lighting setup used below.
Yes, that’s darktable developer hanatos bracing the umbrella from the wind for me! Photo by Michael Schumachercbna
I loved the lane receding in the background and thought it might make for some fun images of Mairi. I had two YN-560 flashes in the Softlighter both firing around ¾ power. I had to balance the ambient sky with the softlighter so needed the extra power of a second flash (it also helps to keep the cycle times down).
Mairi waiting patiently while we set things up. Mairi Finsburycba
50mm f/8.0 1⁄200 ISO200
Mairi Finsbury Park (In the Lane)cba
The day was awesome and I really enjoyed being able to just hang out with everyone and take some neat photos. The evening at the pub was pretty great also (I got to hang out with Barrie and his friend and have a couple of pints - thanks again Barrie!).
It never fails to amaze me how every year the LGM organizers manage to put together such a great meeting for everyone. The venue was great and the people were just fantastic at the University of Westminster.
View of the lobby and meeting rooms (on the second floor).
Andrea Ferrero (@Carmelo_DrRaw) presenting PhotoFlow in the auditorium!
The opening “State of the Libre Graphics“ presentation was done by our (the GIMP teams) very own João Bueno who did a fantastic job! João will also be the local organizer for the 2017 LGM in Rio.
Thanks to contributions from community members Kees Guequierre, Jonas Wagner, and Philipp Haegi I had some great images to use for the PIXLS.US community slides for the “State of the Libre Graphics“. If anyone is curious, here is what I submitted:
These slides can be found on our Github PIXLS.US Presentations page (along with all of our other presentations that relate to PIXLS.US and promoting the community).
I was given some time to talk about and present our community to everyone at the meeting. (See embedded slides below):
I started by looking at what my primary motivation was to begin the site and what the state of free software photography was like at that time (or not like). Mainly that the majority of resources online for photographers that were high quality (and focused on high-quality results) were usually aimed at proprietary software users. Worse still, in some cases these websites locked away their best tutorials and learning content behind paywalls and subscriptions. I finished by looking at what was done to build this site and forum as a community for everyone to learn and share with each other freely.
A nice change this year was the inclusion of an exhibition space to display works by LGM members and artists. We even got an opportunity to hang a couple of prints (for some reason they really wanted my quad-print of pippin). I was particularly happy that we were able to print and display the Green Tiger Beetle by community member Kees Guequierre:
Hanatos and houz inspecting the prints at the exhibition.
View of the Exhibition. Well attended!
pippin x5
In Leipzig I thought it would be nice to offer portraits/headshots of folks that attended the meeting. I think it’s a great opportunity to get a (hopefully) nice photograph that people can use in social media, avatars, websites, etc. Here’s a sample of portraits from LGM2014 of the GIMP team that sat for me:
In 2014 I was lucky that houz had brought along an umbrella and stand to use, so this time I figured it was only fair that I bring along some gear myself. I had the Softlighter setup on the last couple of days for anyone that was interested in sitting for us. I say us because Marek Kubica (@Leonidas) from the community was right there to shoot with me along with the very famous @Ofnuts (well - famous to me - I’ve lost count of the neat things I’ve picked up from his advice)! Marek took quite a few portraits and managed the subjects very well - he was conversational, engaged, and managed to get some great personality from them.
A couple of samples from the images that I got are here as well, and they are the local organizer Lara with students from the University! I simply can’t thank them enough for the efforts and generosity in making us feel so welcome.
I’m still working through the portraits I took, but I’ll have them uploaded to my Flickr soon to share with everyone!
One of the best parts of attendance is getting to spend some time with the rest of the GIMP crew. Here’s an action shot during the GIMP meeting over lunch with a neat, glitchy schumaml:
There’s even some darktable nerds thrown in there!
It was great to see everyone at the flat on our last evening there as well…
Everyone spending the evening together! Mitch is missing from his seat in this shot (back there by pippin).
Overall this was another incredible meeting bringing together great folks who are building and supporting Free Software and Libre Graphics. Just my kind of crowd!
I even got a chance to speak a bit with the wonderful Susan Spencer of the Valentina project and we roughed out some thoughts about getting together at some point. It turns out she lives just up the same state as me (Alabama)! This is simply too great to not take advantage of - Free Software Fashion + Photography?! That will have to be a fun story (and photos) for another day…
Keep watching the blog for some more images from the trip - up next are the portraits of everyone and some more shots of the venue and exhibition!
It’s that time of year again! The weather is turning mild, the days are smelling fresh, and a bunch of photography nerds are all going to get together in a new country to roam around and (possibly) annoy locals by taking a ton of photographs! It’s the Pre-Libre Graphics Meeting photowalk of 2016!
Come join us the day before LGM kicks off to have a stroll through a lovely park and get a chance to shoot some photos between making new friends and having a pint.
Thanks to the wonderful work by the local LGM organizing team, we are able to invite everyone out to the photowalk on Thursday, April 14th the day before LGM kicks off.
They were able to get us in touch with the kind folks at Furtherfield Gallery & Commons in Finsbury Park. They’ve graciously offered us the use of their facilities at the Furtherfield Commons as a base to start from. So we will meet at the Commons building at 10:00 on Thursday morning.
Pre-LGM Photowalk 10:00 (AM), Thursday, April 14th Furtherfield Commons Finsbury Gate - Finsbury Park Finsbury Park, London, N4 2NQ
An overview of the photowalk venue relative to the LGM venue at the University of Westminster, Harrow:
If you would like to join us but may not make it to the Commons by 10:00, email me and let me know. I’ll try my best to make arrangements to meet up so you can join us a little later. I can’t imagine we’d be very far away (likely somewhere relatively near by in the park).
We’ll plan on meandering through the park with frequent stops to shoot images that strike our fancy. I will personally be bringing along my off-camera lighting equipment and a model (Mairi) to pose for us during the day. In case anyone wanted to play/learn a little about that type of photography.
There is no set time for finishing up. I figured we would play it by ear through lunch and to possibly all finish up at a nice pub together. (Taking advantage of the golden hour light at the end of the day hopefully).
In the spirit of saying “Thank you!” and sharing, I have also offered the Furtherfield folks our services for headshots and architectural/environmental shots of the Commons and Gallery spaces. For sure I will be taking these images for them but if anyone else wanted to pitch in and try, help, or assist the effort would be very welcome!
Dot in the Leipzig Market from the 2014 Pre-LGM photowalk.
Speaking of which, if you plan on attending and would like to explore some particular aspect of photography please feel free to let me know. I’ll do my best to match folks up based on interest. I sincerely hope this will be a fun opportunity to learn some neat new things, make some new friends, and to maybe grab some great images at the same time!
If there are any questions, please don’t hesitate to reach out to me! `patdavid@gmail.com` patdavid on irc://irc.gimp.org/#gimp
For some reason I was checking my account on the forums earlier today and noticed that it was created in April, 2015. On further inspection it looks like my, and @darix, accounts were created on April 2nd 2015.
(Not to be confused with the main site because apparently it took me about 8 months to get a forum stood up…)
Which means that the forums have been around for just over a year now?!
We’re just over a year old and just under 500 users on the forum!
For fun, I looked for the oldest (public) post we had and it looks like it’s the “Welcome to PIXLS.US Discussion“ thread. In case anyone wanted to revisit a classic…
THANK YOU so much to everyone who has made this an awesome place to be and nerd out about photography and software and more! Since we started we migrated the official G’MIC forums here as well as our friends at RawTherapee!
We’ve been introduced to some awesome projects like PhotoFlow as well as Filmulator. And everyone has just been amazing, supportive, and fun to be around.
Community member Eric Mesa asked on the forums the other day if there might be some Free resources for photographers that want to build a lighting diagram of their work. These are the diagrams that show how a shot might be set up with the locations of lights, what types of modifiers might be used, and where the camera/photographer might be positioned with respect to the subject. These diagrams usually also include lighting power details and notes to help the production.
It turns out there wasn’t really anything openly available and permissively licensed. So we need to fix that…
These diagrams are particularly handy for planning a shoot conceptually or explaining what the lighting setup was to someone after the fact. For instance, here’s a look at the lighting setup for Sarah (Glance):
Sarah (Glance)
YN560 full power into a 60” Photek Softlighter, about 20” from subject.
She was actually a bit further from the rear wall…
There are a few different commercial or restrictive-licensed options for photographers to create a lighting diagram, but nothing truly Free.
So thanks to the prodding by Eric, I thought it was something we should work on as a community!
I already had a couple of simple, basic shapes created in Inkscape for another tutorial so I figured I could at least get those files published for everyone to use.
I don’t have much to start with but that shouldn’t be a problem! I already had a backdrop, person, camera, octabox (+grid), and a softbox (+grid):
Even better: join the organization and fork the repo to add your own additions and to help us flesh out the available diagram assets for all to use!
From the README.md on that repo, I compiled a list of things I thought might be helpful to create:
Cameras
DSLR
Mirrorless
MF
Strobes
Speedlight
Monoblock
Lighting Modifiers
Softbox (+ grid?)
Umbrella (+ grid?)
Octabox (+ grid?)
Brolly
Reflectors
Flags
Barn Doors / Gobo
Light stands? (C-Stands?)
Environmental
Chairs
Stools
Boxes
Backgrounds (+ stands)
Models
If you don’t want to create something from scratch, perhaps grabbing the files and tweaking the existing assets to make them better in some way?
Hopefully we can fill out the list fairly quickly (as it’s a fairly limited subset of required shapes). Even better would be if someone picked up the momentum to possibly create a nice lighting diagram application of some sort!
On the old RawTherapee forums they used to have a contest sharing a single raw file amongst the members to see how everyone would approach processing from the same starting point. They called it PlayRaw. This seemed to really bring out some great work from the community so I thought it might be fun to start doing something similar again here.
I took a (relatively) recent image of Mairi and decided to see how it would be received (I’d say fairly well given the responses). This was my result from the raw file that I called Mairi Troisième:
The only things I asked for was to see the results and possibly the processing steps through either an XMP or PP3 sidecar file (darktable and RawTherapee respectively).
Here’s a montage of the results from everyone:
I loved being able to see what everyone’s approaches looked like. It’s neat to get a feel for all the different visions out there among the users and there were some truly beautiful results!
If you haven’t given it a try yourself yet, head on over to the [PlayRaw] Mairi Troisieme thread to get the raw file and try it out yourself! Just don’t forget to show us your results in the topic.
I’ll be soliciting options for a new image to kick off another round of processing again soon.
Donations go to help cover to costs of various projects to come together and meet, photograph, discuss, and hack at things. Please consider donating as every little bit helps us immensely! If you can’t donate then please consider helping us to raise awareness of what we’re trying to do! Either link the Pledgie campaign to others or let them know we’re here to help and share!
Even better is if you’re in the vicinity of London this April 15–18! Come out and join us as well as many other awesome Free Software projects all focused on the graphics community! We (PIXLS) will be conducting photowalks and meet-ups the Thursday before LGM kicks off as well!
Oh, and I finally did convince Mairi to join us through the weekend to model for us as needed. She’s super awesome and worth raising a glass to/with! Even more reason to come out and join us!
Some of you may know I exclusively use Contax manual focus lenses on my Canon cameras. I have had one reliable adapter from the start, that just happened to be perfect in every way: perfectly parallel, and lets my lenses focus exactly to infinity, and none of my lenses hit the mirror on my 5D.
However, swapping adapters between cameras gets mighty tedious, so recently I have been trying a variety of different adapters for my cameras, several quality tiers ranging from the cheapest ($15) up to the most expensive ($70).
However, I wasn’t satisfied with any of them. In order to assure that the adapted lenses can focus to infinity even with manufacturing tolerances, they’re made thinner than necessary. This means that they focus past infinity, and with some lenses the mirror of my 5D would hit the back of the lens, needing me to wiggle it to free the mirror after taking a photo.
I measured my fancier Fotodiox Pro adapter, and found that not only was it too thin, but it was unevenly thick! The top was 8 thousandths of an inch thin, the bottom right was 2 thousandth of an inch thin, and the bottom left was exactly the right thickness.
I decided I could do something about it.
I bought some shim stock from McMaster Carr, plastic and 2 thousandths of an inch thick, figuring I might be able to fold it to build up thickness if necessary. (Spoiler: it does fold.) It comes as a giant sheet five by twenty inches, but you’ll only need the tiniest amount of it.
Then I went about removing the screws that hold the two sides together.
The screws are incredibly small.
Here you can see that there are only three points on the ring that actually control the thickness; I point to one with the scissors. I had to be careful when measuring the thickness to only measure it between the screws, and that was challenging because the EF mount diameter is larger than the C/Y mount diameter, and there was only the slightest overlap between the outside of the C/Y registration surface and the inside of the EF mount.
Next I just cut a narrow strip out of this piece of shim stock using scissors, and put slits in it so it could fold more easily.
The right hand shim is folded in the shape of a W, and the left hand shim is only one layer.
The thicker shim went on the top, and the thinner shim went on the bottom-right.
Put the ring back on, and then…
Reinstall the screws.
Test your lenses for infinity focus and, if applicable, mirror slap, and rejoice if they’re good!
If you don’t have a perfect adapter as a reference for the proper thickness, you can first adjust the adapter to be perfectly even thickness all the way around, and then you can add thickness uniformly until your lenses just barely focus to infinity. It might be time consuming, but it’s very rewarding being able to trust the infinity stop on your lenses.
This method isn’t only applicable to the two-part SLR->SLR Fotodiox adapters; it should also work for SLR or rangefinder to mirrorless adapters as well.
I’ve seen it written that you can’t be sure whether or not your adapters are even thickness all the way around, but with this technique, you can make sure that your adapters are perfect.
Carlo originally posted this as a thread on the forums but I thought it would be useful as a post. He has graciously allowed us to re-publish it here. –Pat
Mike Howard, the host and creator of the jpeg2RAW podcast reached out to me last week to see if I might be able to come on the show to talk about Free Software Photography and what we’ve been up to here.
One of the primary reasons for creating this site was to be able to raise awareness of the Free Software community to a wider audience.
So this is a great opportunity for us to expose ourselves!
The podcast airs live this Tuesday, February 23rd at 8PM Eastern (-0500). You can join us at the jpeg2RAW live podcast page!
Mike has the live feed available to watch on that page and also has a chat server set up so viewers can interact with us live during the broadcast.
If you are free on Tuesday night then come on by and join us! I’ll be happy to field any questions you want answered (and that Mike asks) and will do my best to not embarrass myself (or our community). If you would like to make sure I address something in particular (or just don’t forget something), I also have a thread on discuss where you can make sure I know it.
I’m also looking for community members to submit some photos to help highlight our work and what’s possible with Free Software. Feel free to link them in the same thread as above. I’ve already convinced andabata to point us to some of his great macro shots (like that awesome lede image) and I’ll be submitting a few of my own images as well. If you have some works that you’d like to share please let me know!
Mike has all of his prior podcasts archived on his Podcasts page. So if you miss the live show it looks like you’ll be able to catch up later at your convenience.
As mentioned previously we are heading to London for Libre Graphics Meeting 2016! We’ve got a flat rented for a great crew to be able to stay together and we’re on track for a PIXLS meet up before LGM!
Speaking of people, I’m looking forward to being able to spend some time with some great folks again this year! We’ve got Tobias, Johannes, and Pascal making it out (I’m not sure that Simon, top below, will be making it out) from darktable, DrSlony and qogniw from RawTherapee, Andrea Ferrero creator of PhotoFlow, even Ofnuts (how cool is that?) may make it out!
Pascal, Johannes, and Tobias (left to right, bottom row) will be there!
We’ve also already had a great response so far on our Pledgie campaign. The campaign is still running if you want to help out!
If anyone is thinking they’d like to make it out to join us, please let me know as soon as possible so we can plan for space!
My friend and model Mairi will also be making it out for the meeting. She’ll be on hand to help us practice lighting setups, model interactions, and will likely be shooting right along with the rest of us as well!
I’ll also be assembling slides for my presentation during LGM. I’ve got a 20 minute time slot to talk about the community we’ve been building here and the neat things our members have been up to (Filmulator, PhotoFlow, and more).
I’ve setup a Github Pixls organization so that we can begin to share various things. This came about after talking with @paperdigits on the post about the upcoming podcast at jpeg2RAW. We were talking about ways to share information and assets for creating/delivering presentations about Free Software photography.
At the moment there is only the single repository Presentations as we are figuring out structure. I’ve uploaded my slides and notes from the LGM2015 State of the Libre Graphics presentation announcing PIXLS. If you’re on Github and want to join us just let me know!
A first approach to creating and mapping HDR images
I have a mostly love/hate relationship with HDR images (well, tonemapping HDR more than the HDR themselves).
I think the problem is that it’s very easy to create really bad HDR images that the photographer thinks look really good.
I know because I’ve been there:
Don’t judge me, it was a weird time in my life…
The best term I’ve heard used to describe over-processed images created from an HDR is “clown vomit” (which would also be a great name for a band, by the way).
They are easily spotted with some tell-tale signs such as the halos at high-contrast edges, the unrealistically hyper-saturated colors that make your eyes bleed, and a general affront to good taste.
In fact, while I’m putting up embarrassing images that I’ve done in the past, here’s one that scores on all the points for a crappy image from an HDR:
Crap-tastic!
Of course, the allure here is that it provides first timers a glimpse into something new, and they feel the desire to crank every setting up to 11 with no regards to good taste or aesthetics.
If you take anything away from this post, let it be this: “Turn it DOWN“.
If it looks good to you, then it’s too much. ;)
HDR lightprobes are used in movie fx compositing to ensure that the lighting on CG models matches exactly the lighting for a live-action scene. By using an HDR lightprobe, you can match the lighting exactly to what is filmed.
I originally learned about, and used, HDR images when I would use them to illuminate a scene in Blender. In fact, I will still often use Paul Debevec’s Uffizi gallery lightprobe to light scene renders in Blender today.
For example, you may be able to record 10-12 stops of light information using a modern camera. Some old films could record 12-13 stops of light, while your eyes can approximately see up to 14 stops.
HDR images are intended to capture more than this number of stops. (Depending on your patience, significantly more in some cases).
I can go on a bit about the technical aspects of HDR imaging, but I won’t. It’s boring. Plus, I’m sure you can use Wikipedia, or Google yourselves. :)
In the end, just realize that an HDR image is simply one where there is a greater amount of light information being stored than is able to be captured by your camera sensor in one shot.
Taking an HDR image(s)
More light information than my camera can record in one shot? Then how do I take an HDR photo?
You don’t.
You take multiple photos of a scene, and combine them to create the final HDR image.
Before I get into the process of capturing these photos to create an HDR with, consider something:
When/Why to use HDR
An HDR image is most useful to you when the scene you want to capture has bright and dark areas that fall outside the range of a single exposure, and you feel that there is something important enough outside that range to include in your final image.
That last part is important, because sometimes it’s OK to have some of your photo be too dark for details (or too light). This is an aesthetic decision of course, but keep it in mind…
Here’s what happens. Say you have a pretty scene you would like to photograph. Maybe it’s the Lower Chapel of Sainte Chapelle:
You may setup to take the shot, but when you are setting your exposure you may run into a problem. To expose for the brighter parts of the image means that the shadows fall to black too quickly, crushing out the details there.
If you expose for the shadows, then the brighter parts of the image quickly clip beyond white.
The use case for an HDR is when you can’t find a happy medium between those two exposures.
A similar situation comes up when you want to shoot any ground details against a bright sky, but you want to keep the details in both. Have a look at this example:
In the first column, if you expose for the ground, the sky blows out.
In the second, you can drop the exposure to bring the sky in a bit, but the ground is getting too dark.
In the third, the sky is exposed nicely, but the ground has gone to mostly black.
If you wanted to keep the details in the sky and ground at the same time, you might use an HDR (you could technically also use exposure blending with just a couple of exposures and blend them by hand, but I digress) to arrive at the last column.
Shooting Images for an HDR
Many cameras have an auto-bracketing feature that will let you quickly shoot a number of photos while changing the exposure value (EV) of each. You can also do this by hand simply by changing one parameter of your exposure each time.
You can technically change any of ISO, shutter speed, or aperture to modify the exposure, but I’d recommend you change only the shutter speed (or EV value when in Aperture Priority modes).
The reason is that changing the shutter speed will not alter the depth-of-field (DoF) of your view or introduce any extra noise the way changing the aperture or ISO would.
When considering your scene, you will also want to try to stick to static scenes if possible.
The reason is that objects that move around (swaying trees, people, cars, fast moving clouds, etc.) could end up as ghosts or mis-alignments in your final image.
So as you’re starting out, choose your scene to help you achieve success.
Set up your camera someplace very steady (like a tripod), dial in your exposure and take a shot.
If you let your camera meter your scene for you then this is a good middle starting point.
For example, if you setup your camera and meter your scene, it might report a 1⁄160 second exposure. This is our starting point (0EV).
The base exposure, 1⁄160 s, 0EV
To capture the lower values, just cut your shutter speed in half ( 1⁄80 second, +1EV), and take a photo. Repeat if you’d like ( 1⁄40 second, +2EV).
To capture the upper values, just double your starting point shutter speed ( 1⁄320, -1EV) and take a photo. Repeat if you’d like again ( 1⁄640, -2EV).
1⁄320, -1EV (left), 1⁄640, -2EV (right)
This will give you 5 images covering a range of -2EV to +2EV:
Shutter Speed
Exposure Value
1⁄640
-2EV
1⁄320
-1EV
1⁄160
0EV
1⁄80
+1EV
1⁄40
+2EV
Your values don’t have to be exactly 1EV each time, LuminanceHDR is usually smart enough to figure out what’s going on from the EXIF data in your image - I chose full EV stops here to simplify the example.
So armed with your images, it’s time to turn them into an HDR image!
Creating an HDR Image
You kids have it too easy these days. We used to have to bring all the images into Hugin and align them before we could save an hdr/exr file. Nowadays you’ve got a phenomenal piece of Free/Open Source Software to handle this for you:
After installing it, open it up and hit “New HDR Image“:
This will open up the “HDR Creation Wizard” that will walk you through the steps of creating the HDR. The splash screen notes a couple of constraints.
On the next screen, you’ll be able to load up all of the images in your stack. Just hit the big green “+“ button in the middle, and choose all of your images:
LuminanceHDR will load up each of your files, and investigate them to try and determine the EV values for each one. It usually does a good job of this on its own, but if there a problem you can always manually specify what the actual EV value is for each image.
Also notice that because I only adjusted my shutter speed by half or double, that each of the relative EV values is neatly spaced 1EV apart. They don’t have to be, though. I could have just as easily done ½ EV or ⅓ EV steps as well.
If there is even the remotest question about how well your images will line up, I’d recommend that you check the box for “Autoalign images”, and let Hugin’s align_image_stack do it’s magic.
You really need all of your images to line up perfectly for the best results.
Hit “Next“, and if you are aligning the images be patient.
Hugin’s align_image_stack will find control points between the images and remap them so they are all aligned.
When it’s done you’ll be presented with some editing tools to tweak the final result before the HDR is created.
You are basically looking at a difference view between images in your stack at the moment. You can choose which two images to difference compare by choosing them in the list on the left. You can now shift an image horizontally/vertically if it’s needed, or even generate a ghosting mask (a mask to handle portions of an image where objects may have shifted between frames).
If you are careful, and there’s not much movement in your image stacks, then you can safely click through this screen. Hit the “Next“ button.
This is the final screen of the HDR Creation Wizard.
There are a few different ways to calculate the pixel values that make up an HDR image, and this is where you can choose which ones to use.
For the most part, people far smarter than I had a look at a bunch of creation methods, and created the predefined profiles.
Unless you know what you’re doing, I would stick with those.
Hit “Finish“, and you’re all done!
You’ll now be presented with your HDR image in LuminanceHDR, ready to be tonemapped so us mere mortals can actually make sense of the HDR values present in the image.
At this point, I would hit the “Save As…” button, and save your work.
Tonemapping the HDR
So now you’ve got an HDR image. Congratulations!
The problem is, you can’t really view it with your puny little monitor.
The reason is that the HDRi now contains more information than can be represented within the limited range of your monitor (and eyeballs, likely). So we need to find a way to represent all of that extra light-goodness so that we can actually view it on our monitors. This is where tonemapping comes in.
We basically have to take our HDRi and use a method for compressing all of that radiance data down into something we can view on our monitors/prints/eyeballs. We need to create a Low Dynamic Range (LDR) image from our HDR.
Yes - we just went through all the trouble of stacking together a bunch of LDR images to create the HDRi, and now we’re going back to LDR ? We are - but this time we are armed with way more radiance data than we had to begin with!
The question is, how do we represent all that extra data in an LDR? Well, there’s quite a few different ways. LuminanceHDR provides for 9 different tonemapping operators (TMO’s) to represent your HDRi as an LDR image:
Just a small reminder, there’s a ton of math involved in how to map these values to an LDR image.
I’m going to skip the math.
The references are out there if you want them.
I’ll try to give examples of each of the operators below, and a little comment here and there. If you want more information, you can always check out the list on the Open Source Photography wikidot page.
Before we get started, let’s have a look at the window we’ll be working in:
Tonemap is the section where you can choose which TMO you want to use, and will expose the various parameters you can change for each TMO. This is the section you will likely be spending most of your time, tweaking the settings for whichever TMO you decide to play with.
Process gives you two things you’ll want to adjust. The first is the size of the output that you want to create (Result Size). While you are trying things out and dialing in settings you’ll probably want to use a smaller size here (some operators will take a while to run against the full resolution image). The second is any pre-gamma you want to apply to the image. I’ll talk about this setting a bit later on.
Oh, and this section also has the “Tonemap” button to apply your settings and generate a preview. I’ll also usually keep the “Update current LDR” checked while I rough in parameters. When I’m fine-tuning I may uncheck this (it will create a new image every time you hit the “Tonemap” button).
Results are shown in this big center section of the window. The result will be whatever Result Size you set in the previous section.
Previews are automatically generated and shown in this column for each of the TMO. If you click on one, it will automatically apply that TMO to your image and display it (at a reduced resolution - I think the default is 400px, but you can change it if you want). It’s a nice way to quickly get a preview overview of what all the different TMOs are doing to your image.
Ok, with that out of the way, let’s dive into the TMOs and have a look at what we can do. I’m going to try to aim for a reasonably realistic output here that (hopefully) won’t make your eyeballs bleed. No promises, though.
Need an HDR to follow along?
I figured it might be more fun (easier?) to follow along if you had the same file I do.
So here it is, don’t say I never gave you anything (This hdr is licensed cc-by-sa-nc by me):
Download from Google Drive (41MB .hdr)
Another note - all of the operators can have their results tweaked by modification of the pre-gamma value ahead of time. This is applied the image before the TMO is applied, and will make a difference in the final output. Usually pushing the pre-gamma value down will increase contrast/brightness in the image, while increasing it will do the opposite. I find it better to start with pre-gamma set to 1 as I experiment, just remember that it is another factor that you use to modify your final result.
Mantiuk ‘06
I’m starting with this one because it’s the first in the list of TMOs. Let’s see what the defaults from this operator look like against our base HDRi:
Default Mantiuk ‘06 applied
By default Mantiuk ‘06 produces a muted color result that seems pleasing to my eye. Overall the image feels like it’s almost “dirty” or “gritty” with these results. The default settings produce a bit of extra local contrast boosting as well.
Let’s see what the parameters do to our image.
Contrast Factor
The default factor is 0.10.
Pushing this value down to as low as 0.01 produces just a slight increase in contrast across the image from the default. Not that much overall.
Pushing this value up, though, will tone down the contrast overall. I think this helps to add some moderation to the image, as hard contrasts can be jarring to the eyes sometimes. Here is the image with only the Contrast Factor pushed up to 0.40:
Mantiuk ‘06 - Contrast Factor increased to 0.40
(click to compare to defaults)
Saturation Factor
The default value is 0.80.
This factor just scales the saturation in the image, and behaves as expected. If you find the colors a bit muted using this TMO, you can bump this value a bit (don’t get crazy). For example, here is the Saturation Factor bumped to 1.10:
Mantiuk ‘06 - Saturation Factor increased to 1.10
(click to compare to defaults)
Of course, you can also go the other way if you want to mute the colors a bit more:
Mantiuk ‘06 - Saturation Factor decreased to 0.40
(click to compare to defaults)
Detail Factor
The default is 1.0.
The Detail Factor appears to control local contrast intensity. It gets overpowering very quickly, so make small movements here (if at all). Here is what pushing the Detail Factor up to 10.0 produces:
Don’t do this. Mantiuk ‘06 - Detail Factor increased to 10.0
(click to compare to defaults)
Contrast Equalization
This is supposed to equalize the contrast if there are heavy swings of light/dark across the image on a global scale, but in my example did little to the image (other than a strange lightening in the upper left corner).
My Final Version
I played a bit starting from the defaults. First I wanted to push down the contrast a bit to make everything just a bit more realistic, so I pushed Contrast Factor up to 0.30. I slightly bumped the Saturation Factor to 0.95 as well.
I liked the textures of the tree and house, so I wanted to bring those back up a bit after decreasing the Contrast Factor, so I pushed the Detail Factor up to 5.0.
Here is what I ended up with in the end:
My final output (Contrast 0.3, Saturation 0.95, Detail 5.0)
(click to compare to defaults)
Mantiuk ‘08
Mantiuk ‘08 is a global contrast TMO (for comparison, Mantiuk ‘06 uses local contrast heavily). Being a global operator, it’s very quick to apply.
Default Mantiuk ‘08 applied
As you can see, the effect of this TMO is to compress the dynamic range into an LDR output using a function that operates across the entire image globally. This will produce a more realistic result I think, overall.
The default output is not bad at all, where brights seem appropriately bright, and darks are dark while still retaining details. It does feel like the resulting output is a little over-sharp to my eye, however.
There are only a couple of parameters for this TMO (unless you specifically override the Luminance Level with the checkbox, Mantiuk ‘08 will automatically adjust it for you):
Predefined Display
There are options for LCD Office, LCD, LCD Bright, and CRT but they didn’t seem to make any difference in my final output at all.
Color Saturation
The default is 1.0.
Color Saturation operates exactly how you’d expect. Dropping this value decreases the saturation, and vice versa. Here’s a version with the Color Saturation bumped to 1.50:
Mantiuk ‘08 - Color Saturation increased to 1.50
(click to compare to defaults)
Contrast Enhancement
The default value is 1.0.
This will affect the global contrast across the image. The default seemed to have a bit too much contrast, so it’s worth it to dial this value in. For instance, here is the Contrast Enhancement dialed down to 0.51:
Mantiuk ‘08 - Contrast Enhancement decreased to 0.51
(click to compare to defaults)
Compared to the default settings I feel like this operator can work better if the contrast is turned down just a bit to make it all a little less harsh.
Enable Luminance Level
This checkbox/slider allows you to manually specify the Luminance Level in the image. The problem that I ran into was that with this enabled, I couldn’t adjust the Luminance far enough to keep bright areas in the image from blowing out. if I let the default behavior of automatically adjusting Luminanace, then it kept things more under control.
My Final Version
Starting from the defaults, I pushed down the Contrast Enhancement to 0.61 to even out the overall contrast. I bumped the Color Saturation to 1.10 to bring out the colors a bit more as well.
I also dropped the pre-gamma correction to 0.91 in order to bring back some of the contrast lost from the Contrast Enhancement.
My final Mantiuk ‘08 output
(pre-gamma 0.91, Contrast Enhancement 0.61, Color Saturation 1.10)
(click to compare to defaults)
Fattal
Crap. Time for this TMO I guess…
THIS is the TMO responsible for some of the greatest sins of HDR images.
Did you see the first two images in this post? Those were Fattal.
The problem is that it’s really easy to get stupid with this TMO.
Fattal (like the other local contrast operators) is dependent on the final output size of the image.
When testing this operator, do it at the full resolution you will want to export.
The results will not match up if you change size.
I’m also going to focus on using only the newer v.2.3.0 version, not the old one.
Here is what the default values look like on our image:
Default Fattal applied
The defaults are pretty contrasty, and the color seems saturated quite a bit as well. Maybe we can get something useful out of this operator. Let’s have a look at the parameters.
Alpha
The default is 1.00.
This parameter is supposed to be a threshold against which to apply the effect. According to the wikidot, decreasing this value should increase the level of details in the output and vice versa. Here is an example with the Alpha turned down to 0.25:
Fattal - Alpha decreased to 0.25
(click to compare to defaults)
Increasing the Alpha value seems to darken the image a bit as well.
Beta
The default value is 0.90.
This parameter is supposed to control the amount of the algorithm applied on the image. A value of 1 is no effect on the image (straight gamma=1 mapping). Lower values will increase the amount of the effect. Recommended values are between 0.8 and 0.9. As the values get lower, the image gets more cartoonish looking.
Here is an example with Beta dropped down to 0.75:
Fattal - Beta decreased to 0.75
(click to compare to defaults)
Color Saturation
The default value is 1.0.
This parameter does exactly what’s described. Nothing interesting to see here.
Noise Reduction
The default value is 0.
This should suppress fine detail noise from being picked up by the algorithm for enhancement. I’ve noticed that it will slightly affect the image brightness as well. Fine details may be lost if this value is too high. Here the Noise Reduction has been turned up to 0.15:
Fattal - Noise Reduction increased to 0.15
(click to compare to defaults)
My Final Version
This TMO is sensitive to changes in its parameters. Small changes can swing the results far, so proceed lightly.
I increased the Noise Reduction a little bit up front, which lightened up the image. Then I dropped the Beta value to let the algorithm work to brighten up the image even further. To offset the increase, I pushed Alpha up a bit to keep the local contrasts from getting too harsh. A few minutes of adjustments yielded this:
My Fattal output - Alpha 1.07, Beta 0.86, Saturation 0.7, Noise red. 0.02
(click to compare to defaults)
Overall, Fattal can be easily abused. Don’t abuse the Fattal TMO. If you find your values sliding too far outside of the norm, step away from your computer, get a coffee, take a walk, then come back and see if it still hurts your eyes.
Drago
Drago is another of the global TMOs. It also has just one control: bias.
Here is what the default values produce:
Default Drago applied
The default values produced a very washed out appearance to the image. The black points are heavily lifted, resulting in a muddy gray in dark areas.
Bias is the only parameter for this operator. The default value is 0.85. Decreasing this value will lighten the image significantly, while increasing it will darken it. For my image, even pushing the Bias value all the way up to 1.0 only produced marginal results:
Drago - Bias 1.0
(click to compare to defaults)
Even at this level the image still appears very washed out. The only other parameter to change would be the pre-gamma before the TMO can operate. After adjusting values for a bit, I settled on a pre-gamma of 0.67 in addition to the Bias being set to 1:
My Final Version
My result: Drago - Bias 1.0, pre-gamma 0.67
(click to compare to defaults)
Durand
Most of the older documentation/posts that I can find describe Durand as the most realistic of the TMOs, yielding good results that do not appear overly processed.
Indeed the default settings immediately look reasonably natural, though it does exhibit a bit of blowing out in very bright areas - which I imagine can be fixed by adjustment of the correct parameters. Here is the default Durand output:
Default Durand applied
There are three parameters that can be adjusted for this TMO, let’s have a look:
Base Contrast
The default is 5.00.
This value is considered a little high from most sources I’ve read. Usually recommending to drop this value to the 3-4 range. Here is the image with the Base Contrast dropped to 3.0:
Durand - Base Contrast decreased to 3.5
(click to compare to defaults)
The Base Contrast does appear to drop the contrast in the image, but it also drops the blown-out high values on the house to more reasonable levels.
Spatial Kernel Sigma
The default value is 2.00.
This parameter seems to produce a change to contrast in the image. Large value swings are required to notice some changes, depending on the other parameter values. Pushing the value up to 65.00 looks like this:
Durand - Spatial Kernel Sigma increased to 65.00
(click to compare to defaults)
Range Kernel Sigma
The default value is 2.00.
My limited testing shows that this parameters doesn’t quite operate correctly. Changes will not modify the output image until you reach a certain threshold in the upper bounds, where it will overexpose the image. I am assuming there is a bug in the implementation, but will have to test further before filing a bug report.
My Final Version
In experiment I found that pre-gamma adjustments can affect the saturation in the output image. Pushing pre-gamma down a bit will increase the saturation.
My Durand results - pre-gamma 0.88, Contrast 3.6, Spatial Sigma 5.00
(click to compare to defaults)
I pulled the Base Contrast back to keep the sides of the house from blowing out. Once I had done that, I also dropped the pre-gamma to 0.88 to bump the saturation slightly in the colors. A slight boost to Spatial Kernel Sigma let me increase local contrasts slightly as well.
Finally, I used the Adjust Levels dialog to modify the levels slightly by raising the black point a small amount (hey - I’m the one writing about all these #@$%ing operators, I deserve a chance to cheat a little).
Reinhard ‘02
This is supposed to be another very natural looking operator. The initial default result looks good with medium-low contrast and nothing blowing out immediately:
Default Reinhard ‘02 applied
Even though many parameters are listed, they don’t really appear to make a difference. At least with my test HDR. Even worse, attempting to use the “Use Scales” option usually just crashes my LuminanceHDR.
Key Value
The default is 0.18.
This appears to be the only operator that does anything in my image at the moment. Increasing it will increase the brightness of the image, and decreasing it will darken the image.
Here is the image with Key Value turned down to 0.05:
Reinhard ‘02 - Key Value 0.05
(click to compare to defaults)
Phi
The default is 1.00.
This parameter does not appear to have any affect on my image.
Use Scales
Turning this option on currently crashes my session in LuminanceHDR.
My Final Version
I started by setting the Key Value very low (0.01), and adjusted it up slowly until I got the highlights about where I wanted them. Due to this being the only parameter that modified the image, I then started adjusting pre-gamma up until I got to roughly the exposure I thought looked best (1.09).
Final Reinhard ‘02 version - Key Value 0.09, pre-gamma 1.09
(click to compare to defaults)
Reinhard ‘05
Reinhard ‘05 is supposed to be another more ‘natural’ looking TMO, and also operates globally on the image. The default settings produce an image that looks under-exposed and very saturated:
Default Reinhard ‘05 applied
There are three parameters for this TMO that can be adjusted.
Brightness
The default value is -10.00.
Interestingly, pushing this parameter down (all the way to its lowest setting, -20) did not darken my image at all. Pulling it up, however, did increase the brightness overall. Here the brightness is increased to -2.00:
Reinhard ‘05 - Brightness increased to -2.00
(click to compare to defaults)
Chromatic Adaptation
The default is 0.00.
This parameter appears to affect the saturation in the image. Increasing it desaturates the results, which is fine given that the default value of 0.00 shows a fairly saturated image to begin with. Here is the Chromatic Adaptation turned up to 0.60:
Reinhard ‘05 - Chromatic Adaptation increased to 0.6
(click to compare to defaults)
Light Adaptation
The default is 1.00.
This parameter modifies the global contrast in the final output. It starts at the maximum of 1.00, and decreasing this value will increase the contrast in the image. Pushing the value down to 0.5 does this to the test image:
Reinhard ‘05 - Light Adaptation decreased to 0.50
(click to compare to defaults)
My Final Version
My Reinhard ‘05 - Brightness -5.00, Chromatic Adapt. 0.60, Light Adapt. 0.75
(click to compare to defaults)
Starting from the defaults, I raised the Brightness to -5.00 to lift the darker areas of the image, while keeping an eye on the highlights to keep them from blowing out. I then decreased the Light Adaptation until the scene had a reasonable amount of contrast without becoming overpowering to 0.75. At that point I turned up the Chromatic Adaptation to reduce the saturation in the image to be more realistic, and finished at 0.60.
Ashikhmin
This TMO has little in the way of controls - just options for two different equations that can be used, and a slider. The default (Eqn. 2) image is very dark and heavily saturated:
Default Ashikhmin applied
There is a checkbox option for using a “Simple” method (that produces identical results regardless of which Eqn is checked - I’m thinking it doesn’t use that information).
Simple
Checking the Simple checkbox removes any control over the image parameters, and yields this image:
Ashikhmin - Simple
(click to compare to defaults)
Fairly saturated, but exposed reasonably well. It lacks some contrast, but the tones are all there. This result could use some further massaging to knock down the saturation and to bump the contrast slightly (or adjust pre-gamma).
Equation 4
This is the result of choosing Equation 4 instead:
Ashikhmin - Equation 4
(click to compare to defaults)
There is a large loss of local contrast details in the scene, and some of the edges appear very soft. Overall the exposure remains very similar.
Local Contrast Threshold
The default value is 0.50.
This parameter modifies the local contrast being applied to the image. The result will be different depending on which Equation is being used.
Here is Equation 2 with the Local Contrast Threshold reduced to 0.20:
Ashikhmin - Eqn 2, Local Contrast Threshold 0.20
(click to compare to defaults)
Lower values will decrease the amount of local contrast in the final output.
Equation 4 with Local Contrast Threshold reduced to 0.20:
Ashikhmin - Eqn 4, Local Contrast Threshold 0.20
(click to compare to defaults)
My Final Version
After playing with the options, the overall best version I feel is had by just using the Simple option. Further tweaking may be necessary to get usable results beyond this.
Pattanaik
This TMO appears to attempt to mimic the behavior of human eyes with the inclusion of terminology like “Rod” and “Cone”. There are quite a few different parameters to adjust if wanted. The default TMO results in an image like this:
Default Pattanaik applied
The default results are very desaturated, and tends to blow out in the highlights. The dark areas appear well exposed, with the problems (in my test hdr) being mostly constrained to highlights for this example. On first glance, the results look like something that could be worked with.
There are quite a few different parameters for this TMO. Let’s have a look at them:
Multiplier
The default value is 1.00.
This parameter appears to modify the overall contrast in the image. Decreasing the value will decrease contrast, and vice versa. It also appears to slightly modify the brightness in the image as well (pushing the highlights to a less blown-out value). Here is the Multiplier decreased to 0.03:
Pattanaik - Multiplier 0.03
(click to compare to defaults)
Local Tone Mapping
This parameter is just a checkbox, with no controls. The result is a washed out image with heavy local contrast adjustments:
Pattanaik - Local Tone Mapping
(click to compare to defaults)
Cone/Rod Levels
The default is to have Auto Cone/Rod checked, greying out the options to change the parameters manually.
Turning off Auto Cone/Rod will get the default manual values of 0.50 for both applied:
Pattanaik - Manual Cone/Rod (0.50 for each)
(click to compare to defaults)
The image gets very blown out everywhere, and modification of the Cone/Rod values does not significantly reduce brightness across the image.
My Final Version
Starting with the defaults, I reduced the Multiplier to bring the highlights under control. This reduced contrast and saturation in the image.
My final Pattanaik - Multiplier 0.03, pre-gamma 0.91
(click to compare to defaults)
To bring back contrast and some saturation, I decreased the pre-gamma to 0.91. The results are not too far off of the defualt settings. The results could still use some further help with global contrast and saturation, and might benefit from layering or modifications in GIMP.
Closing Thoughts
Looking through all of the results shows just how different each TMO will operate across the same image. Here are all of the final results in a single image:
I personally like the results from Mantiuk ‘06. The problem is that it’s still a little more extreme than I would care for in a final result. For a really good, realistic result that I think can be massaged into a great image, I would go to Mantiuk ‘08 or Reinhard.
I could also do something with Fattal, but would have to tone a few things down a bit.
While you’re working, remember to occasionally open up the Levels Adjustment to keep an eye on the histogram. Look for highlights blowing out, and shadows becoming too murky. All the normal rules of image processing still apply here - so use them!
You’re trying to use HDR as a tool for you to capture more information, but remember to still keep it looking realistic. If you’re new to HDR processing, then I can’t recommend enough to stop occasionally, get away from the monitor, and come back to look at your progress.
If it hurts your eyes, dial it all back. Heck, if you think it looks good, still dial it back .
If I can head off even one clown-vomit image, then I’ll consider my mission accomplished with this post.
A Couple of Further Resources
Here’s a few things I’ve found scattered around the internet if you want to read more.
I don’t ever do this normally, but you’ve got to start somewhere, right?
It’s my long-term desire to be able to hold a PIXLS meetup/event every year where the community can get together.
Where we can hold workshops, photowalks, and generally share knowledge and information.
For free, for anyone.
For now though, we need support.
LGM is a great opportunity for us to meet with many different projects usually having representatives there.
Donations will help us to offset travel costs to attend LGM as well as a pre-LGM meetup we are holding (more below).
Anything further will go to creating new content and to cover hosting costs for the site.
Here’s the fancy little widget they make available:
If you want to help by adding this button places, here’s the code to do it:
<a href='https://pledgie.com/campaigns/30905'>
<img alt='Click here to lend your support to: PIXLS.US at Libre Graphics Meeting 2016 and make a donation at pledgie.com !' src='https://pledgie.com/campaigns/30905.png?skin_name=chrome' border='0' style='width: initial;'>
</a>
Feel free to use it wherever you think it might help. :)
I realize that not everyone will be able to donate funds. No sweat!
If you’d still like to help out then perhaps you can help us raise awareness for the campaign?
The more folks that know about it the better!
Re-tweeting, blogging, linking, yelling on a street corner all help to raise awareness of what we are doing here.
Heck, just invite folks to come read and participate in the community. Let’s help even more people learn about free software!
I am going to arrive a day early so that we can have a gathering of PIXLS community folks and anyone else who wants to join us for some photographic fun!
Thanks to the local organizers in London (yay Lara!), we have facilities for us to use.
We will be meeting on Thursday, April 14th at the Furtherfield Commons.
The facilities will be available from 1000 – 1800 for us to use.
Furtherfield Commons
Finsbury Gate – Finsbury Park
Finsbury Park, London, N4 2NQ
As near as I can tell, here’s a street view of the Finsbury Gate:
I believe the Commons building is just inside this gate, and on the left.
In 2014 I held a photowalk with LGM attendees in Leipzig the day before the event that was great fun.
Let’s expand the idea and do even more!
Nikolaikirche, Leipzig, from the 2014 LGM photowalk.
(That’s houz in the bottom right)
This year I plan on bringing a model along to shoot while we are out and about (my friend Mairi if she’s available - or a local model if not).
I will also be doing a photowalk again, either in the morning or afternoon.
I am also looking for folks from the community to suggest holding their own photoshoots or workshops, so please step forward and let me know if you’d be interested in doing something!
The facilities have bench seating for approximately 20 people, a big desk, and a projector as well.
Three things that I personally will be doing are (in no particular order):
Natural + flash portraits and model shooting workshop.
Photowalk around the park + surrounding environs.
Portraits + architectural photos for Furtherfield (the hosts).
I am hoping to possibly record some of these workshops and interactions for posterity and others that might not be able to make it to London.
It might be fun to record some shoots for the community to be able to use!
I am also 100% open to suggestions for content that you, the community, might be interested in seeing.
If you have something you’d like me to try (and record), please let me know!
Hopefully Mairi will be able to make it to London to model for us!
Sneaking a release out on Christmas Eve, the darktable team have announced their feature release of darktable 2.0!
After quite a few months of Release Candidates the 2.0 is finally here.
Please join me in saying Congratulations and a hearty Thank You! for all of their work bringing this release to us.
Alex Prokoudine of Libre Graphics World has a more in-depth look at the release including a nice interview with part of the team: Johannes Hanika, Tobias Ellinghaus, Roman Lebedev, and Jeremy Rosen. My favorite tidbit from the interview:
There is a lot less planning involved than many might think.
I finally got off my butt to get a process in place to obtain and update security certificates using Let’s Encrypt for both pixls.us and discuss.pixls.us.
I also did some (more) work with Victor Grigas and Wikipedia to support their #Edit2015 video this year.
So it was an honor to hear from Victor Grigas again this year!
This time around there was a neat new crop of images he wanted to animate for the video.
Below you’ll find my contributions (they were all used in the final edit, just shortened to fit appropriately):
Here is the final cut of the video, just released today:
Victor chose some really neat images that were fun to work on!
Of course, all free software was used in this creation (GIMP for cutting up the images into sections and rebuilding textures as needed and Blender for re-assembling the planes and animating the camera movements).
I had previously written a tutorial on doing this with free software on my blog.
Free: Anyone who owns a domain name can use Let’s Encrypt to obtain a trusted certificate at zero cost.
Automatic: Software running on a web server can interact with Let’s Encrypt to painlessly obtain a certificate, securely configure it for use, and automatically take care of renewal.
Secure: Let’s Encrypt will serve as a platform for advancing TLS security best practices, both on the CA side and by helping site operators properly secure their servers.
Transparent: All certificates issued or revoked will be publicly recorded and available for anyone to inspect.
Open: The automatic issuance and renewal protocol will be published as an open standard that others can adopt.
Cooperative: Much like the underlying Internet protocols themselves, Let’s Encrypt is a joint effort to benefit the community, beyond the control of any one organization.
It was relatively painless to obtain the certs.
I only had to run their program to use ACME to verify my domain ownership through placing a file on my web root.
Once the certs were generated I only had to make some small changes for it to work automatically on https://discuss.pixls.us.
(And to automatically get picked up when I update the certs within 90 days).
I still had to manually copy/paste the certs into cpanel for https://pixls.us, though.
Not automated (or elegant) but it works and only takes an extra moment to do.
Linearized sRGB channel values and radiometrically correct editing
One goal for GIMP 2.10 is to make it easy for users to produce radiometrically correct editing results. “Radiometrically correct editing” reflects the way light and color combine out there in the real world, and so requires that the relevant editing operations be done on linearized RGB.
Like many commonly used RGB working spaces, the sRGB color space is encoded using perceptually uniform RGB. Unfortunately colors simply don’t blend properly in perceptually uniform color spaces. So when you open an sRGB image using GIMP 2.9.2 and start to edit, in order to produce radiometrically correct results, many GIMP 2.9 editing operations will silently linearize the RGB channel information before the editing operation is actually done.
GIMP 2.9.2 editing operations that automatically linearize the RGB channel values include scaling the image, Gaussian blur, UnSharp Mask, Channel Mixer, Auto Stretch Contrast, decomposing to LAB and LCH, all of the LCH blend modes, and quite a few other editing operations.
The GIMP 2.9.2 editing operations that automatically linearize the RGB channel values do this regardless of whether you choose “Perceptual gamma (sRGB)” or “Linear light” precision. The only thing that changes when you switch between the “Perceptual gamma (sRGB)” and “Linear light” precisions is how colors blend when painting and when blending different layers together.
(Well, what the Gamma hack actually does changes when you switch between the “Perceptual gamma (sRGB)” and “Linear light” precisions, but the way it changes varies from one operation to the next, which is why I advise to not use the Gamma hack unless you know exactly what you are doing.)
Using the “Linear light” option in the “Image/Precision” menu
Large soft disks painted on a cyan background.
Top row: Painted using “Perceptual gamma (sRGB)” precision. Notice the darker colors surrounding the red and magenta disks, and the green surrounding the yellow disk: those are “gamma” artifacts.
Bottom row: Painted using “Linear Light” precision. This is how light waves blend to make colors out there in the real world.
Circles painted on a red background.
Top row: Painted using “Perceptual gamma (sRGB)” precision. The dark edges surrounding the paint strokes are “gamma” artifacts.
Bottom row: Painted using “Linear Light” precision. This is how light waves blend to make colors out there in the real world.
In GIMP 2.9.2, when using the Normal, Multiply, Divide, Addition, and Subtract painting and Layer blending:
For radiometrically correct Layer blending and painting, use the “Image/Precision” menu to select the “Linear light” precision option.
When “Perceptual gamma (sRGB)” is selected, layers and colors will blend and paint like they blend in GIMP 2.8, which is to say there will be “gamma” artifacts.
The LCH painting and Layer blend modes will always blend using Linear light precision, regardless of what you choose in the “Image/Precision” menu.
What about all the other Layer and painting blend modes? The concept of “radiometrically correct” doesn’t really apply to those other blend modes, so choosing between “Perceptual gamma (sRGB)” and “Linear light” depends entirely on what you, the artist or photographer, actually want to accomplish. Switching back and forth is time-consuming so I tend to stay at “Linear light” precision all the time, unless I really, really, really want a blend mode to operate on perceptually uniform RGB.
A note on interoperability between Krita and GIMP
Many digital artists and photographers are switching to linear gamma image editing. Let’s say you use Krita for digital painting in a true linear gamma sRGB profile, specifically the “sRGB-elle-V4-g10.icc” profile that is supplied with recent Krita installations, and you want to export your image from Krita and open it with GIMP 2.9.2.
Upon opening the image, GIMP will automatically detect that the image is in a linear gamma color space, and will offer you the option to keep the embedded profile or convert to the GIMP built-in sRGB profile. Either way, GIMP will automatically mark the image as using “Linear light” precision.
For interoperability between Krita and GIMP, when editing a linear gamma sRGB image that was exported to disk by Krita:
Upon importing the Krita-exported linear gamma sRGB image into GIMP, elect to keep the embedded “sRGB-elle-V4-g10.icc” profile.
Keep the precision at “Linear light”.
Then assign the GIMP built-in Linear RGB profile (“Image/Color management/Assign”). The GIMP built-in Linear RGB profile is functionally exactly the same as Krita’s supplied “sRGB-elle-V4-g10.icc” profile (as are the GIMP built-in sRGB profile and Krita’s “sRGB-elle-V4-srgbtrc.icc” profile).
Once you’ve assigned the GIMP built-in Linear RGB profile to the imported linear gamma sRGB Krita image, then feel free to change the precision back and forth between “Linear light” and “Perceptual gamma (sRGB)”, as suits your editing goal.
When you are finished editing the image that was imported from Krita to GIMP:
Convert the image to one of the “Perceptual gamma (sRGB) precisions (“Image/Precision”).
Convert the image to the Krita-supplied “sRGB-elle-V4-g10.icc” profile (“Image/Color management/Convert”).
Export the image to disk and import it into Krita.
If your Krita image is in a color space other than sRGB, I would suggest that you simply not try to edit non-sRGB images in GIMP 2.9.2 because many GIMP 2.9.2 editing operations do depend on hard-coded sRGB color space parameters.
GIMP 2.9.2’s unbounded floating point ICC profile conversions (handle with care!)
The sRGB (the gray blob) and ProPhotoRGB (the multicolored wire-frame) color spaces as seen from different viewing angles inside the CIELAB reference color space.(Images produced using ArgyllCMS and View3DScene).
Every time you convert saturated colors from larger gamut RGB working spaces to GIMP’s built-in sRGB working space using floating point precision, you run the risk of producing out of gamut RGB channel values. Rather than just explaining how this works, it’s better if you experiment and see for yourself:
Open “saturated-colors.png” with GIMP 2.9.2. GIMP will report the color space profile as “LargeRGB-elle-V4-g18.icc” — this profile is functionally equivalent to ProPhotoRGB.
Immediately change the precision to 32-bit floating point precision (“Image/Precision/32-bit floating point) and check the “Perceptual gamma (sRGB)” option.
Using the Color Picker Tool, make sure the Color Picker is set to “Use info Window” in the Tools dialog. Then eye-dropper the color squares, and make sure to set one of the columns in the Color Picker info Window to “Pixel”. The red square will eye-dropper as (1.000000, 0.000000, 0.000000). The cyan square will eyedropper as (0.000000, 1.000000, 1.000000), and so on. All the channel values will be either 1.000000 or 0.000000.
While still at 32-bit floating point precision, and still using the “Perceptual gamma (sRGB)” option, convert “saturated-colors.png” to GIMP’s built-in sRGB.
Eyedropper the color squares again. The red square will now eyedropper as approximately (1.363299, -2.956852, -0.110389), the cyan square will eyedropper as approximately (-13.365499, 1.094588, 1.003746), and so on.
For extra credit, change the precision from 32-bit floating point “Perceptual gamma (sRGB)” to 32-bit floating point “Linear light” and eye-dropper the colors again. I will leave it to you as an exercise to figure out why the eye-droppered RGB “Pixel” values change so radically when you switch back and forth between “Perceptual gamma (sRGB)” and “Linear light”.
Where did the funny RGB channel values come from? At floating point precision, GIMP uses LCMS2 to do unbounded ICC profile conversions. This allows an RGB image to be converted from the source to the destination color space without clipping otherwise out of gamut colors. So instead of clipping the RGB channels values to the boundaries of the very small sRGB color gamut, the sRGB color gamut was effectively “unbounded”.
When you do an unbounded ICC profile conversion from a larger color space to sRGB, all the otherwise out of gamut colors are encoded using at least one sRGB channel value that is less than zero. And you might get one or more channel values that are greater than 1.0. Figure 11 below gives you a visual idea of the difference between bounded and unbounded ICC profile conversions:
Unbounded (unclipped floating point) and bounded (clipped integer) conversions of a very colorful red flower from the original ProPhotoRGB color space to the much smaller sRGB color space.(Images produced using ArgyllCMS and View3DScene).
Top row: Unbounded (unclipped floating point) and bounded (clipped integer) conversions of a very colorful red flower from the original ProPhotoRGB color space to the much smaller sRGB color space. The unclipped flower is on the left and the clipped flower is on the right.
Middle and bottom rows: the unclipped and clipped flower colors in the sRGB color space. The unclipped colors are shown on the left and the clipped colors are shown on the right:
The gray blobs are the boundaries of the sRGB color gamut.
The middle row shows the view inside CIELAB looking straight down the LAB Lightness axis.
The bottom row shows the view inside CIELAB looking along the plane formed by the LAB A and B axes.
The unclipped sRGB colors shown on the left are all encoded using at least one sRGB channel value that is less than zero, that is, using a negative RGB channel value.
When converting saturated colors from larger color spaces to sRGB, not clipping would seem to be much better than clipping. Unfortunately a whole lot of RGB editing operations don’t work when performed on negative RGB channel values. In particular, multiplying such colors produces meaningless results, which of course applies not just to the Multiply and Divide blend modes (division and multiplications are inverse operations), but to all editing operations that involve multiplication by a color (other than gray, which is a special case).
So here’s one workaround you can use to clip the out of gamut channel values: Change the precision of “saturated-colors.png” from 32-bit floating point to 32-bit integer precision (“Image/Precision/32-bit integer”). This will clip the out of gamut channel values (integer precision always clips out of gamut RGB channel values). Depending on your monitor profile’s color gamut, you might or might not see the displayed colors change appearance; on a wide-gamut monitor, the change will be obvious.
When switching to integer precision, all colors are clipped to fit within the sRGB color gamut. Switching back to floating point precision won’t restore the clipped colors.
As an important aside (and contrary to a distressingly popular assumption), when doing a normal “bounded” conversion to sRGB, using “Perceptual intent” does not “keep all the colors”. The regular and linear gamma sRGB working color space profiles are matrix profiles, which don’t have perceptual intent tables. When you ask for perceptual intent and the destination profile is a matrix profile, what you get is relative colorimetric intent, which clips.
Using GIMP 2.9.2’s floating point precision for unclamped editing
High bit depth GIMP’s unclamped editing: a whole realm of new editing possibilities
I’ve warned you about the bad things that can happen when you try to multiply or divide colors that are encoded using negative sRGB channel values. However, out of gamut sRGB channel values can also be incredibly useful.
GIMP 2.9.2 does provide a number of “unclamped” editing operations from which the clipping code in the equivalent GIMP 2.8 operation has been removed. For example, at floating point precision, the Levels upper and lower sliders, Unsharp Mask, Channel Mixer and “Colors/Desaturate/Luminance” do not clip out of gamut RGB channel values (however, Curves does clip). Also the Normal, Lightness, Chroma, and Hue blend modes do not clip out of gamut channel values.
Unclamped editing operations might sound more arcane than interesting, but especially for photographers this is a really big deal:
Automatically clipped RGB data produces lost detail and causes hue and saturation shifts.
Unclamped editing operations allow you, the photographer, to choose when and how to bring the colors back into gamut.
Of interest to photographers and digital artists alike, unclamped editing sets the stage for (and already allows very rudimentary) HDR scene-referred image image editing.
Having used high bit depth GIMP for quite a while now, I can’t imagine going back to editing that is constrained to only using clipped RGB channel values. The Autumn colors tutorial provides a start-to-finish editing example making full use of unclamped editing and the LCH blend modes, with a downloadable XCF file so you can follow along.
If the thought of working with unclamped RGB data is unappealing, use integer precision
If working with unclamped RGB channel data is simply not something you want to do, then use integer precision for all your image editing. At integer precision all editing operations clip. This is a function of integer encoding and so happens regardless of whether the particular editing function includes or doesn’t include clipping code.
Looking to the future: GIMP 3.0 and beyond
Even though GIMP 2.10 hasn’t yet been released, high bit depth GIMP is already an amazing image editor. GIMP 3.0 and beyond will bring many more changes, including the port to GTK+3 (for GIMP 3.0), full color management for any well-behaved RGB working space (maybe by 3.2?), plus extended LCH processing with HSV strictly for use with legacy files. Also users will eventually have the ability to choose “Perceptual” encodings other than the sRGB TRC.
If you would like to see GIMP 3.0 and beyond arrive sooner rather than later, GIMP is coded, documented, and maintained by volunteers, and GIMP needs more developers. If you are not a programmer, there are many other ways you can contribute to GIMP development.

 Login