Normal view

Published — 8 July 2026 Simon Späti - Data Engineering & Second Brain

The Grammar of Data: Define Once, Run Anywhere with Cross-Engine Expressions

Grammars for languages or any other field are a beautiful thing. They compress complex systems into a language with a couple of rules. For the spoken language example, we know when to capitalize a letter or how to start a sentence. There are clear rules. Grammars also help us remember, as we do not need to recall every little rule, but apply them in a structured way.

For text editing, we have Vim motions that help us navigate a text document with 1000s of shortcuts, but because there is a grammar, we do not need to remember them all, but learn the structure of the grammar and combine them. But what if you work in data? What if we could have the same for data, a grammar for data engineering, or a language that defines it?

Expressing our needs declaratively and decisively? Also, expressing it in a way that leads to reproducible outcomes, or works with multiple parts and execution engines already out there. This is what we will discuss in this article. How existing tooling, such as Ibis, provides some capabilities, and how xorq extends them by adding full lineage and transparency for humans, with included executable memory for useful tabular data, all manifested in a single git repository.

Expressions for Data Engineering Workloads

Having a grammar for data engineering means we can express the workloads in a declarative manner, and then be sure we can deterministically reproduce and apply that exact definition.

It’s similar to the concept of a Declarative Data Stack I introduced a while back, but it gives the stack not only configurations but also a language with in-built manifestation and execution engines.

Write -> Manifest and Execute | Image from Composable expressions for data pipelines

In the above image, we see:

  1. How to express (write) our transformations and business logic. It’s the context of every ML or DE pipeline.
  2. We can build the expression into a manifest that has a unique hash, runs input validations, tracks lineage, creates a deterministic cache, and produces a human-readable expr.yaml you can diff and review in a PR.
  3. Lastly, we can execute it in any execution engine with the same manifest.

This is hugely powerful and separates the concerns of defining logic, verification in the manifest step, and execution as a composable data stack, as Wes McKinney called it, with multi-compute engine possibilities.

How the DE Language Works: Different Expression Types

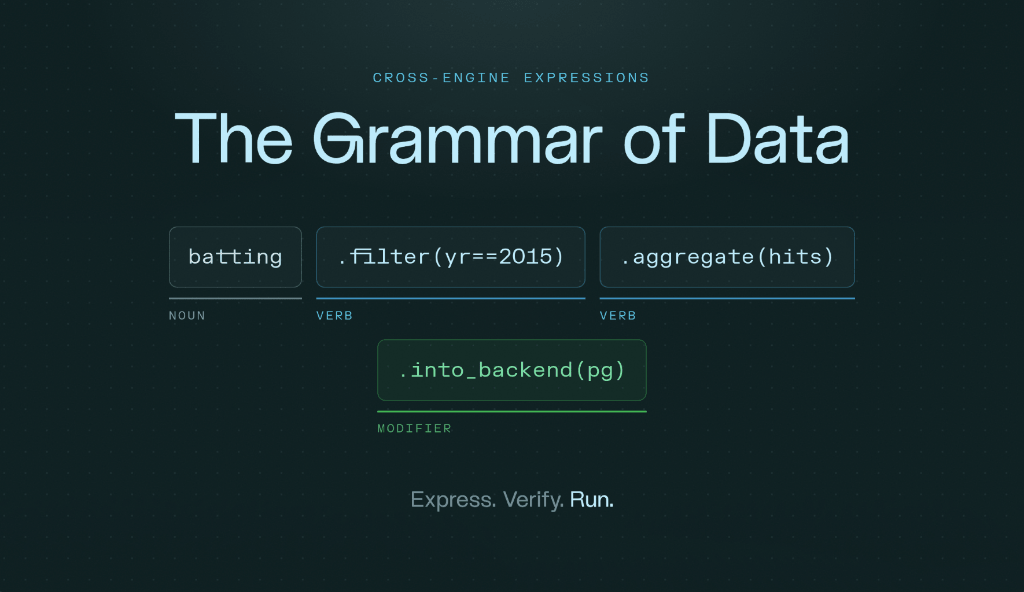
Every grammar starts with nouns, and here the noun is the source, a node that holds data but carries no transformation yet. It might be an in-memory table, a registered connection to a warehouse, or just a lazy pointer to a file on disk that hasn’t been read. They’re simply referenced, the way a noun refers to a thing before any verb acts on it.

The verbs in our language are transforms such as filter, select, mutate, aggregate, join, order, limit. Each one takes a source (or another transformed expression) and returns a new, immutable expression. You do not mutate anything before it, only describe what should happen next.

Looking at a definition such as .filter(...).aggregate(...).mutate(...), we can see this as a sentence. The moment a verb is applied, the expression stops being a plain noun and becomes a statement, a description of “data plus what should happen to it.” But the sentence isn’t spoken yet, it stays inert, fully composed but unexecuted, until something finally asks it to run. That’s the deferred part of the grammar: writing the sentence and saying it out loud are two different acts.

There’s a third part of speech worth naming: the template. Instead of writing a sentence about a specific noun, you can write one about a noun’s shape, a schema with no rows behind it. A template says “given something with a column of this type, here is what I’ll do to it,” and only later gets bound to an actual source, at which point the placeholder resolves and it becomes an ordinary statement again.

And we have modifiers that ride alongside a statement without changing what it computes. They’re small tags of metadata that say “this expression also represents a fitted model” or “this is a saved reference to something else.” It’s like a footnote with additional metadata that doesn’t change the surface meaning, but adds context for later use.

This analogy makes the grammar compose the same way regardless of which engine eventually executes it. There are more parts, but with just these four, noun, verb, template, modifier, you can read (and write) arbitrarily complex data pipelines the same way learning a handful of verb-and-object combinations in a text editor lets you compose arbitrarily complex edits.

[!tip] Avoids building “Inner-Platform Effect” with repeated tools
With this grammar, we can avoid repeatedly implementing the same logic we already have, but manifest and express our logic once, and reuse it with different execution engines, exactly what Ibis and xorq allow. Similar to what the inner-platform effect means for software best practices.

Why a Grammar is Really Good for LLMs

Having a grammar is really good for LLMs, too. It helps them first to declare data artifacts and second to execute them reproducibly.

On top, expressions can be LLM-agnostic, and we can interchange the LLMs we use just with an expression. Also, the chart is just an expression, or the data catalog and the metrics.

Model Once, Represent Everywhere: Expressing the Full Data Stack with a Single Expression

Like UDA (Unified Data Architecture) from Netflix, we define our expressions once and represent them everywhere. Netflix built UDA to solve duplicated models, inconsistent terminology, and siloed systems, where the same concept like ‘actor’ or ‘movie’ gets modeled differently across teams, with no shared foundation. Their answer was a full knowledge graph with a metamodel, making the conceptual model part of the actual control plane.

Not everyone needs Netflix-scale tooling, though. For a code-first approach, xorq gives you the same core principle: define once, execute anywhere by writing a declarative Ibis expression, serializing them as content-addressed YAML artifacts, and running against any supported engine, fully reproducible.

The difference worth noting: UDA is a semantic layer defining what data means across systems. Xorq is a computational layer defining what transformations do across engines. Both reject the same anti-pattern of re-implementing the same logic for every system.

Entering Xorq: The Horizontal Data Architecture

Xorq is an executable memory system for tabular data that works horizontally across your data stack, supporting everything from discovery with a catalog to defining transformation logic to modeling.

It has declarative transformation (Pandas style), and you can build ML pipelines and prepare data with its semantics in a single stack that is not vertically integrated, but horizontally integrated, giving your agents a catalog of executable pipelines and turning short-lived agent work such as wrangling scripts, sklearn pipelines, ad-hoc tables into durable, composable, executable artifacts that any future agent or human can discover, reproduce, and reuse.

Old vertical siloed way vs. the horizontal composable data stack way with multi-engine

The horizontal data stack shows what Xorq brings to the table. Xorq’s origins started from a git-native semantic layer, for data analysts out of college, to build semantic models for a living, to make their lives easier.

From point-and-click tools, dragging tables and drawing joins manually, only to add more reporting tools on top to create pixel-perfect reports. Also performance-wise, it didn’t scale, meaning we needed cubes to make it faster, adding another layer of complexity.

And there was no lineage that shows from source to dashboard. The question asked was: “what if we could do this end-to-end data engineering workflow locally?”. This is what the horizontal data stack and xorq are providing.

To add semantic layer capabilities, Julien Hurault and Hussain built the Boring Semantic Layer + the Xorq catalog, providing a semantic model you define in Python, check into git, and query from the CLI.

Compressing Logic into a Single Executable

Compression of a full data stack into a single executable is hard, but xorq tries exactly this with the help of Ibis, git, uv, and DataFusion.

The design choices of xorq showcase even better what it is, and what they enable:

  • Ibis as expression layer (v9.5.0+, partial): Declarative dataframe expressions compiled to multiple backends (xorq supports a subset of the Ibis API, not the full surface)
  • Git for state and storage: The catalog is a git repo of entries with git-annex support for large files
  • uv for reproducible environments: Each entry ships with a wheel and pinned requirements.txt.
  • DataFusion for embedded compute: Pipelines execute in-process with SQL and UDFs

Composable Data Engines

Another big advantage of expressions and having a grammar for data engineering is easily switching between backends, with no change to the transformation or business logic. It’s just defining the backend from Apache Arrow Flight to DuckDB or any other engine.

We write the definitions and express our tabular data and computations. The engine, in this case xorq, can build it into a manifest file that is deterministic and hashed.

Xorq uses Ibis as the expression layer for single-backend logic, then builds the cross-engine expression tree into a serialized YAML artifact. When moving data between backends, xorq transfers Apache Arrow RecordBatch streams between them—each backend acts as a RecordBatch transducer. No CSV serialization, no JSON encoding needed. This makes backend switching fast and memory-efficient. Write declarative Ibis expressions that run like a tool—xorq extends Ibis with caching, multi-engine execution, and UDFs.

Here’s an example of using DuckDB and Postgres in conjunction:

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
import xorq.api as xo

# Connect to engines
pg = xo.postgres.connect_env()
db = xo.duckdb.connect()

# Load data from different sources
batting = pg.table("batting")
awards = xo.examples.awards_players.fetch(backend=db)

# Filter in respective engines
recent = batting.filter(batting.yearID == 2015)
nl_awards = awards.filter(awards.lgID == "NL")

# Move data to postgres for join
result = recent.join(
    nl_awards.into_backend(pg),
    ["playerID"]
)

result.execute()

Move data between different engines within a single expression using into_backend(), here Postgres and DuckDB

You can see how easily you choose your most optimized execution engine, whether in the above example choosing DuckDB for filtering recent batting and using Postgres to filter NL (National League) awards, and joining the two with the Postgres engine.

Engines supported by xorq as of now, with the ability to move data between them, are (check Supported backends for the latest):

  • Embedded: DataFusion, DuckDB, SQLite, Pandas
  • Warehouses: Snowflake, Databricks, Trino, Postgres
  • Lakehouse: PyIceberg
  • Arrow Flight: GizmoSQL (DuckDB over Arrow Flight SQL)

Cross-Engine Expression Tree

With different engines supported, we can use the compressed single executable logic across engines. We can build expression graphs before executing them, which works like this, with one expression, many engines:

1
2
expr = penguins.into_backend(xo.sqlite.connect())
expr.ls.backends

The output of building a cross-engine expression is a directory containing your serialized pipeline with a unique hash identifying each build and its artifacts and expressions. When executed, the output is the resulting object or data.

And the expressions are tools, Arrow is the pipe. E.g., a Unix pipe streams text between small programs. Xorq pipes Arrow streams between expressions: unix : programs :: xorq : arrow-transforms

That executes like this:

1
2
In [6]: expr.to_pyarrow_batches()
Out[6]: <pyarrow.lib.RecordBatchReader at 0x15dc3f570>

This is quite short and potentially abstract to understand when never used, but we will go into more examples and details in another article.

A Shared Language for Data

This article introduces a new way of describing data transformations for machine learning or data engineering pipelines in a direct and simple way that works locally with any execution engine, without changing the code itself.

It’s a good place if you need a trusted harness for a data engineering persona. We can define once and use it with the engine that works best for your workload and data engineering environment.

We had a look at how we write -> manifest -> execute with xorq, its advantages, and why you might use it for modeling once and representing everywhere. By adding AI agents to the mix, which help us pull the right lever, instead of bigger, more expensive models or more tokens, we improve accuracy with more semantic understanding, with a grammar the model can learn and apply, even pre-manifest before execution, and run them deterministically every time. This is a huge addition to working just with agentic Skills files that are free-form Markdown and pull data all over, or are not defined precisely enough. It’s all about having high-quality context in the right format, with a clear definition where humans and AI agents can interchange and help each other.

There’s a lot more to come, with showcasing the horizontal data stack and the use cases it supports, how we build expressions versus running computations, and how data catalogs are integrated into the picture, too.

Check out xorq code and star it on GitHub, or read more behind the scenes at Xorq documentation.

They also have a macOS desktop app coming up that does it all in one unified app, geared towards non-technical users. Join the waitlist for that.


Full article published at xorq.dev - written as part of my services

Published — 7 July 2026 Simon Späti - Data Engineering & Second Brain

Where AI Agents Belong in Data Engineering: The Correctness Layer

With ever-changing models, new and better ones coming out every few months, it’s great if we don’t have to rely on them too heavily. The better your tooling, the less dependent you become on any single model. That’s also why the deterministic harness matters: a correctness layer that lets you reproduce outputs and trace lineage regardless of which model you’re running underneath. This is especially true during maintenance or extending the project, where verification is the real job.

The danger isn’t only a crash or an error message, but a wrong number that didn’t break. It might be a clean query, but it introduces duplicated rows.

In this article, we go through the three levels of AI agents in data engineering, how to structure projects so the AI delivers its best outcomes, and how dedicated agents with a deterministic core help us build higher-quality pipelines — ones we can actually trust. And we look at a practical example of how it works with a blast radius analysis.

The Three Levels of AI Agents in Data Engineering

Why should we use agents for data engineering? And at what levels can agents help us productively? As LLMs will always have some error tolerance, as humans do too, we need a way to be more confident in producing the code.

Chat-phase, Autonomous and Dedicated Tooling

There are different levels of confidence and levels on which the agents can help us.

  1. The initial chat-phase: the development where we prompt Claude or ChatGPT. The model tries to understand the context based on what it has access to. It takes a decent amount of tokens, as it needs to scan everything from scratch.
  2. The autonomous approach, where Claude Code or Codex also have access to the tools humans have, mostly the CLI on the terminal, making it possible to query Postgres with psql or read from S3 or Parquet with DuckDB to verify queries and data. A much higher quality outcome.
  3. Dedicated agents for the task at hand. E.g., for data, the tools know dbt or know how to transpile SQL code deterministically, meaning not from training data only, but with an actual tool that does it much faster and more reliably. Built-in checks and features a “general” agent can’t provide.
Showcasing the three levels of AI agents in data engineering

Ideally, we’d want to always use the dedicated tools, but there isn’t always one.

Where in the DE Lifecycle Each Level Actually Helps

BI Dashboards vs. Plumbing the Data Pipelines, or Creating Source Ingestions, or Maintaining? For data engineering, the question is not only if there is dedicated agent tooling, but also on what part of the data engineering lifecycle AI agents can help data engineers and analysts the most, and potentially even domain experts?

The lifecycle contains the ingestion part, ETL, or understanding the business in great detail, or is it just to visualize the result? Or should it cover maintenance in case of overnight ETL errors, or the full data lifecycle?

In general, before we go into more details later, agents can help us on the full cycle, but it always depends on who you are and what role you play. Building from scratch with no knowledge or seniority is dangerous. Why? Because they can’t verify if the produced code is correct. Okay for a side project or a proof of concept, but not for actual production.

What’s the Engineering Discipline for Working with AI?

There’s also a part that is less technical, a way of guiding the agents in the right direction. Especially if we want to safely use it in large projects or organizations, we can’t just let it run without guidance.

For that we need:

  1. clear project structure in which the agents can flourish. The more is given, the fewer tokens are used for this work, and it will be more aligned across the project. (Another reason a deterministic workflow such as uv init is best, because it will always be the same).
  2. build with clear instructions (agentic skills, superpowers, etc.) on how the tools are used (basically providing CLIs and API documentation). This is the bulk of the work anyway. That’s the data architecture, the brainstorming with fellow humans before you build something, instead of missing a key insight in the beginning and then letting the agent run down the wrong path. Also, be realistic: prompting “be correct” or “use state-of-the-art” won’t make it more correct or more state-of-the-art than the model was trained on. So if it’s a rather new architecture, it’s a must that you provide these links and hints.
  3. set up the project in a modular fashion, so the agents cannot break the whole project if they make a small change, so you don’t end up in a scenario like dependency hell with everything dependent on each other.
  4. use a declarative approach, with descriptive configuration that says the what and not the how, so that you can collaborate on these configs with the agents, version them, and easily revert or change something, as well as decouple the implementation logic from the actual business logic.

With these steps, you can get the best out of the agents of today. I’d say the model matters less, but the structure does, and as Mario says, so does the workflow approach. For example, extensively plan (the process before writing a single line) and correct the model before any implementation that could lead down the wrong path is written.

Also, don’t overthink it. But this is only the workflow and learning the soft skills and discipline of working with agents. How does that look in a real-world project?

[!note] The key is to get use out of AI, not to get more work.
E.g., most developers used to think about the problem. Today, most drown in PRs. When the AI tooling gets better, AI can provide more quality code that is correct, that needs less review or fewer iterations, which means fewer PRs and less work for the developers to go through.

The Correctness Layer for Data Engineers

A key insight is that AI agents should support the “human in the loop” for correctness, or a correctness layer. And rather than making more work to verify more code, we should be confident in the process and know that the code it produces is verified and ultimately correct.

But how do we get more “correct” work and a layer in which we can verify it? The biggest argument is a deterministic-validation architecture in full. E.g., Altimate Code splits the agent into a probabilistic layer on top and a deterministic Rust/TS layer underneath that does the actual SQL ops such as parsing, validating, and equivalence checks, so that the agent itself never has to be trusted on those questions.

An example of how Altimate Code is built with its probabilistic agent, deterministic harness, and deterministic core | Image from the article The Correctness Layer: Why Data Agents Need Determinism

Altimate Code, for example, is built on a probabilistic agent, deterministic harness, and deterministic core. The probabilistic agent with the LLM does the creative work of reading intent, picking a strategy, drafting SQL, summarizing results, and recovering when something goes wrong.

Below the boundary sits the deterministic harness, a TypeScript layer that intercepts every tool call: a dispatcher checks hasNativeHandler before the call runs, and routes it either to a native, deterministic handler or back to the model. Those handlers don’t reimplement logic themselves, they call into the deterministic core, a Rust engine (altimate-core) that exposes SQL operations as pure functions over ASTs and schemas, wired in via napi-rs bindings. Parsing, validating, transpiling, checking query equivalence, diffing schemas, extracting column lineage, diffing rows across warehouses — all of it runs sub-millisecond, and all of it returns the same answer on the same input, every time.

Like a compiler, the agent never decides whether two queries are equivalent or a column exists upstream. Instead, it calls a function that proves it against the parsed AST and the schema, the same way a type-checker proves a program compiles rather than guessing.

How the correctness layer adds additional verification

That’s the distinction that makes the output easier to review, as factual checks have been run and the output is either correct, or there’s a bug that it can fix directly. The rest a human can re-verify. On the dilemma of having stopped to hand-write code and approving it faster than humanly possible to check, you can also read more at You Are the Trust Layer.

[!note] There’s another factor, being wrong
Bare agent use might be cheap, but only until they’re wrong, and then the cost is unbounded.

Improvements for Better Usage of Tokens

Altimate, or data engineering agents that have deterministic functions and integrated understanding of how to work, can help you save tokens and be token lean (the opposite of [[tokenmaxxing]], which is popular on Twitter/X, using as many tokens as possible and having an agent running at all times). Because in large enterprises, token costs are a real budget point.

To slow down the tokens, an easy trick is to instruct the model to use fewer tokens and words itself - caveman is a good example of that, but you can also add a singular prompt to your CLAUDE.md, Codex, or model of choice in combination with Altimate Code.

An example of Altimate Code showing a trace of data lineage and a web UI for it.

There’s a second, less obvious cost: the token itself isn’t a stable unit. When Anthropic shipped Opus 4.7, the same prompt that cost X tokens on 4.6 started costing roughly 1.4X (same input, same answer, more tokens, same price per token).

Altimate on The Great Token Heist of ‘26 makes the case that “cost-per-token is the wrong number to optimize”, since the meter itself can move with a vendor’s next model update, and what we should track instead is cost-per-task. I fully agree, and this is where deterministic function calls work around that volatility by not using a model/tokens for every task, making it less expensive.

Typical Use Cases

In this chapter we go through typical AI agent use cases for data engineering.

There are many of them. You can use them to educate yourself or your team, build production data pipelines, build data apps, and visualize your data in new innovative ways (usually HTML web pages with React and other JavaScript frameworks). But in general, the use cases fit into these approaches:

  1. Start a new project from scratch example: Building a data landscape with more open source.
  2. Extending an existing project or data warehouse: Adding new data pipelines.
  3. Maintaining current setup: Update and verify it still works when changes come in.
  4. Migration: Migrate from one database or tooling to the next.
  5. Finding the Blind Spots: Two similar-sounding IDs might be wrongly used for a join, or missing data in a column that got missed in a nightly load, or anything in between. If agents can do these checks, that would be super beneficial. With more access to CLI, Model Context Layer, and deterministic tooling, these things are truly possible.

Below we go through extending and changing an existing warehouse with a change of column, and using Altimate Code to give us a Blast-radius assessment.

Showcases: Blast-Radius Example

A Blast-radius refers to the potential extent of damage. For example, before you knock down a wall in your house, you want to know if there’s plumbing behind it, electrical wiring within it, or if it’s holding up the floor above.

The same is true for a data warehouse or a data project with lots of ETL. For example, if a data engineer cleans up the table fct_orders by joining orders to order_items and summing order_total. It compiles, the dbt tests pass, nothing errors. But the join changes the grain, so any order with several line items now gets counted once per item, and revenue quietly inflates.

It’s best to know, before you rename a column or add a new join, the downstream (data that comes after the current task) dependencies to the dashboard — that’s what the blast-radius report does.

With Altimate Code we can achieve this. Before any change goes through, it maps out the full impact automatically and produces a detailed blast-radius report with what will break, what’s safe, what needs someone to sign off, and also performs the changes. Here is what this looks like:

Rename and Change Columns and Logic

As an example, in this prepared ecommerce repo with different DWH layers such as staging -> intermediate -> marts, I prompted this request to change unit from cent to dollars:

It recognized the dbt name and invoked dbt-analyze automatically:

It gave me a full Blast-radius report and the impact my changes would have on the project:

Including semantics only, to point out what’s safe and what’s not:

With a fixed order to address breaking changes, semantics and docs, and intentionally untouched:

Notice, I hadn’t said anything about blast analysis or using dbt-analyze — it did it on its own, ran dbt, and analyzed it deterministically.

This shows how Altimate Code looks behind the walls of data engineering, just like blast radius analysis.

If you want to see another example and a full blog post on Blast Radius, check out Blast Radius Analysis Using Altimate Code, and what Altimate Code did as in the video. Or Altimate provides many more examples and Showcase on their website such as Migrate SQL Server to Snowflake with dbt or showing how to resolve An Upstream Schema Changed.

[!example] Connect a model to Altimate
Make sure to connect to a model with /connect and choose an existing subscription with API credits, or any other subscription. I used opencode zen for my example, which includes e.g. Opus 4.8.

Correctness Over Confidence

I hope you got a better understanding of why AI agents can be genuinely useful, especially when provided with the right tools and applied with the right discipline.

You’ve also seen how deterministic tooling, purpose-built for data engineering and analytics problems, gets you both better correctness and better token economics than general-purpose agents alone.

Coming back to where we started: not every task needs a level-three agent. A quick chat-phase agent is fine for exploring a dataset or drafting a query you’ll review yourself. But the moment that output touches production or serious work, a dashboard, a nightly job, a number someone makes a decision on, you want the deterministic core underneath it, not just a model that sounds confident.

That’s the gap Altimate Code is built to close. It runs on deterministic functions purpose-built for DE workloads, it’s open-source via the OpenCode TUI, and for teams wanting more, there’s Altimate Studio — a paid, multi-agent platform with extras like warehouse cost optimization, dbt development acceleration, and migration tooling.


Check out Altimate Code, it’s free and open-source. Give them a star if you like them, and find more information on their docs and new website.


Full article published at Altimate.ai - written as part of my services

❌