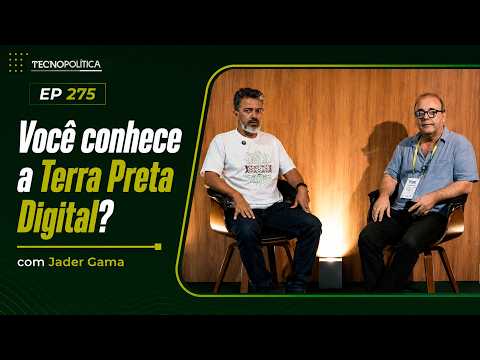
Neste episódio do Tecnopolítica, gravado durante o Fórum da Internet no Brasil (FIB 2026), em Belém do Pará, Sérgio Amadeu entrevista Jader Gama, pesquisador dedicado às relações entre tecnologias digitais, Amazônia, conhecimentos tradicionais e justiça socioambiental. Sua atuação reúne temas como soberania tecnológica, territórios digitais, cultura, inovação e os impactos da digitalização sobre as comunidades amazônicas.
Durante a conversa, eles discutem o conceito de Terra Preta Digital, suas inspirações nos saberes ancestrais da Amazônia, a construção de infraestruturas tecnológicas voltadas ao bem comum, a valorização dos conhecimentos tradicionais e os caminhos para pensar um desenvolvimento tecnológico comprometido com a diversidade cultural, a sustentabilidade e a autonomia dos povos.
With ever-changing models, new and better ones coming out every few months, it’s great if we don’t have to rely on them too heavily. The better your tooling, the less dependent you become on any single model. That’s also why the deterministic harness matters: a correctness layer that lets you reproduce outputs and trace lineage regardless of which model you’re running underneath. This is especially true during maintenance or extending the project, where verification is the real job.
The danger isn’t only a crash or an error message, but a wrong number that didn’t break. It might be a clean query, but it introduces duplicated rows.
In this article, we go through the three levels of AI agents in data engineering, how to structure projects so the AI delivers its best outcomes, and how dedicated agents with a deterministic core help us build higher-quality pipelines — ones we can actually trust. And we look at a practical example of how it works with a blast radius analysis.
The Three Levels of AI Agents in Data Engineering
Why should we use agents for data engineering? And at what levels can agents help us productively? As LLMs will always have some error tolerance, as humans do too, we need a way to be more confident in producing the code.
Chat-phase, Autonomous and Dedicated Tooling
There are different levels of confidence and levels on which the agents can help us.
The initial chat-phase: the development where we prompt Claude or ChatGPT. The model tries to understand the context based on what it has access to. It takes a decent amount of tokens, as it needs to scan everything from scratch.
The autonomous approach, where Claude Code or Codex also have access to the tools humans have, mostly the CLI on the terminal, making it possible to query Postgres with psql or read from S3 or Parquet with DuckDB to verify queries and data. A much higher quality outcome.
Dedicated agents for the task at hand. E.g., for data, the tools know dbt or know how to transpile SQL code deterministically, meaning not from training data only, but with an actual tool that does it much faster and more reliably. Built-in checks and features a “general” agent can’t provide.
Showcasing the three levels of AI agents in data engineering
Ideally, we’d want to always use the dedicated tools, but there isn’t always one.
Where in the DE Lifecycle Each Level Actually Helps
BI Dashboards vs. Plumbing the Data Pipelines, or Creating Source Ingestions, or Maintaining? For data engineering, the question is not only if there is dedicated agent tooling, but also on what part of the data engineering lifecycle AI agents can help data engineers and analysts the most, and potentially even domain experts?
The lifecycle contains the ingestion part, ETL, or understanding the business in great detail, or is it just to visualize the result? Or should it cover maintenance in case of overnight ETL errors, or the full data lifecycle?
In general, before we go into more details later, agents can help us on the full cycle, but it always depends on who you are and what role you play. Building from scratch with no knowledge or seniority is dangerous. Why? Because they can’t verify if the produced code is correct. Okay for a side project or a proof of concept, but not for actual production.
What’s the Engineering Discipline for Working with AI?
There’s also a part that is less technical, a way of guiding the agents in the right direction. Especially if we want to safely use it in large projects or organizations, we can’t just let it run without guidance.
For that we need:
clear project structure in which the agents can flourish. The more is given, the fewer tokens are used for this work, and it will be more aligned across the project. (Another reason a deterministic workflow such as uv init is best, because it will always be the same).
build with clear instructions (agentic skills, superpowers, etc.) on how the tools are used (basically providing CLIs and API documentation). This is the bulk of the work anyway. That’s the data architecture, the brainstorming with fellow humans before you build something, instead of missing a key insight in the beginning and then letting the agent run down the wrong path. Also, be realistic: prompting “be correct” or “use state-of-the-art” won’t make it more correct or more state-of-the-art than the model was trained on. So if it’s a rather new architecture, it’s a must that you provide these links and hints.
set up the project in a modular fashion, so the agents cannot break the whole project if they make a small change, so you don’t end up in a scenario like dependency hell with everything dependent on each other.
use a declarative approach, with descriptive configuration that says the what and not the how, so that you can collaborate on these configs with the agents, version them, and easily revert or change something, as well as decouple the implementation logic from the actual business logic.
With these steps, you can get the best out of the agents of today. I’d say the model matters less, but the structure does, and as Mario says, so does the workflow approach. For example, extensively plan (the process before writing a single line) and correct the model before any implementation that could lead down the wrong path is written.
Also, don’t overthink it. But this is only the workflow and learning the soft skills and discipline of working with agents. How does that look in a real-world project?
[!note] The key is to get use out of AI, not to get more work.
E.g., most developers used to think about the problem. Today, most drown in PRs. When the AI tooling gets better, AI can provide more quality code that is correct, that needs less review or fewer iterations, which means fewer PRs and less work for the developers to go through.
The Correctness Layer for Data Engineers
A key insight is that AI agents should support the “human in the loop” for correctness, or a correctness layer. And rather than making more work to verify more code, we should be confident in the process and know that the code it produces is verified and ultimately correct.
But how do we get more “correct” work and a layer in which we can verify it? The biggest argument is a deterministic-validation architecture in full. E.g., Altimate Code splits the agent into a probabilistic layer on top and a deterministic Rust/TS layer underneath that does the actual SQL ops such as parsing, validating, and equivalence checks, so that the agent itself never has to be trusted on those questions.
Altimate Code, for example, is built on a probabilistic agent, deterministic harness, and deterministic core. The probabilistic agent with the LLM does the creative work of reading intent, picking a strategy, drafting SQL, summarizing results, and recovering when something goes wrong.
Below the boundary sits the deterministic harness, a TypeScript layer that intercepts every tool call: a dispatcher checks hasNativeHandler before the call runs, and routes it either to a native, deterministic handler or back to the model. Those handlers don’t reimplement logic themselves, they call into the deterministic core, a Rust engine (altimate-core) that exposes SQL operations as pure functions over ASTs and schemas, wired in via napi-rs bindings. Parsing, validating, transpiling, checking query equivalence, diffing schemas, extracting column lineage, diffing rows across warehouses — all of it runs sub-millisecond, and all of it returns the same answer on the same input, every time.
Like a compiler, the agent never decides whether two queries are equivalent or a column exists upstream. Instead, it calls a function that proves it against the parsed AST and the schema, the same way a type-checker proves a program compiles rather than guessing.
How the correctness layer adds additional verification
That’s the distinction that makes the output easier to review, as factual checks have been run and the output is either correct, or there’s a bug that it can fix directly. The rest a human can re-verify. On the dilemma of having stopped to hand-write code and approving it faster than humanly possible to check, you can also read more at You Are the Trust Layer.
[!note] There’s another factor, being wrong
Bare agent use might be cheap, but only until they’re wrong, and then the cost is unbounded.
Improvements for Better Usage of Tokens
Altimate, or data engineering agents that have deterministic functions and integrated understanding of how to work, can help you save tokens and be token lean (the opposite of [[tokenmaxxing]], which is popular on Twitter/X, using as many tokens as possible and having an agent running at all times). Because in large enterprises, token costs are a real budget point.
To slow down the tokens, an easy trick is to instruct the model to use fewer tokens and words itself - caveman is a good example of that, but you can also add a singular prompt to your CLAUDE.md, Codex, or model of choice in combination with Altimate Code.
An example of Altimate Code showing a trace of data lineage and a web UI for it.
There’s a second, less obvious cost: the token itself isn’t a stable unit. When Anthropic shipped Opus 4.7, the same prompt that cost X tokens on 4.6 started costing roughly 1.4X (same input, same answer, more tokens, same price per token).
Altimate on The Great Token Heist of ‘26 makes the case that “cost-per-token is the wrong number to optimize”, since the meter itself can move with a vendor’s next model update, and what we should track instead is cost-per-task. I fully agree, and this is where deterministic function calls work around that volatility by not using a model/tokens for every task, making it less expensive.
Typical Use Cases
In this chapter we go through typical AI agent use cases for data engineering.
There are many of them. You can use them to educate yourself or your team, build production data pipelines, build data apps, and visualize your data in new innovative ways (usually HTML web pages with React and other JavaScript frameworks). But in general, the use cases fit into these approaches:
Start a new project from scratch example: Building a data landscape with more open source.
Extending an existing project or data warehouse: Adding new data pipelines.
Maintaining current setup: Update and verify it still works when changes come in.
Migration: Migrate from one database or tooling to the next.
Finding the Blind Spots: Two similar-sounding IDs might be wrongly used for a join, or missing data in a column that got missed in a nightly load, or anything in between. If agents can do these checks, that would be super beneficial. With more access to CLI, Model Context Layer, and deterministic tooling, these things are truly possible.
Below we go through extending and changing an existing warehouse with a change of column, and using Altimate Code to give us a Blast-radius assessment.
Showcases: Blast-Radius Example
A Blast-radius refers to the potential extent of damage. For example, before you knock down a wall in your house, you want to know if there’s plumbing behind it, electrical wiring within it, or if it’s holding up the floor above.
The same is true for a data warehouse or a data project with lots of ETL. For example, if a data engineer cleans up the table fct_orders by joining orders to order_items and summing order_total. It compiles, the dbt tests pass, nothing errors. But the join changes the grain, so any order with several line items now gets counted once per item, and revenue quietly inflates.
It’s best to know, before you rename a column or add a new join, the downstream (data that comes after the current task) dependencies to the dashboard — that’s what the blast-radius report does.
With Altimate Code we can achieve this. Before any change goes through, it maps out the full impact automatically and produces a detailed blast-radius report with what will break, what’s safe, what needs someone to sign off, and also performs the changes. Here is what this looks like:
Rename and Change Columns and Logic
As an example, in this prepared ecommerce repo with different DWH layers such as staging -> intermediate -> marts, I prompted this request to change unit from cent to dollars:
It recognized the dbt name and invoked dbt-analyze automatically:
It gave me a full Blast-radius report and the impact my changes would have on the project:
Including semantics only, to point out what’s safe and what’s not:
With a fixed order to address breaking changes, semantics and docs, and intentionally untouched:
Notice, I hadn’t said anything about blast analysis or using dbt-analyze — it did it on its own, ran dbt, and analyzed it deterministically.
This shows how Altimate Code looks behind the walls of data engineering, just like blast radius analysis.
[!example] Connect a model to Altimate
Make sure to connect to a model with /connect and choose an existing subscription with API credits, or any other subscription. I used opencode zen for my example, which includes e.g. Opus 4.8.
Correctness Over Confidence
I hope you got a better understanding of why AI agents can be genuinely useful, especially when provided with the right tools and applied with the right discipline.
You’ve also seen how deterministic tooling, purpose-built for data engineering and analytics problems, gets you both better correctness and better token economics than general-purpose agents alone.
Coming back to where we started: not every task needs a level-three agent. A quick chat-phase agent is fine for exploring a dataset or drafting a query you’ll review yourself. But the moment that output touches production or serious work, a dashboard, a nightly job, a number someone makes a decision on, you want the deterministic core underneath it, not just a model that sounds confident.
That’s the gap Altimate Code is built to close. It runs on deterministic functions purpose-built for DE workloads, it’s open-source via the OpenCode TUI, and for teams wanting more, there’s Altimate Studio — a paid, multi-agent platform with extras like warehouse cost optimization, dbt development acceleration, and migration tooling.
Check out Altimate Code, it’s free and open-source. Give them a star if you like them, and find more information on their docs and new website.
Neste episódio do Tecnopolítica, gravado durante o Fórum da Internet no Brasil (FIB 2026), em Belém do Pará, Sérgio Amadeu entrevista Julice Salvagni, pesquisadora dedicada aos estudos sobre o mundo do trabalho, plataformas digitais e transformações nas relações laborais. Sua trajetória é marcada por pesquisas sobre trabalho plataformizado, precarização, organização dos trabalhadores e os impactos das plataformas digitais sobre o emprego e os direitos sociais.
Durante a conversa, eles discutem o estado do trabalho plataformizado no Brasil, as mudanças promovidas pelas plataformas digitais nas relações de trabalho, os desafios para a regulação desse modelo, as estratégias de organização dos trabalhadores e as perspectivas para a proteção de direitos em um cenário de crescente digitalização da economia.
Neste episódio do Tecnopolítica, gravado durante o Fórum da Internet no Brasil (FIB 2026), em Belém do Pará, Sérgio Amadeu entrevista Antonio Terceiro, desenvolvedor de software livre, integrante da comunidade Debian e pesquisador com ampla atuação em infraestrutura digital, colaboração em projetos abertos e desenvolvimento de tecnologias livres. Sua trajetória é marcada pela participação em comunidades de software livre e pela defesa de modelos colaborativos de produção tecnológica baseados no compartilhamento de conhecimento e na autonomia digital.
Durante a conversa, eles discutem como atua a comunidade de software livre, sua organização, formas de colaboração e os desafios enfrentados para manter projetos essenciais que sustentam grande parte da infraestrutura da internet.
Thanks Antigravity for sponsoring this video! Get 25% off the A1 at https://geni.us/lQlFcj for a limited time, and get 20% off accessories during Prime Day! Also, the first 25 people get a free flight battery and a double-lens replacement kit with their A1 purchase.
MKBHD Merch: http://shop.MKBHD.com
Playlist of MKBHD Intro music: https://goo.gl/B3AWV5
System76 has officially released COSMIC 1.1.0, bringing a host of exciting improvements to their Rust-powered desktop environment. System76 has officially released COSMIC 1.1.0, the latest version of their exciting Rust-based desktop environment. This solid update brings many practical improvements across the board, making COSMIC even more polished and enjoyable to use. I have been following...
Shotcut 26.6 brings powerful High Dynamic Range preview, restored external monitor support, and several useful improvements. A new version of the popular free and open-source video editor Shotcut 26.6.25 is now available. This release brings excellent HDR (High Dynamic Range) preview and export capabilities, brings back the long-missing external monitor support using a system display,...
Neste episódio do Tecnopolítica, gravado durante o Fórum da Internet no Brasil (FIB 2026), em Belém do Pará, Sérgio Amadeu entrevista Flávia Lefèvre, advogada, especialista em direitos digitais e telecomunicações, integrante do Comitê Gestor da Internet no Brasil (CGI.br) e uma das mais reconhecidas vozes na defesa do interesse público nas políticas de comunicação e internet no país. Sua trajetória é marcada pela atuação em temas relacionados à regulação das telecomunicações, neutralidade da rede, proteção de dados e governança democrática da internet.
Durante a conversa, eles discutem as recentes movimentações da Agência Nacional de Telecomunicações (Anatel) para ampliar sua influência sobre a regulação da internet brasileira. O debate aborda os diferentes modelos de governança da rede e as disputas institucionais em torno de quem deve formular, implementar e fiscalizar as políticas relacionadas ao ambiente digital no Brasil.
Neste episódio do Tecnopolítica Conjuntura, Gabriel de Moraes e Sérgio Amadeu comentam duas notícias que revelam como a inteligência artificial e a infraestrutura digital se tornaram temas centrais da disputa geopolítica contemporânea.
De um lado, a decisão do TCU que determinou a revisão de contratos de estatais brasileiras com a Amazon Web Services (AWS), levantando preocupações sobre soberania digital, armazenamento de dados públicos e dependência tecnológica.
De outro, a crise envolvendo o governo Trump, a Amazon e a Anthropic, que evidencia como os modelos avançados de IA passaram a ser tratados como ativos estratégicos de segurança nacional, sujeitos a restrições de acesso e disputas entre Estados e corporações.
O que está em jogo quando dados, nuvens computacionais e inteligência artificial se tornam recursos estratégicos? Como a concentração de poder tecnológico afeta a autonomia dos países?
👥 Apresentadores
Sérgio Amadeu é sociólogo, professor da UFABC e pesquisador do CNPq, com atuação destacada na defesa da democratização da comunicação e da soberania tecnológica. Autor de livros e artigos, é referência em debates sobre privacidade, software livre e cultura digital.
Gabriel de Moraes é mestrando e pesquisador do Laboratório de Tecnologias Livres da UFABC (LabLivre), integra a equipe do Podcast Tecnopolítica e coordena o Grupo Avançado de Tecnologias para Movimentos Sociais (GATMOB-UFABC).
📌 Equipe
Coordenação e autoria dos podcasts: Sérgio Amadeu da Silveira
Criação de arte e edição: Tutti Marketing
Conteúdos e divulgação: Tutti Marketing e Gabriel Boscardim de Moraes
🔗 ACESSE OS CURSOS NO PORTAL DO TECNOPOLÍTICA: https://tecnopolitica.blog.br/
Instagram: https://www.instagram.com/podtecnopolitica/
Here’s a quick rundown of the 10 quick tips after you finish installing a brand new Fedora 44 workstation edition. In this article, we will talk about a few post-install tips for Fedora 44 workstation edition. These are a good starting point if you are installing a fresh Fedora 44 workstation edition for all user...
Here’s are the quick steps on how you can upgrade to the Fedora 44 version. Fedora 44 is officially available for download and the upgrade channels are now available. This release brings the latest and greatest GNOME 50 desktop for workstation editions, refinements to KDE Plasma desktop and more updates. If you are trying to...
Canonical is bringing thoughtful, local-first AI to Ubuntu – enhancing accessibility, enabling intelligent agents, and keeping user privacy and open source values at the core. As we move through 2026, large language models (LLMs) and AI tools have become ubiquitous across the tech industry. Adoption varies widely – some projects dive in headfirst, while others...
Xubuntu 26.04 LTS is here – a fast, lightweight, and beautiful release featuring Xfce 4.20 and special 20th anniversary wallpapers. Xubuntu 26.04 LTS codenamed ‘Resolute Raccoon’ released on April 23, 2026. This lightweight flavour of Ubuntu brings the stable Xfce 4.20 desktop along with three years of support until April 2029. It celebrates 20 years...
We round up the best new features of the upcoming fedora 44 workstation edition release. Fedora 44 is released on April 28, 2026. This significant release brings the latest and greatest GNOME 50 to Workstation, Linux kernel 6.19, and many practical updates across desktops and tools. It balances new technology with excellent usability, making it...
Ubuntu 26.04 LTS codenamed “Resolute Raccoon” brings exciting improvements in desktop experience, security, and hardware support for the next five years. Ubuntu 26.04 LTS codenamed “Resolute Raccoon” released on April 23, 2026. This is the latest long-term support release that brings solid improvements in security, desktop experience, and hardware support. This release, will be receiving...
OpenShot 3.5 is here with major speed and smoothness upgrades that make video editing feel much more responsive and enjoyable. The free and open source video editor OpenShot 3.5 arrives with major speed, smoothness, and power improvements. This is one of the biggest releases in its 18-year history. A new default timeline, 35% overall performance...

 Login